
使用 ExecuTorch 在 Arm® 边缘设备上优化流式语音识别
原题Optimizing Streaming Speech Recognition on Arm® Edge Devices with ExecuTorch
推荐理由Arm 联合比较流式语音的分块、精度和专用内核,提供性能分析证据。端侧团队可学习如何同时考虑识别准确率、响应延迟和设备负载。
读前速览
Arm 工程师展示了 ExecuTorch 结合 SME2 加速如何在边缘设备上实现高效的流式语音识别,并提供了通过选择分块大小与精度来平衡准确率与延迟的实用指南。
流式 ASR 必须在部署时的分块大小下评估,而非依赖批量准确率
批量准确率无法预测流式质量;Qwen3-ASR-1.7B 在使用 2.4 秒分块评估时 WER 上升了 77%。更长的分块能提升最终转录准确率(FP16 的 WER 从 80 ms 到 1,120 ms 由 15.2% 降至 11.5%),但会增加响应延迟。
ExecuTorch 通过 XNNPACK 和 KleidiAI 将 PyTorch 模型连接到优化的 Arm CPU 内核
导出流水线将符合条件的算子委托给 XNNPACK,后者为 Arm CPU 选择 KleidiAI 微内核。SME2 扩展了矩阵乘法的指令集,启用后可为 FP16 和 INT8 QC8W 的 GEMM 运算提供 SME2 优化路径。
SME2 为边缘设备上的流式 ASR 带来显著的处理余量
在 Pixel 11 的中核 CPU 上,SME2 使整段录音的处理时间在 FP16 下缩短 2.12 倍,在 QC8W 下缩短 1.61 倍,实时因子分别达到 0.19 和 0.13。这为持续转录期间的其他 CPU 工作和热管理留出了容量。
通过 ETDump 和 Arm Streamline 进行性能分析,揭示 GEMM 是主要加速来源,数据搬运是下一个瓶颈
ETDump 显示 GEMM 时间从 8.2→3.1 s(FP16)和 4.1→2.0 s(QC8W)下降,但其占总时间的比例从 84%→67% 和 78%→62% 下降。数据搬运的相对占比从约 8%→17% 增长,限制了进一步加速,并指明了优化目标。
开发者应根据应用需求联合选择分块大小与精度
对于 13% 的 WER 上限,FP16 和 QC8W 在 320、560 和 1,120 ms 分块下均符合要求。对于 800 ms 的延迟预算,320 ms 和 560 ms 配置同时满足两项约束。文章提供了一个将主机端 WER 与设备端延迟估算配对的实用决策框架。
完整摘要
本案例研究在 Google Pixel 11 上使用 ExecuTorch、XNNPACK 和 Arm KleidiAI 内核评估 Nemotron 3.5 流式 ASR。作者在四种分块大小(80–1,120 ms)和三种精度(FP32、FP16、INT8 QC8W)下测量词错误率,发现更长的分块能提升最终转录准确率,FP16 与 FP32 相当,而 QC8W 仅增加 0.2–0.3% 的 WER。启用 SME2 后,FP16 处理时间下降 2.12 倍(9.79→4.61 s),QC8W 下降 1.61 倍(5.20→3.24 s),实时因子分别达到 0.19 和 0.13。ETDump 性能分析显示 GEMM 是主要加速来源,而数据搬运成为新的瓶颈。Arm Streamline 确认了 SME2 内核的选择(SME 利用率为 38–54%)。文章为开发者提供了一个实用框架,可根据准确率目标或延迟预算联合选择分块大小与精度。
目录 · 9 节
精选项目Featured projects
当你对着设备说话时,你会期待文字随着你说话逐渐显示出来。这使得流式自动语音识别(ASR)与批量转录面临不同的挑战:在批量转录中,模型开始处理前就能获得完整录音。批量处理的高准确率未必能延续到流式处理中。一项跨模型 ASR 研究展示了这种差距。在测试的模型中,Qwen3-ASR-1.7B 的批量处理准确率最高,但在使用 2.4 秒音频块进行评估时,其词错误率(WER)上升了 77%。When you’re speaking to a device, you expect text to appear as you talk. That makes streaming automatic speech recognition (ASR) a different challenge from batch transcription, where the model has the complete recording before it starts. Strong batch accuracy does not necessarily carry over into streaming. One cross-model ASR study illustrates this gap. Qwen3-ASR-1.7B achieved the best batch accuracy among the models tested, but its word error rate (WER) rose by 77% when evaluated with 2.4-second audio chunks.
在该研究的跨模型流式对比中(表 5),NVIDIA® Nemotron™ Speech Streaming 0.6B 在以 560 毫秒音频块为单位运行时,平均流式 WER 最低。这项对比指出了一个关键点:必须按照部署时使用的音频块处理节奏来衡量准确率。In that study’s cross-model streaming comparison (Table 5), NVIDIA® Nemotron™ Speech Streaming 0.6B had the lowest average streaming WER when operating over 560 ms audio chunks. The comparison makes a critical point: accuracy must be measured at the chunk cadence used in deployment.
本案例研究将较新的多语言模型 Nemotron 3.5 从 PyTorch 部署到 ExecuTorch,并分析其在 Google Pixel 11 上的设备端执行情况。我们探讨精度和分块大小如何影响流式处理质量、音频在单个推理线程下需要多少处理时间、工作负载的时间都花在了哪里,以及运行了哪些原生内核。我们的目标是提供一种同时评估准确率和延迟的实用方法。This case study takes the newer, multilingual Nemotron 3.5 from PyTorch to ExecuTorch and profiles its on-device execution on a Google Pixel 11. We ask how precision and chunk size change streaming quality, how much processing time the audio requires with one inference thread, where the workload spends its time, and which native kernels run. The goal is a practical way to evaluate accuracy and latency together.
在这篇博客文章中,你将了解到:In this blog post, you will learn:
- ExecuTorch 如何将 PyTorch 模型与优化后的 Arm CPU 内核相连接。How ExecuTorch connects PyTorch models to optimized Arm CPU kernels.
- 为什么流式 ASR 需要单独进行质量评估,以及更长的分块如何以增加延迟为代价提升最终转录文本的准确性。Why streaming ASR needs its own quality evaluation, and how longer chunks improve final-transcript accuracy at the cost of higher latency.
- Arm 可扩展矩阵扩展 2(SME2)如何通过 FP16 和采用逐通道权重(QC8W)的 INT8 量化,缩短 ASR 总处理时间。How Arm Scalable Matrix Extension 2 (SME2) reduces total ASR processing time with FP16 and INT8 quantization using per-channel weights (QC8W).
- 如何结合模型算子耗时与原生内核采样数据来理解性能并识别尚存的瓶颈。How to combine model operator timings and native kernel samples to understand performance and identify remaining bottlenecks.
- 如何同时选择块大小和精度,以满足准确率和延迟目标。How to choose chunk size and precision together to meet your accuracy and latency targets.
从 PyTorch 模型到 CPU 指令From PyTorch model to CPU instructions
ExecuTorch 是 PyTorch 的边缘推理框架,提供导出工具和轻量级运行时。导出流程会为推理准备模型,并生成设备运行时可加载和执行的 .pte 文件。ExecuTorch is PyTorch’s edge inference framework, with export tools and a lightweight runtime. The export process prepares the model for inference and produces a .pte file that the device runtime can load and execute.
受支持的运算会委托给 XNNPACK(一款 CPU 推理库)执行。在 Android™ 上,XNNPACK 可以从 Arm® KleidiAI™ 软件中选择微内核:这些是小型优化例程,用于执行矩阵运算中的内部计算。未委托给 XNNPACK 的算子则使用 ExecuTorch 的可移植 CPU 内核执行。Supported operations are delegated to XNNPACK, a CPU inference library. On Android™, XNNPACK can select microkernels from Arm® KleidiAI™ software: small, optimized routines that perform the inner matrix calculations. Operators not delegated to XNNPACK run using ExecuTorch’s portable CPU kernels.

图 1. 从模型导出到 CPU 指令。Figure 1. From model export to CPU instructions.
SME2 扩展了 Arm 指令集,可加速矩阵计算,包括通用矩阵乘法(GEMM)。在采用 SME2 的 Arm C1 CPU 集群实现中,矩阵单元由 CPU 集群中的各个核心共享,而 KleidiAI 提供了使用该单元执行受支持运算的微内核。在构建中启用 SME2 后,即可使用这些执行路径。不过,需要进行原生性能分析才能确认实际运行了哪些内核。SME2 extends Arm’s instruction set to accelerate matrix calculations, including general matrix multiplication (GEMM). In the Arm C1 CPU cluster implementation with SME2, the matrix unit is shared by cores in the CPU cluster, and KleidiAI provides microkernels that use it for supported operations. Enabling SME2 in a build makes those paths available. However, native profiling is needed to show which kernels actually ran.
单个流式调用包含的内容What one streaming call contains
Nemotron 3.5 是一款采用 RNN-T 架构的多语言流式 ASR 模型,由三个部分组成:Nemotron 3.5 is a multilingual streaming ASR model built around an RNN-T architecture with three parts:
- 编码器使用 FastConformer 注意力层和卷积层来表示音频。The encoder uses FastConformer attention and convolution layers to represent the audio.
- 预测器使用 LSTM 表示已生成词元的历史记录。The predictor uses an LSTM to represent the history of emitted tokens.
- 连接器使用一个小型前馈层,将编码器的音频表示与预测器的令牌历史表示结合起来,并预测下一个令牌。它还可以输出一个空白符,从而将解码推进到下一个音频位置。The joiner uses a small feedforward layer to combine the encoder’s audio representation with the predictor’s token-history representation and predict the next token. It can also produce a blank, which advances decoding to the next audio position.
前端将音频转换为对数梅尔特征向量,每 10 毫秒生成一个向量。编码器将时间位置的数量缩减为原来的 1/8,因此其输出每 80 毫秒音频对应一个位置。这样就能用更紧凑的序列表示相同长度的音频。The frontend converts audio into log-mel feature vectors, producing one vector for every 10 ms. The encoder reduces the number of time positions by a factor of 8, so its output has one position for every 80 ms of audio. This creates a more compact sequence representing the same audio duration.
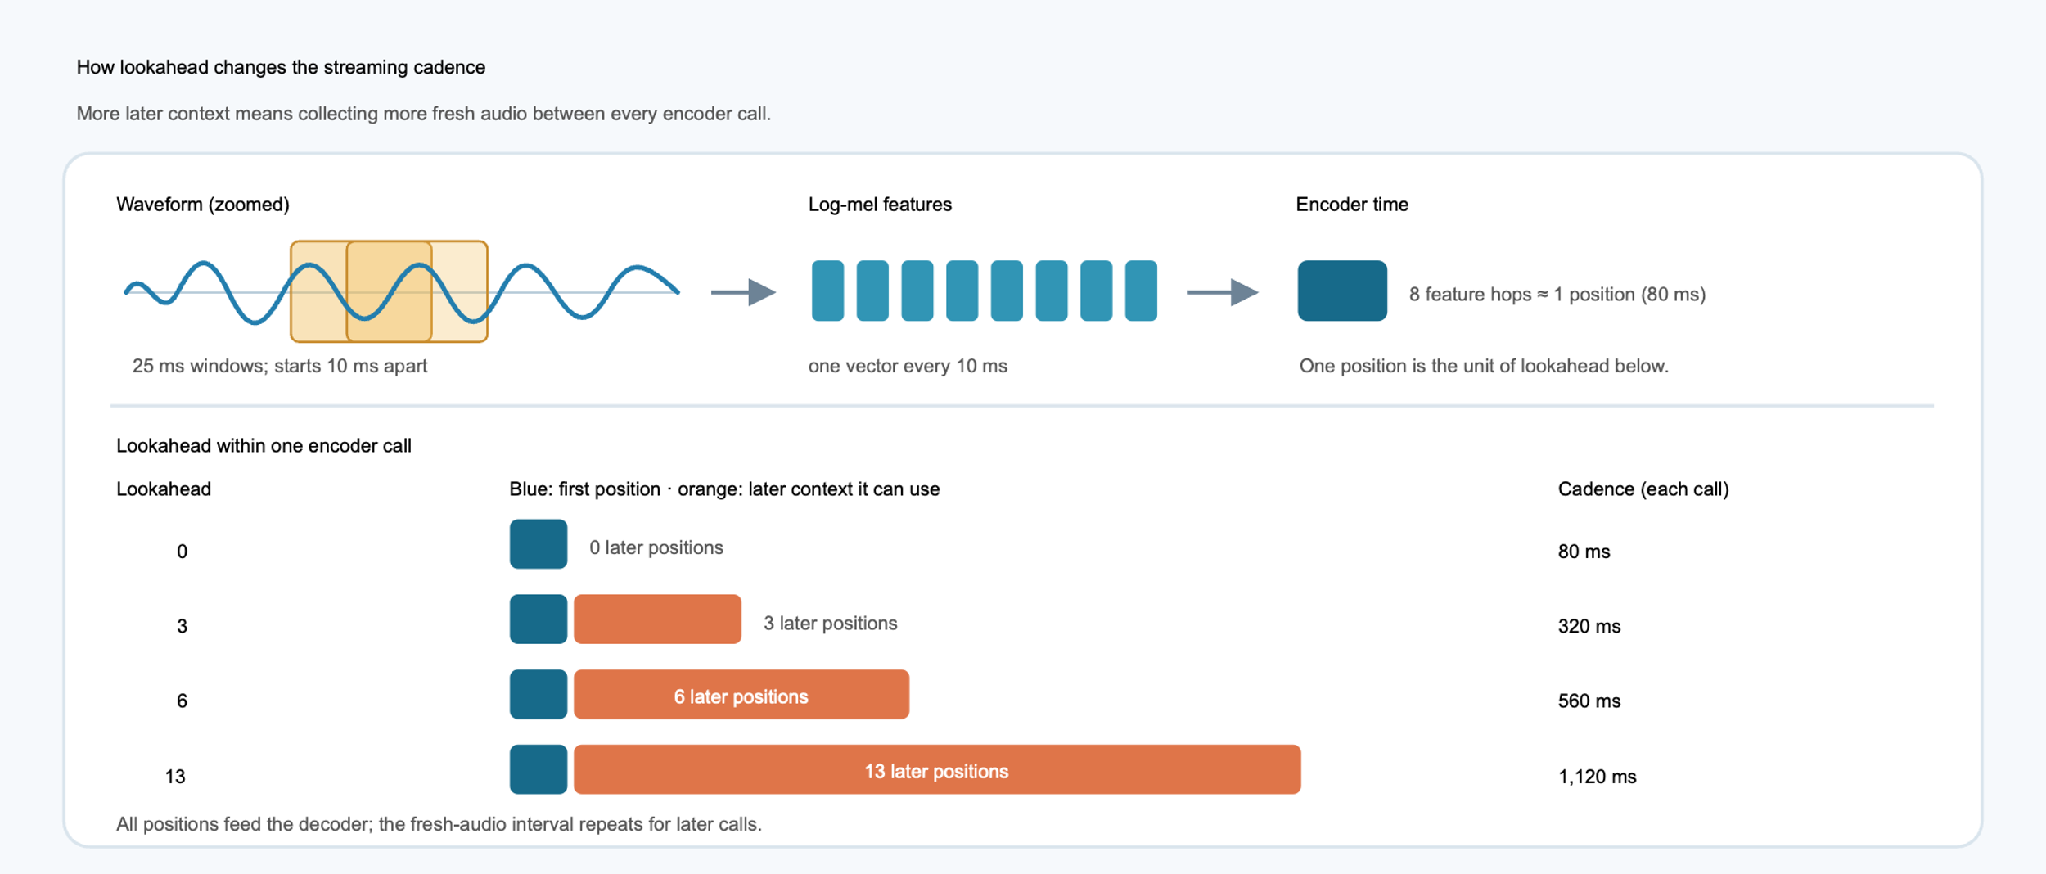
图 2. 从波形窗口到流式编码器位置。Figure 2. From waveform windows to streaming encoder positions.
前瞻量是指一个音频块内可用的未来上下文;分块节奏是指一次调用收集新音频的频率。前瞻量为 13 时,一次调用会收集 1,120 毫秒的音频,并生成 14 个编码器位置。预测器和连接器会处理全部 14 个有效位置,并将这些位置对应的 token 累积到转录文本中。Lookahead is the future context available within a chunk; chunk cadence is how often fresh audio is collected for a call. At lookahead 13, a call collects 1,120 ms of audio and produces 14 encoder positions. The predictor and joiner processes all 14 valid positions, accumulating their tokens into the transcript.
前瞻量为 0、3 和 6 时,分别产生 80、320 和 560 毫秒的音频块。音频块越长,等待首段文本和后续更新的时间就越久;音频采集完成后,预处理和推理还会额外耗时。Lookaheads 0, 3, and 6 give 80, 320, and 560 ms chunks. Longer chunks increase the wait for the first text and subsequent updates; preprocessing and inference add time after audio collection.
同时选择分块大小和精度Choose chunk size and precision together
我们使用 ExecuTorch 运行时及其 XNNPACK CPU 后端,在主机上测量了转录准确率。我们创建了一个本地流式适配器,使用 Hugging Face Open ASR Leaderboard 评测工具链进行数据集准备、转录文本规范化和 WER 评分。We measured transcription accuracy on the host using the ExecuTorch runtime with its XNNPACK CPU backend. We created a local streaming adapter that uses the Hugging Face Open ASR Leaderboard evaluation harness for dataset preparation, transcript normalization, and WER scoring.
我们在四种分块大小下评估了 FP32、FP16 和 INT8。INT8 规格为 QC8W,它针对符合条件的线性运算使用动态 INT8 激活值和按通道量化的 INT8 权重,并输出 FP32。We evaluated FP32, FP16, and INT8 at four chunk sizes. The INT8 specification is QC8W which uses dynamic INT8 activations and per-channel INT8 weights for eligible linear operations, with FP32 outputs.

图 3. 四个语料库中流式 WER 与分块大小的关系。Figure 3. Streaming WER versus chunk size across four corpora.
上图中的每个点均涵盖来自 LibriSpeech Other(LS Other)、AMI Cleaned、Earnings22 和 VoxPopuli Cleaned AA 数据集的 14,019 条话语。WER 是四个语料库中的总词语错误数除以参考文本总词数所得的比值。Each point on the above figure covers 14,019 utterances from LibriSpeech Other (LS Other), AMI Cleaned, Earnings22, and VoxPopuli Cleaned AA datasets. WER divides total word errors by total reference words across all four corpora.
较长的分块有助于提高最终转录文本的准确率。分块长度从 80 毫秒增至 1,120 毫秒时,FP16 的 WER 从 15.2% 降至 11.5%,QC8W 则从 15.5% 降至 11.7%。FP16 的表现基本与 FP32 相当,各种分块长度下的差异均小于 0.03 个百分点,因此我们不再将 FP32 纳入后续性能分析。QC8W 仍保持较高的准确率,相较于 FP32,WER 增加了 0.21–0.31 个百分点。Longer chunks improve final-transcript accuracy. From 80 to 1,120 ms, FP16 WER falls from 15.2% to 11.5%, and QC8W from 15.5% to 11.7%. FP16 essentially matches FP32, differing by less than 0.03 percentage points at every chunk size, so we exclude FP32 from further performance analysis. QC8W preserves strong accuracy, adding 0.21–0.31 percentage points of WER relative to FP32.
这些主机端 WER 结果可为精度和前瞻选择提供依据。不过,它并不衡量文本在设备上显示所需的时间。These host WER results inform precision and lookahead choices. However, it does not measure how long it takes for text to appear on the device.
在边缘设备上测试实时预算Test the real-time budget on an edge device
我们使用一台 Google Pixel 11 智能手机处理了一段 24.9 秒的录音,采用 1,120 毫秒的分块,并将一个推理线程固定在中核 CPU 上。我们选择中核 CPU,作为系统上持续流式处理工作负载的代表性目标。我们测试了 ExecuTorch 1.3.1 的两个构建版本,分别启用和禁用 SME2 支持。两个构建版本均保留了 XNNPACK 和 KleidiAI,并使用相同的模型产物。We processed a 24.9-second recording on a Google Pixel 11 smartphone device using 1,120 ms chunks and one inference thread pinned to a mid-core CPU. We chose the mid-core CPU as a representative target for a sustained streaming workload on the system. We tested two builds of ExecuTorch 1.3.1, toggling SME2 support on and off. Each build retained XNNPACK and KleidiAI, and used identical model artifacts.
每种配置均进行了两次预热和一次计时跟踪运行。总耗时涵盖对已加载录音的处理过程,从音频预处理一直到最终的去分词。Each configuration had two warm-ups and one measured tracing run. Totals cover processing the loaded recording from audio preprocessing through final detokenization.

图 4. 禁用和启用 SME2 时处理完整录音所需的时间。Figure 4. Whole-recording processing time with SME2 disabled and enabled.
SME2 大幅缩短了处理时间:FP16 从 9.79 秒降至 4.61 秒(快 2.12 倍),QC8W 从 5.20 秒降至 3.24 秒(快 1.61 倍)。SME2 substantially reduces processing time: FP16 falls from 9.79 to 4.61 seconds (2.12x faster), and QC8W from 5.20 to 3.24 seconds (1.61x faster).
无论是否启用 SME2,两种配置处理这段录音所需的时间都远短于其音频时长。将处理时间除以音频时长后,我们计算出 FP16 的实时系数为 0.19,QC8W(启用 SME2)为 0.13。即使只有一个推理线程,这也能提供充足的处理余量。音频必须先到达才能解码,因此这部分余量无法消除收集音频块所造成的延迟。不过,它能为音频块之间的其他 CPU 工作留出处理能力,也有助于在持续转录期间控制热负载。With and without SME2, both process the recording in much less time than its audio duration. Dividing the processing time by the audio duration we calculate real-time factors of 0.19 for FP16 and 0.13 for QC8W (with SME2 on). This provides substantial processing headroom with only a single inference thread. Audio still has to arrive before it can be decoded, so this headroom does not remove the chunk-collection delay. But it leaves capacity for other CPU work between chunks and can help manage thermal load during sustained transcription.
使用 ETDump 找出瓶颈Find the bottleneck with ETDump
ETDump 会记录 ExecuTorch 算子的事件和耗时。为了了解 2.12 倍 FP16 和 1.61 倍 QC8W 加速比的来源,我们将编码器、预测器和连接器中的机器学习(ML)算子归为以下几类:ETDump records ExecuTorch operator events and timings. To understand where the 2.12X FP16 and 1.61X QC8W speedups come from, we grouped machine learning (ML) operators across the encoder, predictor, and joiner into categories:
- GEMM(蓝色):矩阵乘法,主要用于编码器的全连接层。GEMM (blue): Matrix multiplication, mainly the encoder’s dense layers.
- 数据移动(橙色):复制、拼接、重复和嵌入查找。Data movement (orange): Copies, concatenation, repeats, and embedding lookup.
- 逐元素(红色):激活、比较及其他逐值操作。Elementwise (red): Activations, comparisons, and other per-value work.
- 卷积和归一化(绿色和紫色):卷积滤波器和归一化算子;在这里,两者都相对较小。Convolution and normalization (green and purple): Convolution filters and normalization operators; both are relatively small here.
- 其他(紫色):剩余的小型计时操作,例如张量创建。Other (violet): Small remaining timed operations, such as tensor creation.
- 开销(灰色):分组算子事件之外的全程运行时间;其中可能包括运行器和框架开销。Overhead (gray): Full-run time outside the grouped operator events; this can include runner and framework overhead.

图 5. 整体运行速度提升背后的操作成本与开销。Figure 5. Operator costs and overhead behind the whole-run speedup.
ETDump 时间是对编码器、预测器和连接器网络的时间求和得出的。加上剩余开销后,即为图 4 所示的完整处理时间。ETDump times are summed across the encoder, predictor, and joiner networks. Adding residual overhead gives the full processing time shown in Figure 4.
GEMM 带来了大部分的加速效果。GEMM drives most of the speedup.
启用 SME2 后,FP16 的 GEMM 耗时从 8.2 秒降至 3.1 秒,QC8W 则从 4.1 秒降至 2.0 秒。GEMM 仍是运行过程中占比最大的部分,不过它在总处理时间中的占比有所下降:FP16 从 84% 降至 67%,QC8W 从 78% 降至 62%。两个构建版本的数据移动耗时大致相同,因此随着 GEMM 加速,数据移动的相对占比有所上升:FP16 从 8% 升至 17%,QC8W 从 9% 升至 17%。这些剩余工作限制了整体加速效果,也为进一步优化指明了方向。Enabling SME2 reduces GEMM time from 8.2 to 3.1 seconds for FP16 and 4.1 to 2.0 seconds for QC8W. GEMM remains the largest part of the run, though its share of total processing time falls from 84% to 67% for FP16 and 78% to 62% QC8W. Data movement takes roughly the same time for both builds, so its relative share grows as GEMM accelerates: from 8% to 17% for FP16 and 9% to 17% for QC8W. This remaining work limits the overall speedup and offers a target for further optimization.
运行了哪些内核?Which kernels ran?
ETDump 可以定位开销较大的算子族,但不会指出执行这些算子族的原生微内核。ETDump locates the expensive operator families, but does not name the native microkernels that execute them.
Arm Streamline 允许我们对原生调用路径进行采样并测量硬件计数器。在 Pixel 11 上,我们测得 FP16 的 SME 利用率为 38.4%,QC8W 的利用率为 53.7%。这表示在每次采集期间,矩阵硬件被分配使用的时间占比;它并不代表峰值算术吞吐量的百分比。我们还对 GEMM 函数进行了采样,以识别每个构建版本所选用的微内核。Arm Streamline allows us to sample native call paths and measure hardware counters. On the Pixel 11, we measured 38.4% SME utilization for FP16 and 53.7% for QC8W. This indicates how much of each capture the matrix hardware was allocated; it is not a percentage of peak arithmetic throughput. We also sampled GEMM functions to identify the microkernels selected by each build.
函数名称揭示了采样到的路径。_sme2_mopa 后缀表示矩阵外积累加例程。NEON 和 I8MM 是控制路径使用的向量指令系列。The function names reveal the sampled paths. The _sme2_mopa suffix denotes a matrix outer-product accumulation routine. NEON and I8MM are the vector instruction families used by the control paths.
| Precision | SME2 | Sampled GEMM paths and functions |
|---|---|---|
| FP16 | True | KleidiAI FP16 SME2
kai_kernel_matmul_clamp_f16_f16p2vlx2_f16p2vlx2_2vlx2vl_sme2_mopa XNNPACK FP16 NEON xnn_f16_gemm_minmax_ukernel_6x16__asm_aarch64_neonfp16arith_cortex_a75 |
| FP16 | False | XNNPACK FP16 NEON
xnn_f16_gemm_minmax_ukernel_6x16__asm_aarch64_neonfp16arith_cortex_a75 |
| QC8W | True | KleidiAI INT8 SME2, FP32 output
kai_kernel_matmul_clamp_f32_qai8dxp1vlx4_qsi8cxp4vlx4_1vlx4vl_sme2_mopa KleidiAI FP32 SME2 kai_kernel_matmul_clamp_f32_f32p2vlx1_f32p2vlx1biasf32_sme2_mopa |
| QC8W | False | KleidiAI INT8 NEON I8MM, FP32 output
kai_run_matmul_clamp_f32_qai8dxp4x8_qsi8cxp4x8_16x4_neon_i8mm |
这些采集结果证实,面向 SME2 的 KleidiAI GEMM 内核在 Pixel 11 上针对 FP16 和 QC8W 均已运行,同时也使用了其他内核路径。在 FP16 构建版本中,部分 GEMM 操作仍使用 NEON。在 QC8W 构建版本中,部分 GEMM 操作仍以 FP32 运行。These captures confirm that SME2-targeted KleidiAI GEMM kernels ran on the Pixel 11 for both FP16 and QC8W, alongside other kernel paths. In the FP16 build, some GEMM operations still use NEON. In the QC8W build, some GEMM operations still run in FP32.
这凸显了该生态系统中的工具缺口。ETDump 展示模型算子的耗时,而 Streamline 对原生函数进行采样,但这两种工具都无法直接关联这两种视图。将各个模型层映射到观测到的内核函数,仍有待未来完成。This highlights a tooling gap in the ecosystem. ETDump exposes model operator timings, while Streamline samples native functions, but neither tool directly connects these views. Mapping individual model layers to the observed kernel functions remains future work.
选择工作点Choosing an operating point
部署需要在精度和分块大小方面权衡响应延迟与准确性。应用可能会从准确性目标或延迟预算入手;以下示例展示了这两种方法。Deployment involves balancing response latency and accuracy across precision and chunk size. An application might start with an accuracy target or a latency budget; the following examples illustrate both approaches.
下方图 6 将主机 WER 结果与 Pixel 11 上启用 SME2 的 FP16 和 QC8W 组件基准测试结果并列展示。灰色刻度标示音频采集完成的时间;虚线段则表示实测的计算延迟。Figure 6 below pairs the host WER results with a Pixel 11 component benchmark for SME2-enabled FP16 and QC8W. Grey ticks mark when audio collection finishes; dotted segments add the measured compute delay.
x 轴表示有条件的首 token 时间估算:音频采集时间加上 encoder–predictor–joiner 序列耗时的中位数。组件基准测试使用合成输入和全新的流状态,每种配置在三轮测试中测量 75 个样本。该估算假设首个输出为文本。The x-axis is a conditional time to first-token estimate: audio collection time plus the median encoder–predictor–joiner sequence time. The component benchmark used synthetic input, fresh stream state, and 75 measured samples per configuration across three rounds. It assumes the first output emits text.

图 6. 启用 SME2 时,WER 与估算的首 token 延迟之间的关系。Figure 6. WER versus estimated first-token latency with SME2 enabled.
以 13% 的词错误率(WER)上限为例,FP16 和 QC8W 在 320、560 和 1,120 毫秒的分块大小下都符合要求。320 毫秒的分块有利于更早响应,FP16 和 QC8W 的 WER 分别为 12.67% 和 12.97%。较长的分块可提升准确率:在 1,120 毫秒时,两者的 WER 分别达到 11.50% 和 11.72%;但需要先接收到更多音频,转录内容才会开始显示。For an illustrative 13% WER ceiling, both FP16 and QC8W qualify at 320, 560, and 1,120 ms chunk sizes. The 320 ms chunks favor earlier responses, with 12.67% WER for FP16 and 12.97% for QC8W. Longer chunks improve accuracy, reaching 11.50% and 11.72%, respectively, at 1,120 ms, but require more audio to arrive before transcripts begin to appear.
在 800 ms 的延迟预算下,320 ms 和 560 ms 两种精度都符合预算,并且低于图示的 13% WER 上限。320 ms 配置更倾向于更快响应,而 560 ms 的准确率更高。在 560 ms 下,FP16 的 WER 为 12.01%,估计延迟为 691 ms;QC8W 的 WER 为 12.26%,延迟为 660 ms。此处,两种 80 ms 配置都未达到 WER 目标。相反,两种 1,120 ms 配置都超出了延迟预算。For an 800 ms latency budget, both precisions at 320 ms and 560 ms fall within the budget and also below the illustrated 13% WER ceiling. The 320 ms configurations favor earlier responses while 560 ms gives better accuracy. At 560 ms, FP16 combines 12.01% WER with an estimated 691 ms delay, while QC8W combines 12.26% with 660 ms. Here, both 80 ms configurations miss the WER target. Conversely, both 1,120 ms configurations miss the latency budget.
结论:这对开发者意味着什么?Conclusion: What does this mean for developers
- 在预期的分块大小下评估流式 ASR。整段录音的准确率无法预测流式处理的质量。在这里,较长的分块能提高最终转录文本的准确率,但也会增加响应延迟。Evaluate streaming ASR at the intended chunk size. Whole-recording accuracy does not predict streaming quality. Longer chunks improve final-transcript accuracy here, while increasing response latency.
- ExecuTorch 将 PyTorch 模型连接到经过优化的 Arm CPU 内核。其导出和运行时流程使 XNNPACK 能够为符合条件的操作选择 KleidiAI 微内核。ExecuTorch connects PyTorch models to optimized Arm CPU kernels. Its export and runtime path lets XNNPACK select KleidiAI microkernels for eligible operations.
- SME2 可提供更多处理余量。加速矩阵运算可缩短 ASR 的耗时,为设备上的其他应用任务或并发工作负载腾出更多空间。SME2 creates more processing headroom. Accelerating matrix work reduces the time spent on ASR, leaving more room for other application tasks or concurrent workloads on the device.
- ETDump 揭示了算子的加速效果和仍然存在的瓶颈。对算子耗时进行分组,可以看出性能提升来自何处,以及数据移动在处理时间中所占比例如何增大。ETDump reveals operator speedups and remaining bottlenecks. Grouping operator timings shows where the gains come from and how data movement becomes a larger share of processing time.
- Streamline 可识别实际运行的原生微内核。原生采样证实选用了 SME2 内核,而硬件计数器则显示矩阵硬件资源的分配情况。Streamline identifies the native microkernels that ran. Native samples confirm selection of SME2 kernels, while hardware counters show matrix hardware allocation.
- 同时选择分块大小和精度。比较不同精度与分块大小的组合,有助于开发者在响应延迟与转录准确性之间,为应用找到合适的平衡。Choose chunk size and precision together. Comparing precision and chunk-size combinations helps developers balance response latency against transcript accuracy for their application.