EmbeddingGemma 2:把多模态检索带到端侧
原题EmbeddingGemma 2: an open, lightweight multimodal embedding model
读前速览
Google 发布 EmbeddingGemma 2,这是一个 7.4 亿参数的模型,整合了文本、代码、图像、视频和音频嵌入,在其尺寸下实现了最佳性能,支持高效的本地检索与搜索。
多模态统一
EmbeddingGemma 2 将文本、代码、图像、视频与音频整合到单一嵌入空间,支持跨模态搜索与检索。这对从语音备忘录中寻找特定视频片段或用文本查询搜索音频录音尤为有用。
专为本地端性能优化
模型设计运行在有限资源的消费级硬件上,文本任务仅需约 191MB 活跃内存,完整多模态模型也仅需约 567MB,适合边缘计算应用。
存储高效
采用 Matryoshka 表征学习(MRL),模型输出向量可动态从 768 维截断至 128 维,实现最多 6 倍的本地向量数据库存储降低,对低存储容量设备管理大型数据集至关重要。
高性能
尽管体积小(小于 10 亿参数),EmbeddingGemma 2 在 MTEB Code 与 MAEB 等基准测试中均获得领先分数,在多项任务上可与或超越众多更大模型,表明其性价比极高。
扩展上下文窗口
模型支持 8K token 上下文窗口,是上一代的 4 倍,可在本地硬件上直接处理更长数据序列,如最多 5.5 分钟音频或 29 张图像。
完整摘要
EmbeddingGemma 2 是 Google 推出的一款新型多模态嵌入模型,构建在 Gemma 4 架构上,采用 Apache 2.0 许可证发布。该模型拥有 7.4 亿参数,优化用于本地推理,支持最高 8K token 上下文,并采用 Matryoshka 表征学习实现存储高效的向量截断。在代码、视觉与音频基准测试中均取得顶级成绩,并与 Google AI Edge 工具集成,用于实时决策引擎与多媒体搜索应用。
目录 · 3 节
去年,我们推出了 EmbeddingGemma,为高质量文本嵌入提供轻量级选择,帮助你的应用直接在消费级硬件上整理、搜索和关联信息。开发者社区的反响远超我们的预期。下载量已超过 2000 万次,开发者们利用它打造更智能的设备端搜索工具,以及以隐私优先的检索增强生成(RAG)管线。We introduced EmbeddingGemma last year to provide a lightweight option for high-quality text embeddings, to help your apps organize, search, and connect information directly on consumer hardware. The developer community’s response blew past our expectations. With more than 20 million downloads, builders have used it to power smarter on-device search tools and privacy-first retrieval augmented generation (RAG) pipelines.
今天,我们推出 EmbeddingGemma 2,将能力从文本扩展到代码、图像、视频和音频,并将它们统一到共享的嵌入空间中。EmbeddingGemma 2 基于 Gemma 4 架构构建,采用对商业用途宽松的 Apache 2.0 许可证发布,拥有 7.4 亿个参数,非常适合在设备端进行推理。它可以根据语音备忘录查找特定视频片段,也可以根据文本查询搜索数小时的音频录音,所有处理都由一个原生多模态模型完成。Today, we’re launching EmbeddingGemma 2, expanding beyond text to unify code, images, video, and audio in a shared embedding space. Built on the Gemma 4 architecture and released under a commercially permissive Apache 2.0 license, EmbeddingGemma 2 has 740 million parameters, making it optimal for on-device inference. It can help find a specific video clip from a voice memo, or search through hours of audio recordings based on a text query, all processed by a single, natively multimodal model.
EmbeddingGemma 2 与 Gemini Embedding 模型采用相同的技术构建,具有以下特点:Built from the same technology as Gemini Embedding models, EmbeddingGemma 2 is:
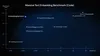
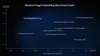
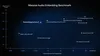
- 同规模中的最佳表现:在其参数规模下,在 MTEB(大规模文本嵌入基准)Code 和 MAEB(大规模音频嵌入基准)等基准测试中,成绩领先于参数量低于 10 亿的多模态嵌入模型;同时,在文本、视觉和音频任务中,表现媲美或优于许多更大型的模型。Best-in-class for its size: Achieves leading scores among sub-1B multimodal embedders for its size across benchmarks like MTEB (Massive Text Embedding Benchmark) Code and MAEB (Massive Audio Embedding Benchmark), while matching or outperforming many larger models across text, vision, and audio tasks.
- 采用模块化设计:纯文本工作负载所需参数量低至 270M;还可选配视觉(170M)和音频(300M)编码器,以实现完整的多模态支持。Modular by design: Requires as little as 270M parameters for text-only workloads with optional vision (170M) and audio (300M) encoders for full multimodal support.
- 存储效率高:借助俄罗斯套娃表示学习(MRL),开发者可以动态地将输出向量从 768 维截短至 512、256 或 128 维。这能使本地向量数据库的存储空间和内存占用最多减少 6 倍。Storage-efficient: Using Matryoshka Representation Learning (MRL), developers can dynamically truncate output vectors from 768 dimensions down to 512, 256, or 128 dimensions. This provides up to 6x storage reduction for local vector databases and memory usage.
- 针对设备端性能进行了优化:可在严格的资源限制下高效运行。经过量化后,在 Google Pixel 11 Pro 上,EmbeddingGemma 2 仅需约 191 MB 的活动 RAM 即可运行纯文本权重,完整多模态模型则需约 567 MB。Optimized for on-device performance: Runs efficiently within tight resource constraints. With quantization, on a Google Pixel 11 Pro, EmbeddingGemma 2 requires as little as ~191MB active RAM for text-only weights and ~567MB for the full multimodal model.
- 扩展上下文已就绪:具备 8K token 上下文窗口(是 EmbeddingGemma 1 的 4 倍),可在本地硬件上直接处理最长 5.5 分钟的音频、29 张图像、58 帧视频,或这些内容的交错组合。Extended context ready: Features an 8K token context window (4x larger than EmbeddingGemma 1), allowing it to process up to 5.5 minutes of audio, 29 images, 58 video frames, or interleaved combinations thereof directly on local hardware.
在代码、视觉和音频方面实现顶尖质量Achieving top-tier quality for code, vision, and audio
EmbeddingGemma 2 保持了 EmbeddingGemma 出色的多语言文本表现,同时在代码性能上提升了 9.92 分(MTEB Code 评测中从 68.76 提升至 78.68),非常适合用于本地代码库索引、语义代码搜索和编程智能体检索。在图像、视频、文档和音频领域,它为参数量低于 10 亿的模型树立了参数效率方面的质量新标杆,甚至超越了一些规模是其两倍以上的专用模型。EmbeddingGemma 2 matches the strong multilingual text performance of EmbeddingGemma while delivering a significant 9.92-point improvement on code performance (in MTEB Code, from 68.76 to 78.68), making it well-suited for local codebase indexing, semantic code search, and coding agent retrieval. Across image, video, documents, and audio, it sets a new standard in quality-per-parameter for sub-1B models and even outperforms some specialist models more than twice its size.
请在 EmbeddingGemma 2 模型卡中查找完整的评估指标和模型信息。Find full evaluation metrics and model information in the EmbeddingGemma 2 model card.
完全在设备端启用语义搜索、路由和检索Enabling semantic search, routing, and retrieval, fully on-device
EmbeddingGemma 2 将强大的能力直接带到了边缘硬件上。在本地生成嵌入有助于保护数据隐私、降低流水线延迟,并让开发者能够构建完全离线运行的跨模态搜索与检索功能。EmbeddingGemma 2 brings robust capabilities directly to edge hardware. Generating embeddings locally helps ensure data privacy, reduces pipeline latency, and empowers developers to build cross-modal search and retrieval that works entirely offline.
与 Gemma 4 等生成式模型搭配使用时,EmbeddingGemma 2 可支持端侧 RAG 流水线,理解复杂的多模态数据。由于 EmbeddingGemma 2 基于 Gemma 4 构建,并与其共用文本分词器和音频编码器,开发者可以在统一的流水线中同时运行这两个模型,从而降低两者合计的内存占用。When paired with generative models such as Gemma 4, EmbeddingGemma 2 enables on-device RAG pipelines that understand complex multimodal data. Because EmbeddingGemma 2 is built on Gemma 4 and shares its text tokenizer and audio encoder, developers can run both models together in a unified pipeline with a lower combined total memory footprint.
使用文本或图像,根据语义相似度在媒体库中查找最匹配的内容。试试 Google AI Edge Gallery 的即时媒体搜索功能。Use text or an image to find the top matches in your media library based on semantic similarity. Try it in Google AI Edge Gallery’s Instant Media Search.
使用文本或音频查询定位视频中的特定时刻。试试 Google AI Edge Gallery 的 Video Moments Finder。Locate specific moments in video using text or audio queries. Try it in Google AI Edge Gallery’s Video Moments Finder.
将 EmbeddingGemma 2 用于本地文件检索,并搭配 Gemma 4 进行上下文推理。欢迎在 Google AI Edge Foresight 应用中体验。Pair EmbeddingGemma 2 for local file retrieval with Gemma 4 for contextual reasoning. Try it in the Google AI Edge Foresight app.
通过 MediaPipe Decision Task API 利用多模态上下文构建实时决策引擎,实现分类、路由和预测能力。Create real-time decision engines leveraging multimodal context for classification, routing, and predictive capabilities via the MediaPipe Decision Task API.
要了解如何使用 LiteRT 构建端侧搜索和 RAG 系统,请阅读 Google AI Edge 博客文章。To learn how to build on-device search and RAG systems with LiteRT, read the Google AI Edge blog post.
EmbeddingGemma 2 入门Getting started with EmbeddingGemma 2
我们与以下合作伙伴密切合作,确保 EmbeddingGemma 2 在你的构建环境中开箱即用:We worked closely with the following partners to ensure EmbeddingGemma 2 works immediately where you build:
- 下载模型:在 Hugging Face 和 Kaggle 上查找模型权重,Gemini Enterprise Agent Platform Model Garden 即将提供相关模型。对于针对设备端优化的模型,请访问 Hugging Face 上的 LiteRT Community。Download the models: Find the model weights on Hugging Face and Kaggle, with Gemini Enterprise Agent Platform Model Garden availability coming soon. Visit LiteRT Community on Hugging Face for models optimized for on-device.
- 设备端部署:使用 Google AI Edge MediaPipe 开发跨平台应用,轻松实现嵌入、检索和决策任务;也可使用 LiteRT 集成自定义模型。使用 transformers.js 或 WebGPU 构建浏览器应用。
- 使用你最喜欢的开发工具:借助 transformers、sentence-transformers、MLX、vLLM、llama.cpp、SGLang、Ollama 和 LMStudio 高效地提供模型服务。使用 Qdrant 存储嵌入向量。
- 微调:请遵循 Unsloth 提供的指南,根据你的使用场景微调 EmbeddingGemma 2。Fine-tuning: Follow guidance by Unsloth for how to fine-tune EmbeddingGemma 2 for your use cases.
探索我们的开发者指南、文档以及推理和微调指南。Explore our developer guide, documentation, and guides for inference and fine-tuning.