
快速、可靠的 A2UI,支持可替换的推理格式
原题Fast, reliable A2UI, with swappable inference formats
推荐理由Google 为 A2UI 引入精简推理格式,让智能体用更少 token 生成可信组件界面。开发者可据 SDK 与评测示例选择速度和控制程度。
读前速览
Google 推出 A2UI Express,一种类 Python 的新推理格式,可将生成式 UI 的 token 用量降低 3 倍、延迟最多降低 3 倍,并展示了 Jev 等决策模型如何为已知屏幕原型实现 80 倍更快的布局选择。
A2UI Express 是一种新的推理格式,相比 Direct JSON 可将 token 用量减少约 3 倍,延迟最多降低 3 倍。
Express 采用类 Python 的按行组织语法,每一行将一个组件赋值给一个变量(该变量即成为组件 ID),参数按照目录 schema 以位置方式传入,数据绑定和事件使用紧凑标记($/ 表示数据模型,Event() 表示动作)。SDK 会将 Express 编译为经过校验的 A2UI JSON 传输消息,因此目录和渲染器保持不变。
可替换的推理格式将模型输出语法与 A2UI 传输协议解耦,使开发者能够为每种用例选择最佳格式。
生成器接受 inference_format_factory 参数(例如 ExpressFormatFactory)。SDK 会根据目录的 JSON schema 自动生成提示词片段和编译器,确保该格式无法描述目录之外的组件或属性。自定义 DSL 只需提供提示词生成器和到 A2UI 消息的转换器。
像 Jev 这样的决策模型(System One)可为具有已知原型的屏幕实现约 80 倍更快的布局决策。
Jev 可在 100–300 ms 内以校准概率回答成批的类型化问题(Choice、Noul、Score)。Apparite(jev2ui)项目演示了一条语法驱动的流水线:一次 Jev 请求解决约 30 个布局问题,代码在约 200 ms 内构建组件树,小型文本模型(gemini-3.5-flash-lite)流式生成文案。在 11 个提示词中,屏幕在 0.8–1.7 s 内完成,且所有运行均产出有效的 A2UI。
评估方法在 51 个任务上比较了四种推理格式(Direct JSON、Express、Atom、Elemental),并分别开启和关闭思考模式。
即使在禁用思考的情况下,Express 的准确率也与 Direct JSON 持平,并实现了最快的推理时间。Atom(Lisp 风格 S 表达式)和 Elemental(自定义 HTML 元素)也经过了测试,但未被选为默认格式。评估基线和规范已发布在 A2UI 仓库中。
实践采用路径:安装 Python 或 TypeScript SDK,传入 ExpressFormatFactory,在关闭思考模式下运行模型,并可选地从目录生成模型技能。
SkillGenerator 会生成一套技能集(每个目录组件对应一项技能),教会任何具备技能能力的模型编写 Express。对于受控生成,开发者可以克隆 jev2ui 示例,定义一份包含引用块问题和项目符号选项的 Markdown 语法,并将 Jev 决策接入 A2UI 组件组装。
完整摘要
文章宣布为 A2UI(Agent-to-UI,智能体到 UI)引入可替换的推理格式,这是一种面向智能体驱动界面的开放协议。新的默认格式 A2UI Express 采用简洁的 Python 风格语法(每行一条语句、位置参数、以变量名作为组件 ID),相比 Direct JSON 可将 token 数量最多减少 3 倍,同时保持完整的表达能力。在 gemini-3.5-flash 上针对 51 个任务的基准测试显示,即使在关闭思考模式的情况下,Express 的准确率也与 Direct JSON 持平,从而实现更快的推理。对于具有预定义布局的屏幕(设置、结账、确认),文章演示了使用 Jev 进行受控生成——Jev 是来自 TypeSafe 的 System One 决策模型,可在 100–300 ms 内回答结构化布局问题;一个示例项目(Apparite)可在 0.8–1.7 s 内渲染完整屏幕。A2UI Agent SDK(Python、TypeScript、Dart)通过一个工厂参数支持 Express,SkillGenerator 可以教会任何模型为给定的组件目录编写 Express。开发者还可以接入自定义 DSL。文章包含代码片段、评估图表,以及规范、SDK 和 Jev2ui 示例仓库的链接。
目录 · 7 节
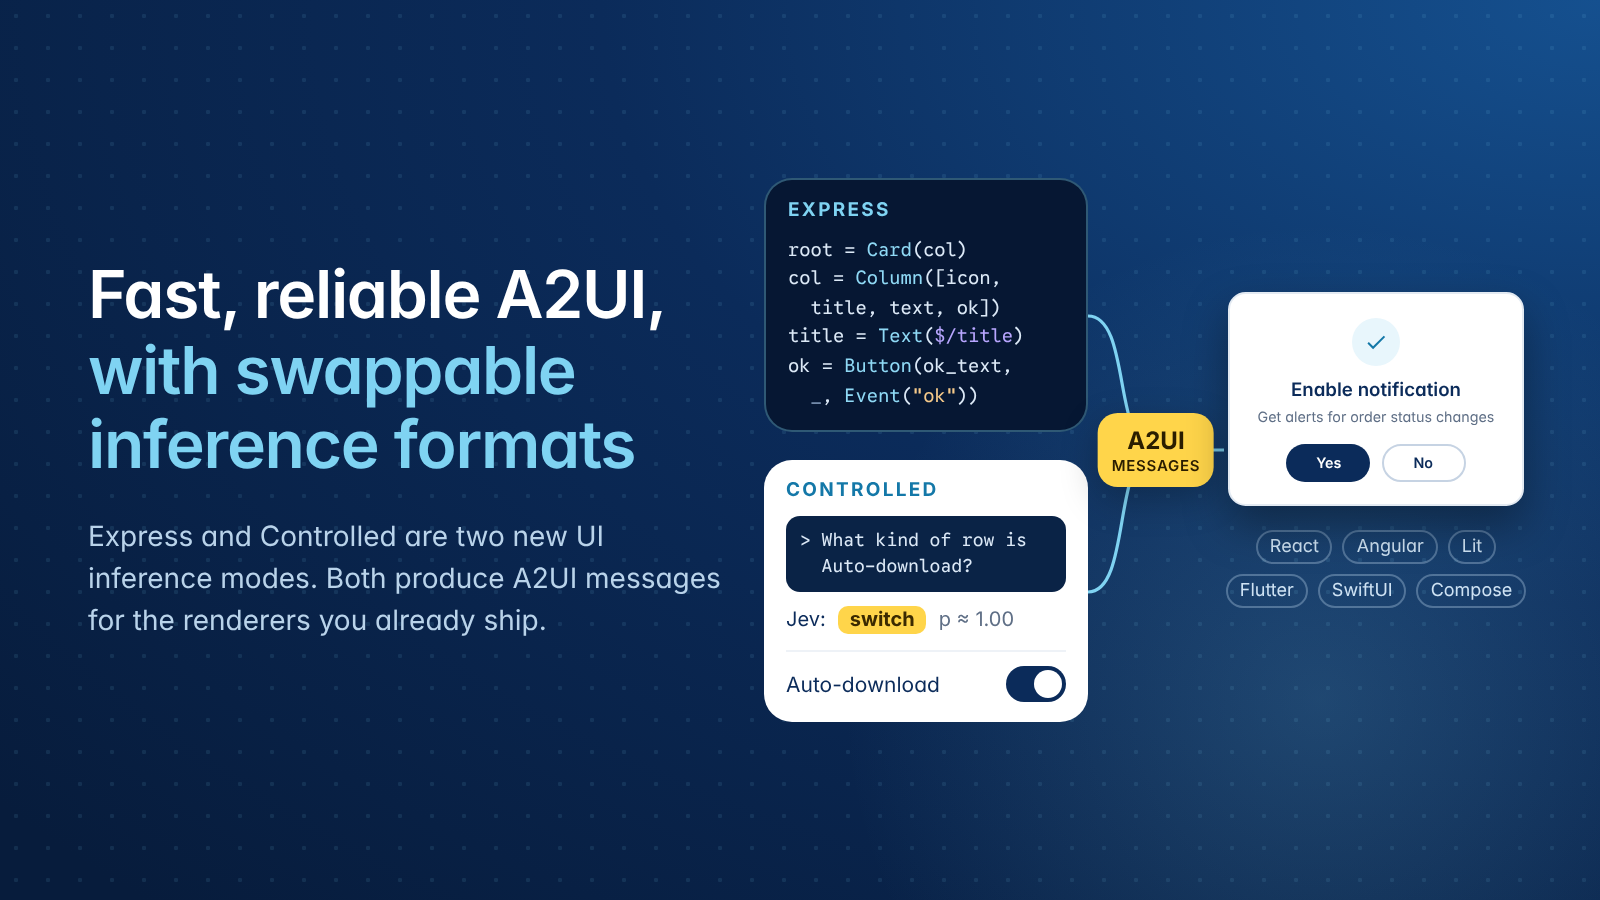
我们听到了你们对 A2UI 和生成式 UI 体验速度的担忧:模型每生成一个界面,用户都要等待。本次发布提供了加速手段,让你可以针对每个界面选择合适的取舍。We've heard your concerns about the speed of A2UI and generative UI experiences: people wait while the model generates each screen. This release gives you levers to make that faster, so you can choose the trade-off that fits each screen.
在此次发布中,我们很高兴推出可切换的推理格式,并分享如何借助 A2UI 使用决策模型的示例,帮助构建更快速、更可靠的生成式 UI 体验。使用我们全新的 A2UI Express 作为推理格式,延迟最高可降低至原来的三分之一;使用 Jev 等决策模型来做布局决策,延迟最高可降低至原来的八十分之一。与 Direct JSON 相比,Express 生成同类 UI 所需的 token 最多可减少三倍。我们将在这篇博客文章中深入介绍详情。With this release, we’re happy to introduce swappable inference formats and share examples on leveraging decision models with A2UI, which help building faster and more reliable generative UI experiences. Using our new A2UI Express as an inference format you can reduce latency by up to 3x, and up-to 80x using decision models like Jev to make layout decisions. Express requires up to 3x fewer tokens to generate the same kinds of UI compared to Direct JSON. We'll dive into the details in this blog post.
A2UI 是一种面向智能体优化的生成式 UI 协议:客户端将一组可信组件目录作为契约公布,智能体发送 A2UI 消息,描述由该目录中的组件构成的定制用户界面,而客户端的渲染器则负责绘制 UI(参见《A2UI 简介》)。A2UI is an agent-optimized protocol for generative UI, where a client advertises a catalog of trusted components as a contract, an agent sends A2UI messages describing a bespoke user interface composed from that catalog, and the client's renderer draws the UI (see Introducing A2UI).
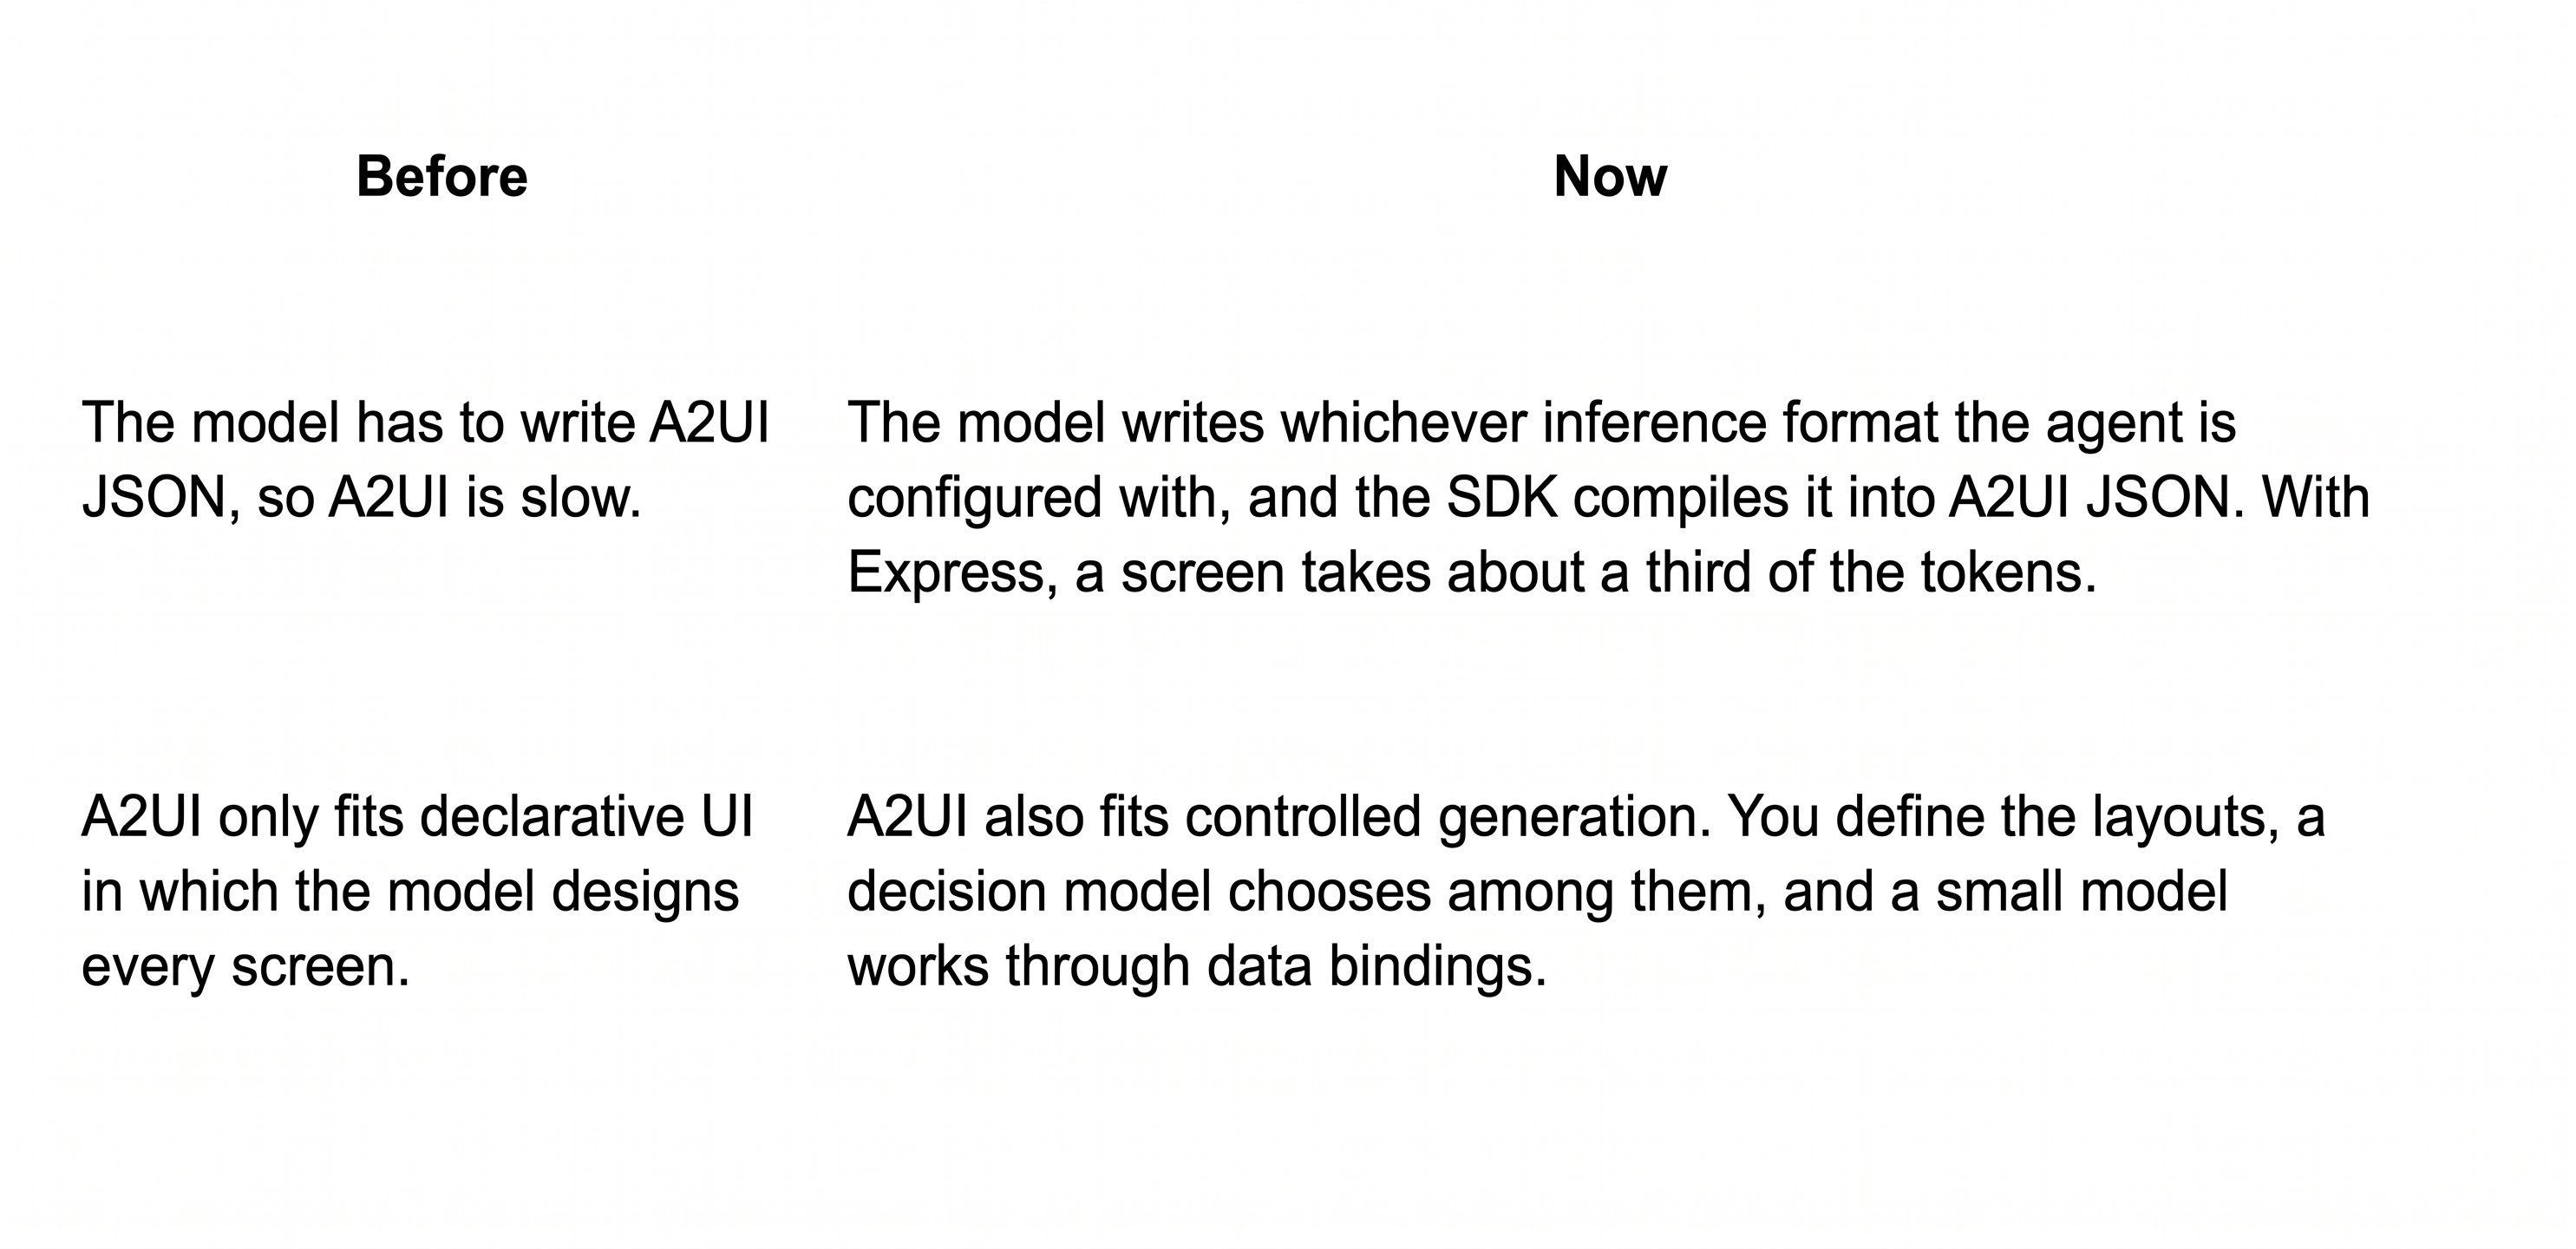
最初,智能体直接生成 A2UI JSON 传输消息,包括每个花括号和嵌套元素。事实证明,对于 LLM 来说,生成受复杂 JSON 架构约束的 JSON 树既缓慢又容易出错。这使 A2UI 与输出文本的 LLM 紧密耦合,也让集成更快的 System One 决策模型变得困难。Initially agents generated A2UI JSON transport messages directly, every curly brace and nested element. It turns out that generating JSON trees constrained by a complex JSON schema is slow and error-prone for LLMs. This coupled A2UI to LLMs, which output text, and made it difficult to integrate faster System One decision models.
现在,智能体可以生成 A2UI Express,这是一种针对推理速度和准确性进行优化的中间格式,并依靠 A2UI Agent SDK 中的确定性代码将其转换为基于 JSON 的传输协议。对于特殊用例,智能体开发者也可以自由换用其他 DSL 及其配套编译器,而 A2UI Agent SDK 则能确保其与传输方式和渲染器兼容。Now agents can generate A2UI Express, an intermediate format optimized for inference speed and accuracy, and rely on deterministic code in A2UI's Agent SDKs to translate it into the JSON-based transport protocol. Agent builders are also free to swap in any other DSL and its associated compiler for any special use-cases, and our A2UI Agent SDK(s) make it compatible with transports and renders.
模型生成的格式就是我们所说的 inference_format。创建生成器时,只需通过一个参数进行设置。SDK 会针对该格式生成提示指令,并将模型的回复编译为标准的 A2UI 消息。本文将介绍这种切换的工作原理、我们为何将 A2UI Express 设为新的默认推理格式,以及决策模型如何根据你预先定义的布局构建屏幕。The format the model generates is what we call inference_format. You set it with one argument when you create the generator. The SDK generates the prompt instructions for that format and compiles the model's reply into standard A2UI messages. This post covers how the swap works, why we developed A2UI Express as the new default inference format, and how a decision model can build screens from layouts you define in advance.
关于 A2UI,有两点已不再成立Two things no longer true about A2UI
一种推理格式包含两部分,SDK 会根据目录的 JSON schema 生成这两部分。提示部分会教模型该格式的语法,编译器则会将模型的回复编译为经过验证的 A2UI 消息。由于这两部分都由 schema 生成,格式无法描述目录中不存在的组件或属性。An inference format has two parts, and the SDK generates both from your catalog's JSON schema. A prompt section teaches the model the format's syntax, and a compiler compiles the model's reply into validated A2UI messages. Because both come from the schema, a format can't describe a component or property that your catalog lacks.
创建生成器时,只需通过一个参数选择格式:You choose the format with one argument when you create the generator:
from a2ui.processor import A2uiGenerator, CatalogConfig
from a2ui.inference_formats import ExpressFormatFactory

catalog = CatalogConfig.from_path("catalog.json")
generator = A2uiGenerator(
    [catalog],
    examples=few_shot_examples,  # written once as A2UI JSON
    inference_format_factory=ExpressFormatFactory(),
)

processor = generator.create_processor(renderer_capabilities)
system_prompt = f"{instructions}\n\n{processor.prompt_snippet}"
parts = processor.parse_response(model_reply)  # text parts + validated A2UI messages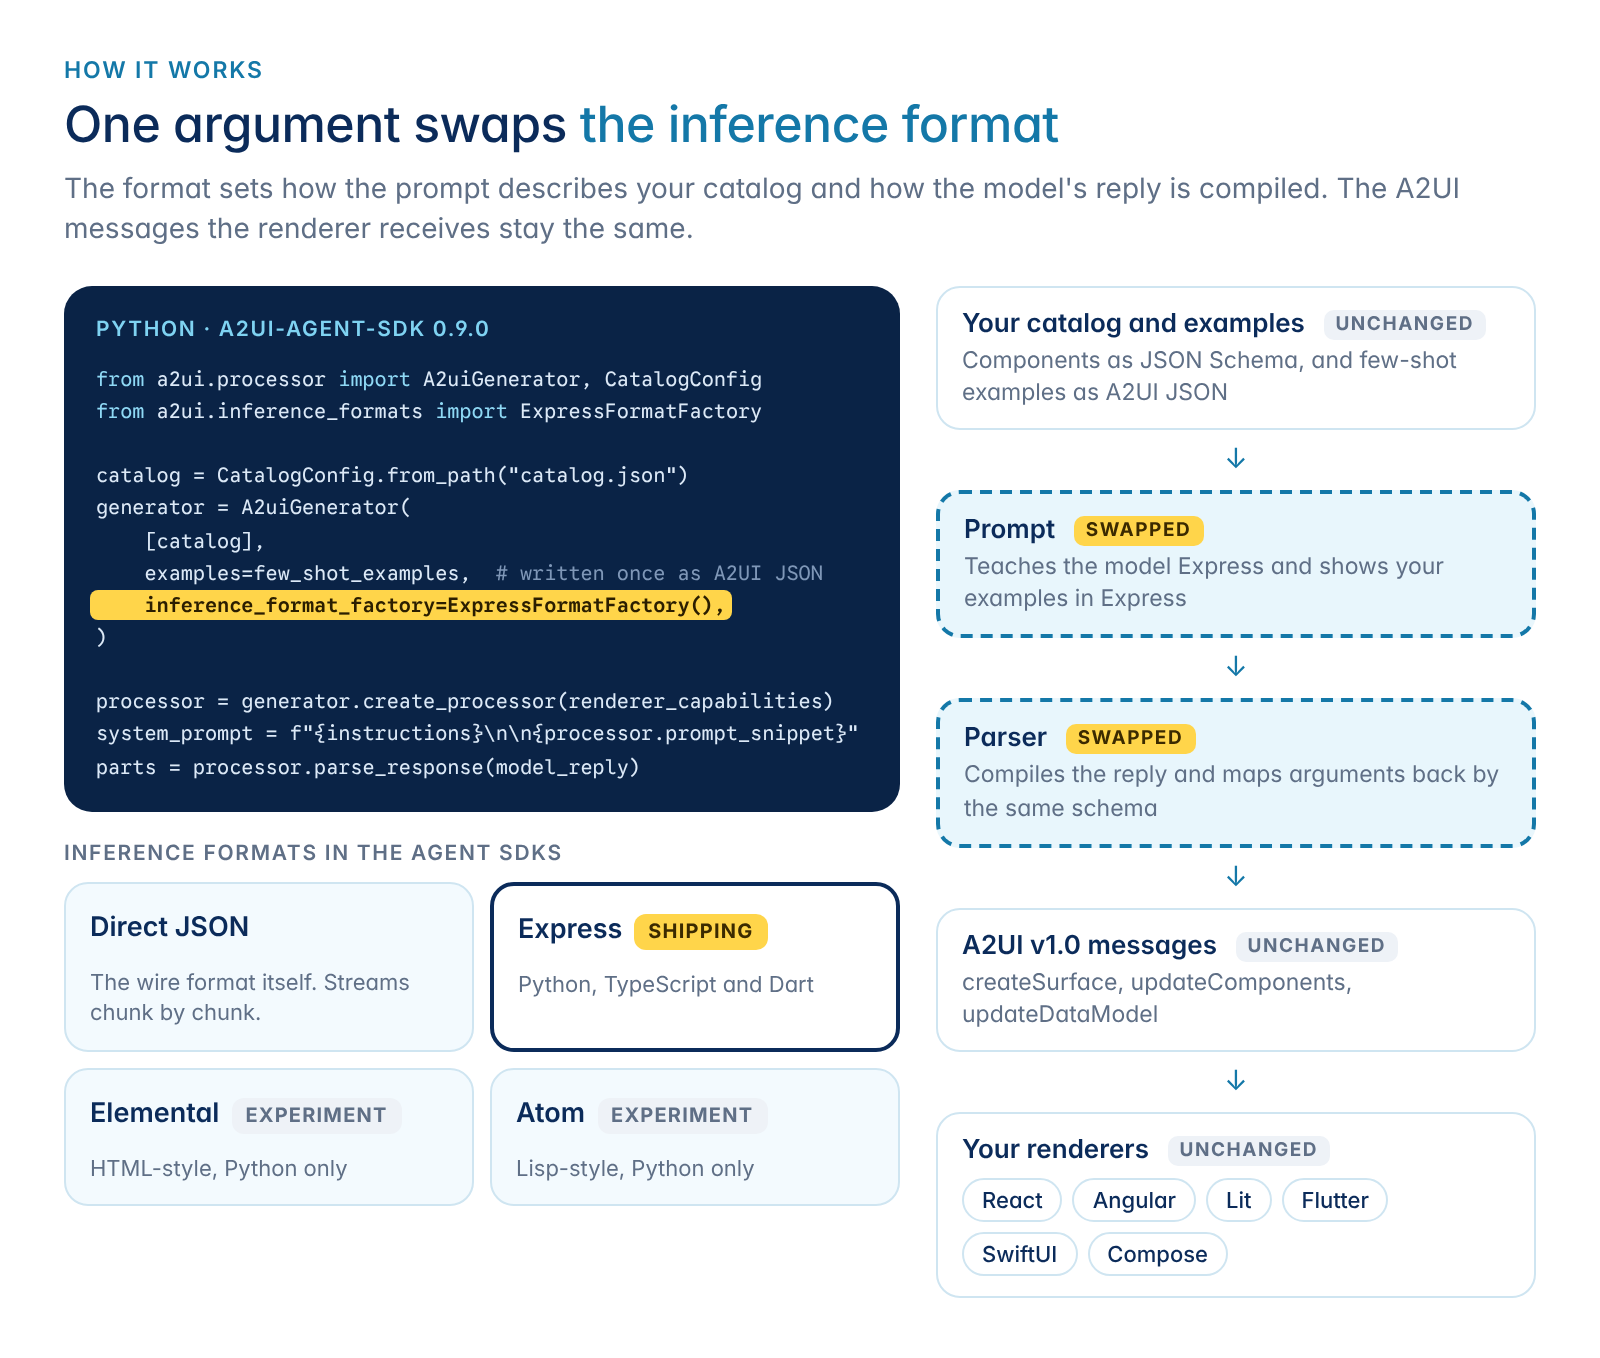
A2UI Express 已在 Python agent SDK(PyPI 上的 a2ui-agent-sdk 0.9.0)、TypeScript agent SDK(npm 上的 @a2ui/agent)以及 Dart SDK(pub.dev 上的 a2ui_agent 0.0.1-wip004)中提供。在 TypeScript 中,将 new ExpressFormatFactory() 作为生成器的第三个参数传入。Python 和 TypeScript SDK 都可以逐块流式传输 Direct JSON,并根据完整回复编译 Express。A2UI Express is available in the Python agent SDK (a2ui-agent-sdk 0.9.0 on PyPI), in the TypeScript agent SDK (@a2ui/agent on npm), and in the Dart SDK (a2ui_agent 0.0.1-wip004 on pub.dev). In TypeScript, you pass new ExpressFormatFactory() as the generator's third argument. The Python and TypeScript SDKs can both stream Direct JSON chunk by chunk, and they compile Express from the complete reply.
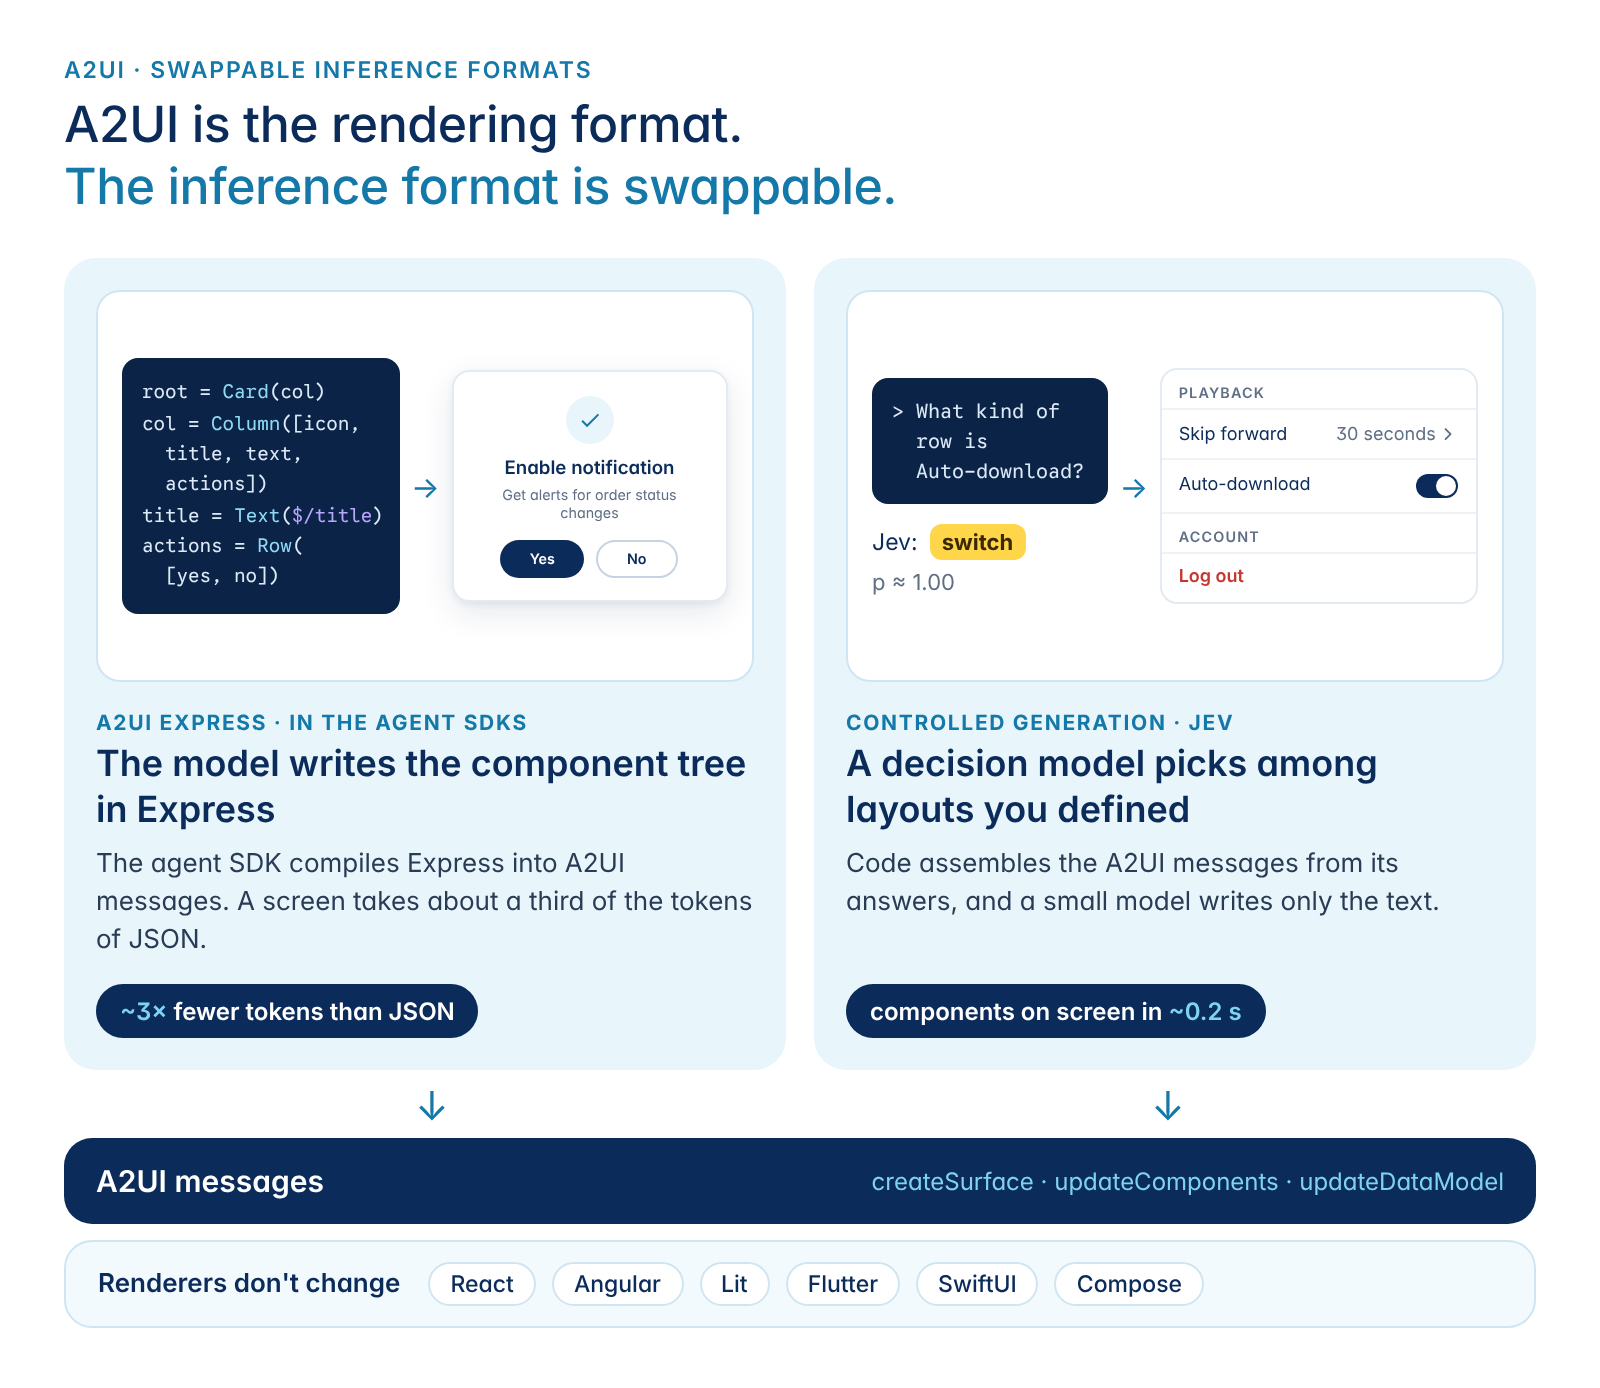
Express:用三分之一的 token 实现相同的界面Express: the same screens in a third of the tokens
Express 每行编写一条语句,风格接近 Python。每行都会将一个组件赋值给变量,而变量名会成为组件 ID。参数按位置传递:编译器会按照目录架构中声明属性的顺序,将参数映射到属性名称;_ 用于跳过一个属性。$/title 会将一个值绑定到数据模型,而 Event("accept") 则声明一个服务器操作。以下是 A2UI 展示库中的通知卡片在 Express 中的写法:Express writes one statement per line, in a style close to Python. Each line assigns a component to a variable, and the variable name becomes the component ID. Arguments are positional: the compiler maps them to property names in the order your catalog schema declares them, and _ skips one. $/title binds a value to the data model, and Event("accept") declares a server action. This is the A2UI gallery's notification card in Express:
surface("gallery-notification-permission")
$/description="Get alerts for order status changes"
$/icon="check"
$/title="Enable notification"
root=Card(main_column)
main_column=Column([icon, title, description, actions], _, "center")
icon=Icon($/icon)
title=Text($/title)
description=Text($/description, "body")
actions=Row([yes_btn, no_btn], "center")
yes_btn_text=Text("Yes")
yes_btn=Button(yes_btn_text, _, Event("accept", {}))
no_btn_text=Text("No")
no_btn=Button(no_btn_text, _, Event("decline", {}))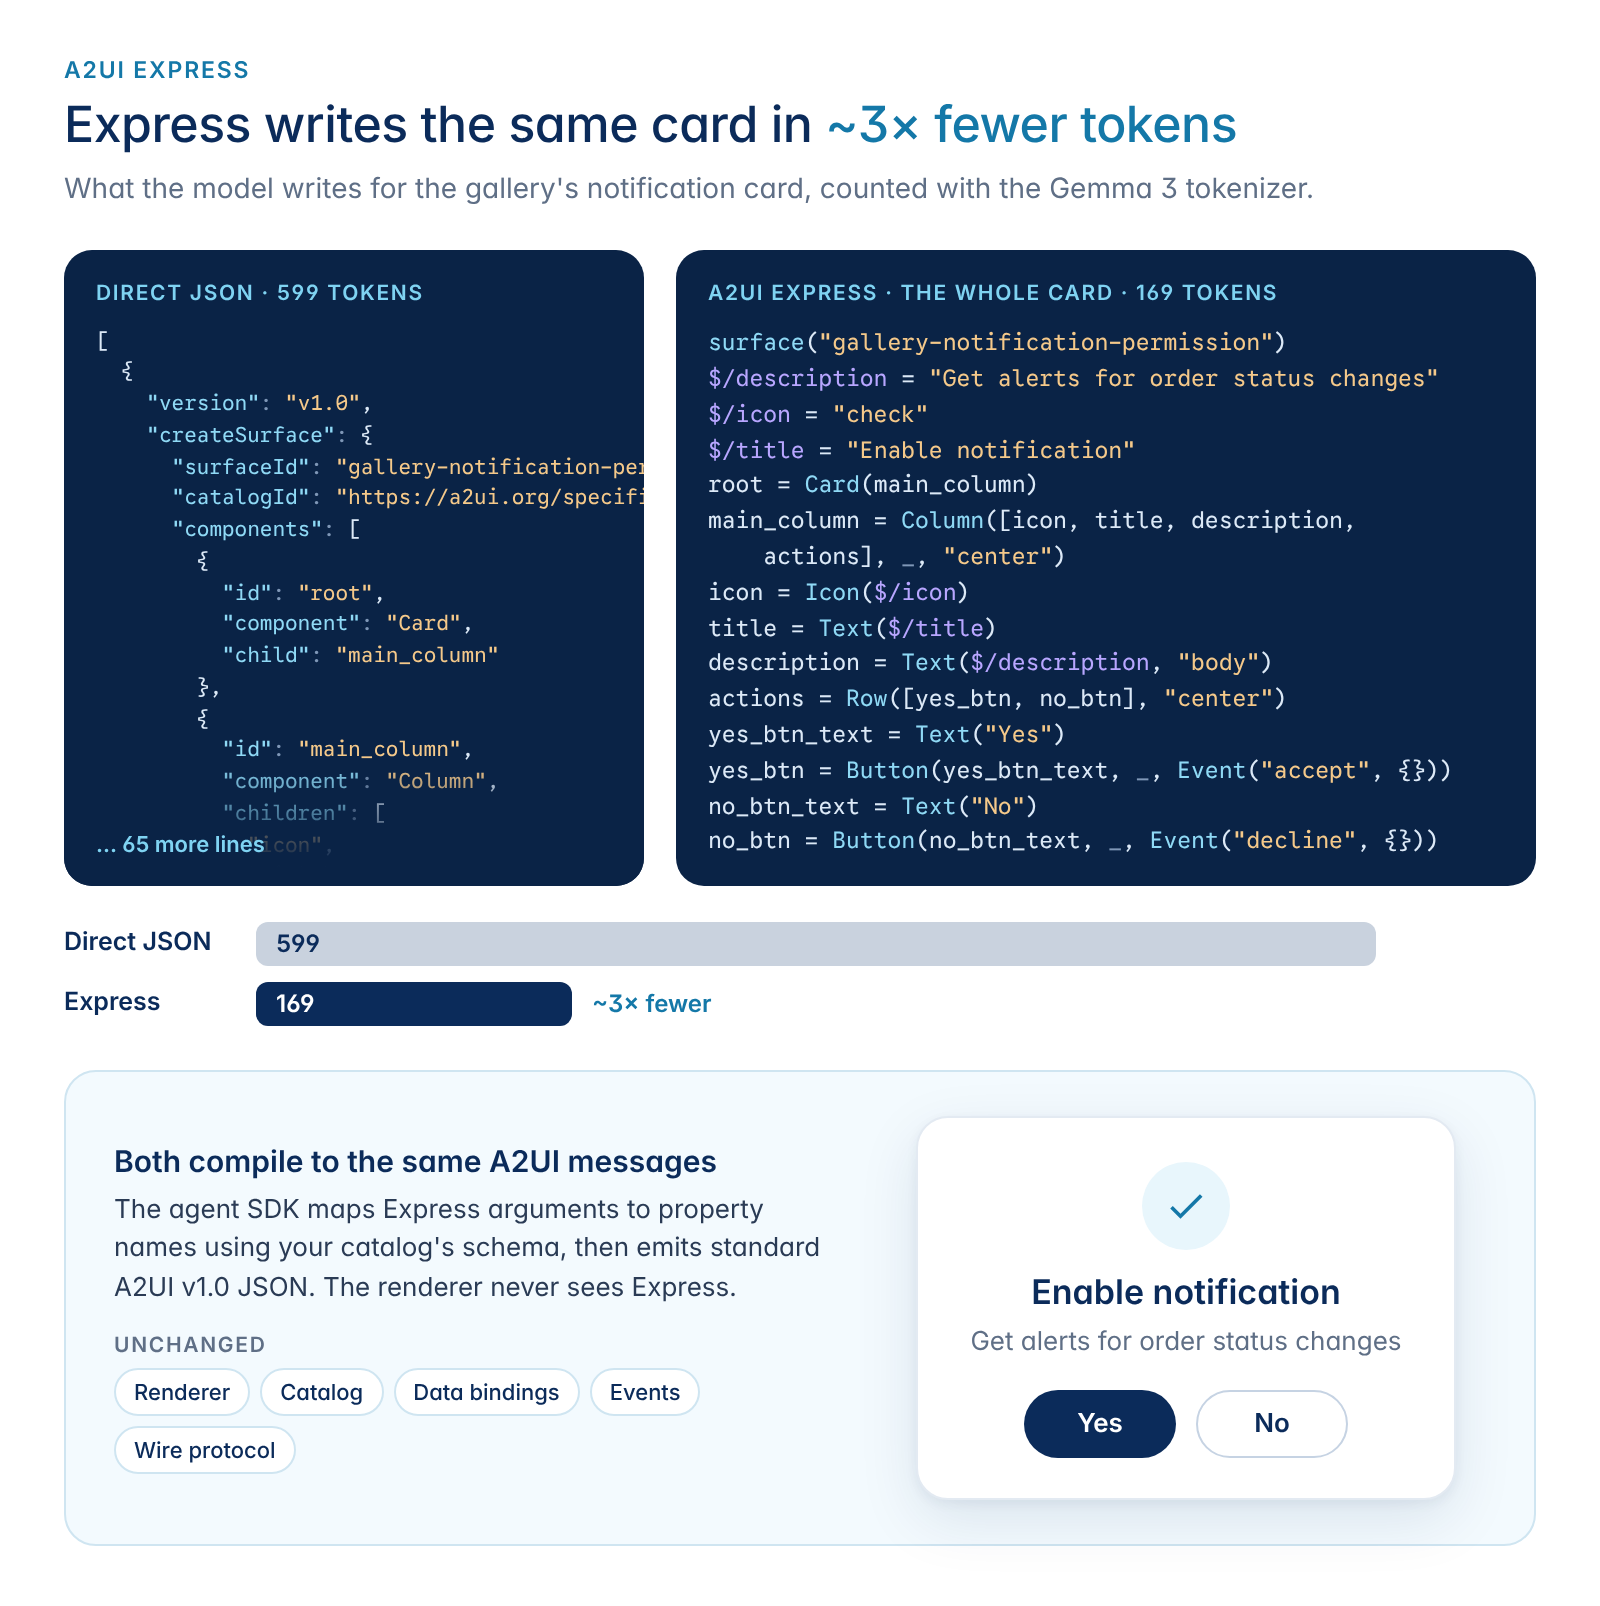
可替换的推理格式(包括 A2UI Express)也支持 Python agent SDK 中的宏,这在屏幕需要显示系统中已有的数据时很有帮助。模型只需生成一个仅包含 ID 的调用,例如 OrderStatus("ord_42"),宏就会获取订单并填入相应值,因此屏幕上的每个值都直接来自你的数据。宏的 README 介绍了如何进行设置。Swappable Inference formats including A2UI Express also work with macros in the Python agent SDK, which help when a screen shows data your systems already hold. The model writes a call with only an ID, such as OrderStatus("ord_42"), and your macro fetches the order and fills in the values, so every value on screen comes straight from your data. The macros README shows the setup.
我们如何构思出 A2UI ExpressHow we devised A2UI Express
客户反馈揭示了直接生成 JSON 时存在延迟和准确性问题。为了解决这些问题,我们开始设计一种新的推理格式,并尝试了四种方案:Customer feedback uncovered latency and accuracy issues with direct JSON generation. To fix this, we started devising a new inference format. We experimented with four options:
- 直接 JSON:这是我们在 2025 年 12 月推出时采用的现有基线。Direct JSON: This was our existing baseline that we launched with back in December 2025.
- Express:我们选定为新默认格式的最终版、受 `python` 语法启发的格式。Express: The final `python` syntax inspired format that we picked as the new default.
- Atom:编写 Lisp 风格的 S 表达式,不使用赋值,也不使用闭合标签。Atom: Writes Lisp-style S-expressions with no assignments and no closing tags.
- Elemental:使用自定义元素编写 HTML,赌的是模型已经很擅长编写 HTML。Elemental: Writes HTML with custom elements, betting on how well models already write HTML.
我们在 gemini-3.5-flash 上使用相同的 51 项任务评测测试了全部四种格式,并比较了两种思考模式:开启和关闭。We ran all four formats through the same 51-task eval on gemini-3.5-flash and compared them for thinking modes: on and off.
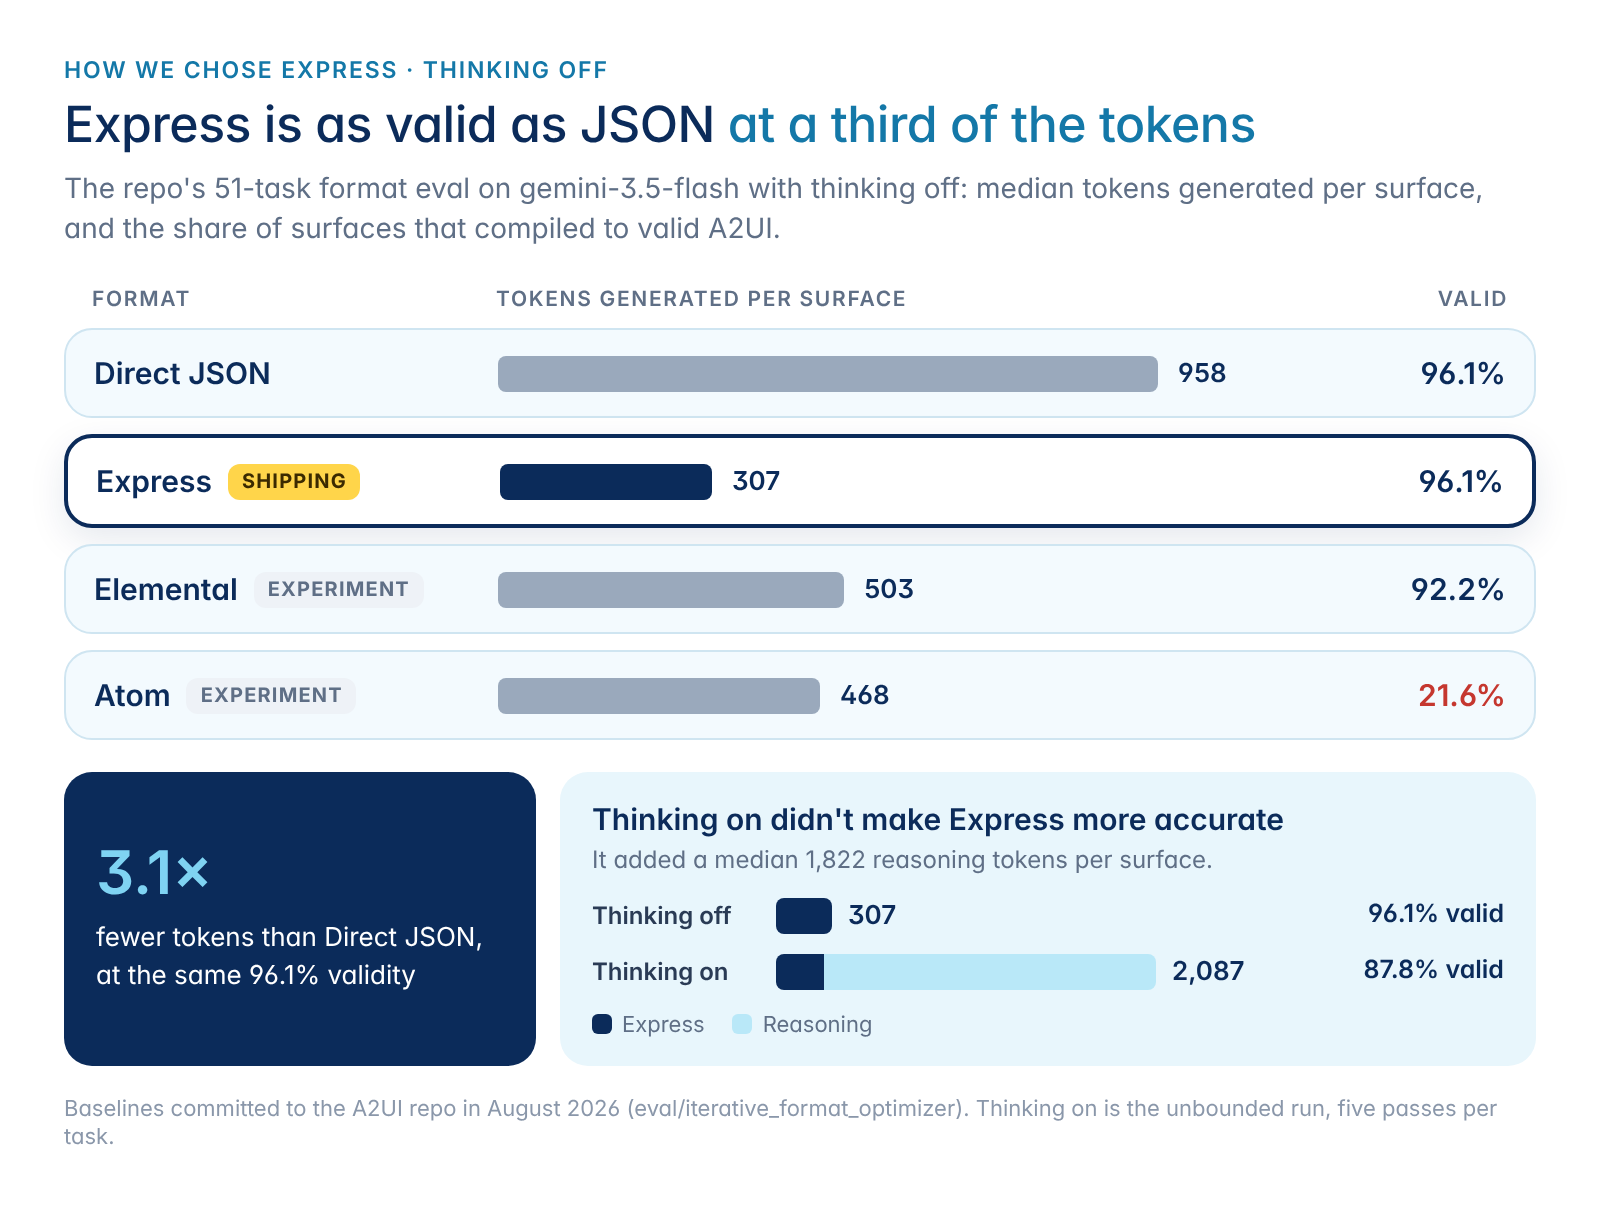
我们观察到,即使关闭思考,Express 推理格式也同样有效;使用 A2UI Express 时,它还能带来最快的推理速度。We observed that Express inference format works just as well even with thinking off; which can give you the fastest inference times when working with A2UI Express.
使用 Jev 进行受控生成Controlled generation with Jev
有些屏幕的结构是固定的,例如设置页面、结账页面或确认页面。对于这类屏幕,模型无需设计布局,只需从你预先定义好的布局中进行选择。为此,我们会构建另一种类型的模型。在这种情况下,你不需要 A2UI Express 所提供的全部表达能力。Some screens have a known shape, such as a settings page, a checkout or a confirmation. For those, the model doesn't need to design a layout. It needs to choose among layouts you have already defined, and a different kind of model is built for that. For this, you would not need the full expressivity provided by A2UI Express.
TypeSafe 的 Jev 是一种所谓的 System One 模型,旨在快速做出结构化决策,供代码直接使用。Jev 不生成文本或 JSON。你向它发送一个状态和一组带类型的问题,它会为每个问题给出经过校准的概率。问题可以询问某个陈述是否属实(Noul)、列表中的哪个选项符合条件(Choice),或某项内容在评分标准上的得分如何(Score)。Jev 能在一次请求中回答许多问题,耗时约为 100 到 300 毫秒。Jev, from TypeSafe, is what is called a System One model, built to make fast, structured decisions that code can use directly. Jev doesn't generate text or JSON. You send it a state and a set of typed questions, and it answers each one with calibrated probabilities. A question can ask whether a statement is true (Noul), which option from a list fits (Choice), or how something scores on a rubric (Score). Jev answers many questions in one request, in roughly 100 to 300 ms.
开源设计工具 Apparite(jev2ui) 展示了一种将 System One 模型连接到 A2UI 的方式。Jev 决定每个屏幕的结构,代码根据这些决定构建 A2UI 组件,而一个小型模型 gemini-3.5-flash-lite 只负责撰写文本。问题预先写在一套 Markdown 语法中。引用块提出一个问题,项目符号列出选项,每个选项都带有相应的标准。语法文件 grammar/screen.md 中的这段内容决定了设置行使用哪种控件:Apparite(jev2ui), an open-source design tool, shows one way to connect a System One model to A2UI. Jev decides the structure of each screen, code builds the A2UI components from those decisions, and a small model, gemini-3.5-flash-lite, writes only the text. The questions live in a Markdown grammar written ahead of time. A blockquote asks a question, and the bullets are its options, each with criteria. This block from grammar/screen.md decides which control a settings row gets:
#### row_control (of each row in rows, within each group in groups)

Material: a switch for one on/off setting that takes effect at once. HIG: a disclosure indicator for a row that opens another page.

> `{row}` is a row in the supplied screen and section. Grouped rows can represent content, navigation, settings or actions; use their actual text and context to decide.
>
> What kind of row is {row}?

- **switch** — A setting that is simply on or off and takes effect at once: notifications, dark mode, autoplay, sync.
- **value** — A setting with one current value picked from several, changed on another page: language, quality, theme, frequency, units.
- **nav** — A link to another page: a content item, details, account, privacy, help, about, or managing something. Its text and section identify what it opens.
- **check** — One of several alternative options listed together, of which one is chosen: the choices of a single setting, such as '10 seconds', '30 seconds', 'High', 'Low'.
- **danger** — A final or destructive account action: sign out, delete account, clear data, reset.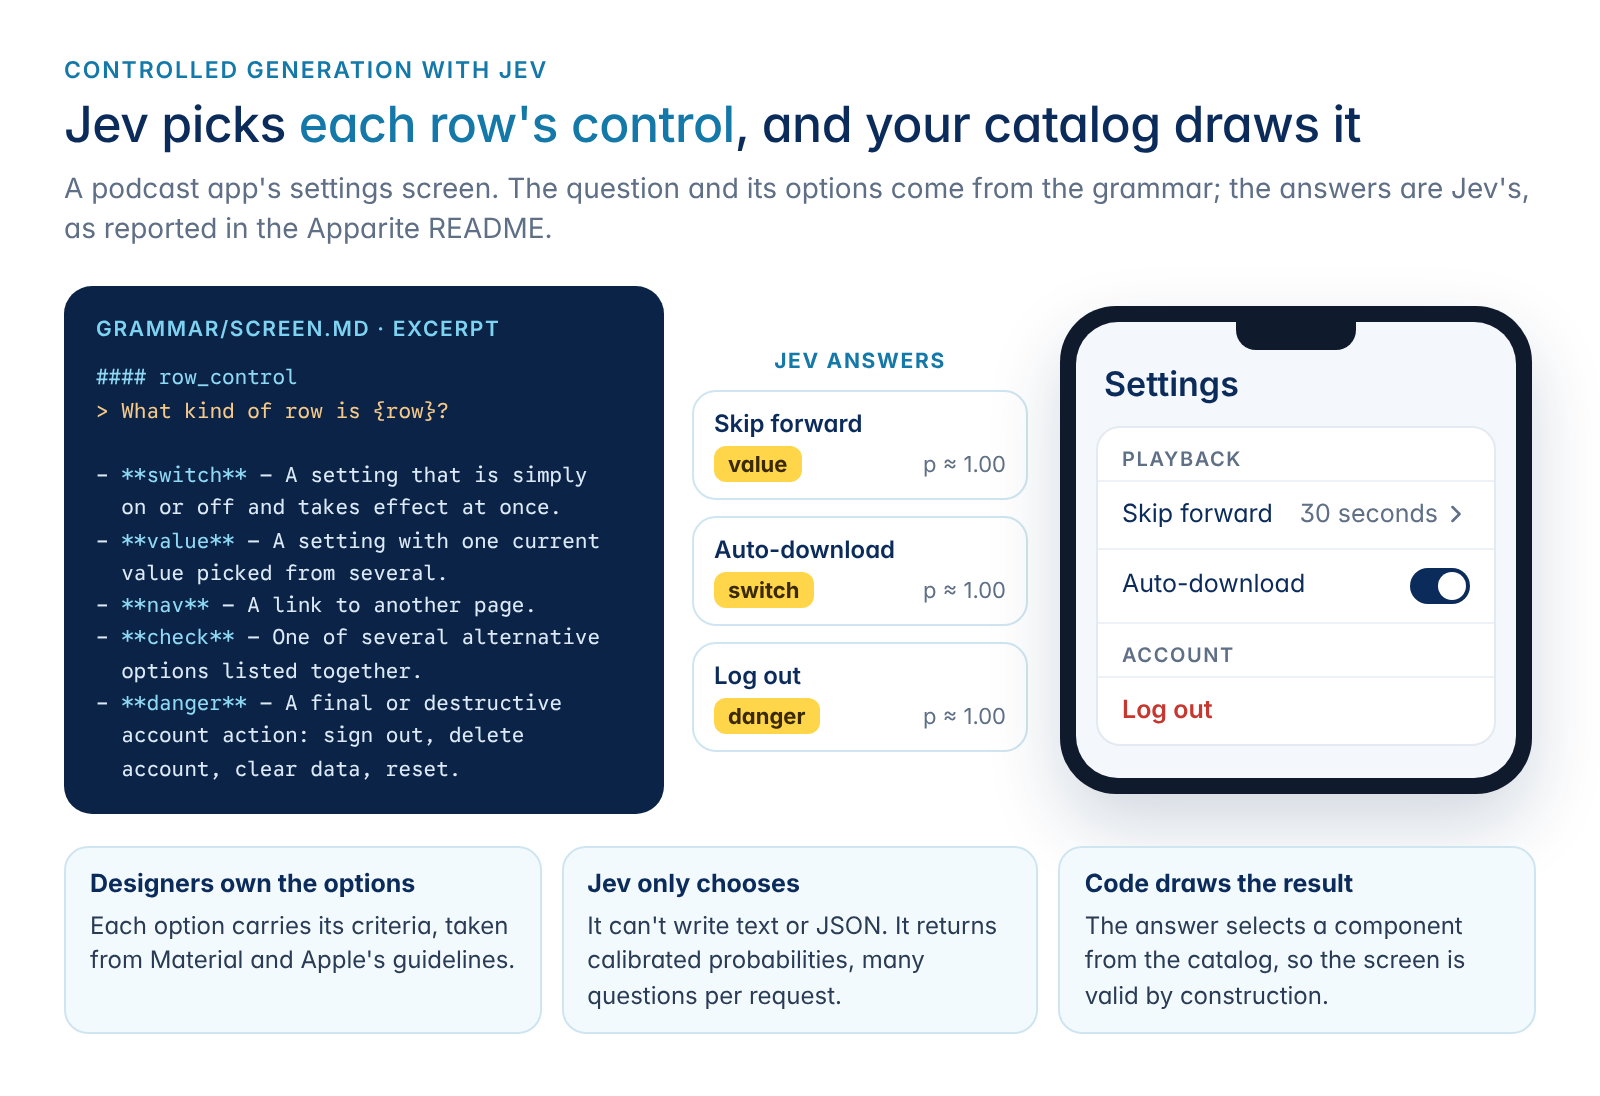
在播客应用的设置屏幕上,Jev 对“快进 → 数值”、“自动下载 → 开关”和“退出登录 → 危险操作”逐一作答,每项的 p ≈ 1.00。Apparite 分三步构建整个屏幕:On a podcast app's settings screen, Jev answers Skip forward → value, Auto-download → switch and Log out → danger, each at p ≈ 1.00. Apparite builds a whole screen in three steps:
- 一次 Jev 请求即可回答语法中的布局问题,每个屏幕大约有 30 个。One Jev request answers the grammar's layout questions, about 30 for a screen.
- 代码从目录构建组件树,并以约 200 毫秒的间隔发送 createSurface 和 updateComponents,其中预留了文本将要放置的位置。Code builds the component tree from the catalog and sends
createSurfaceandupdateComponentsat about 200 ms, with placeholders where the text will go. - gemini-3.5-flash-lite 将文本流式传入 updateDataModel。每当一部分内容到达,较小的后续 Jev 请求就会处理依赖于它的内容,例如上方的行控件。gemini-3.5-flash-lite streams the text into
updateDataModel. As each part arrives, small follow-up Jev requests settle what depends on it, such as the row controls above.
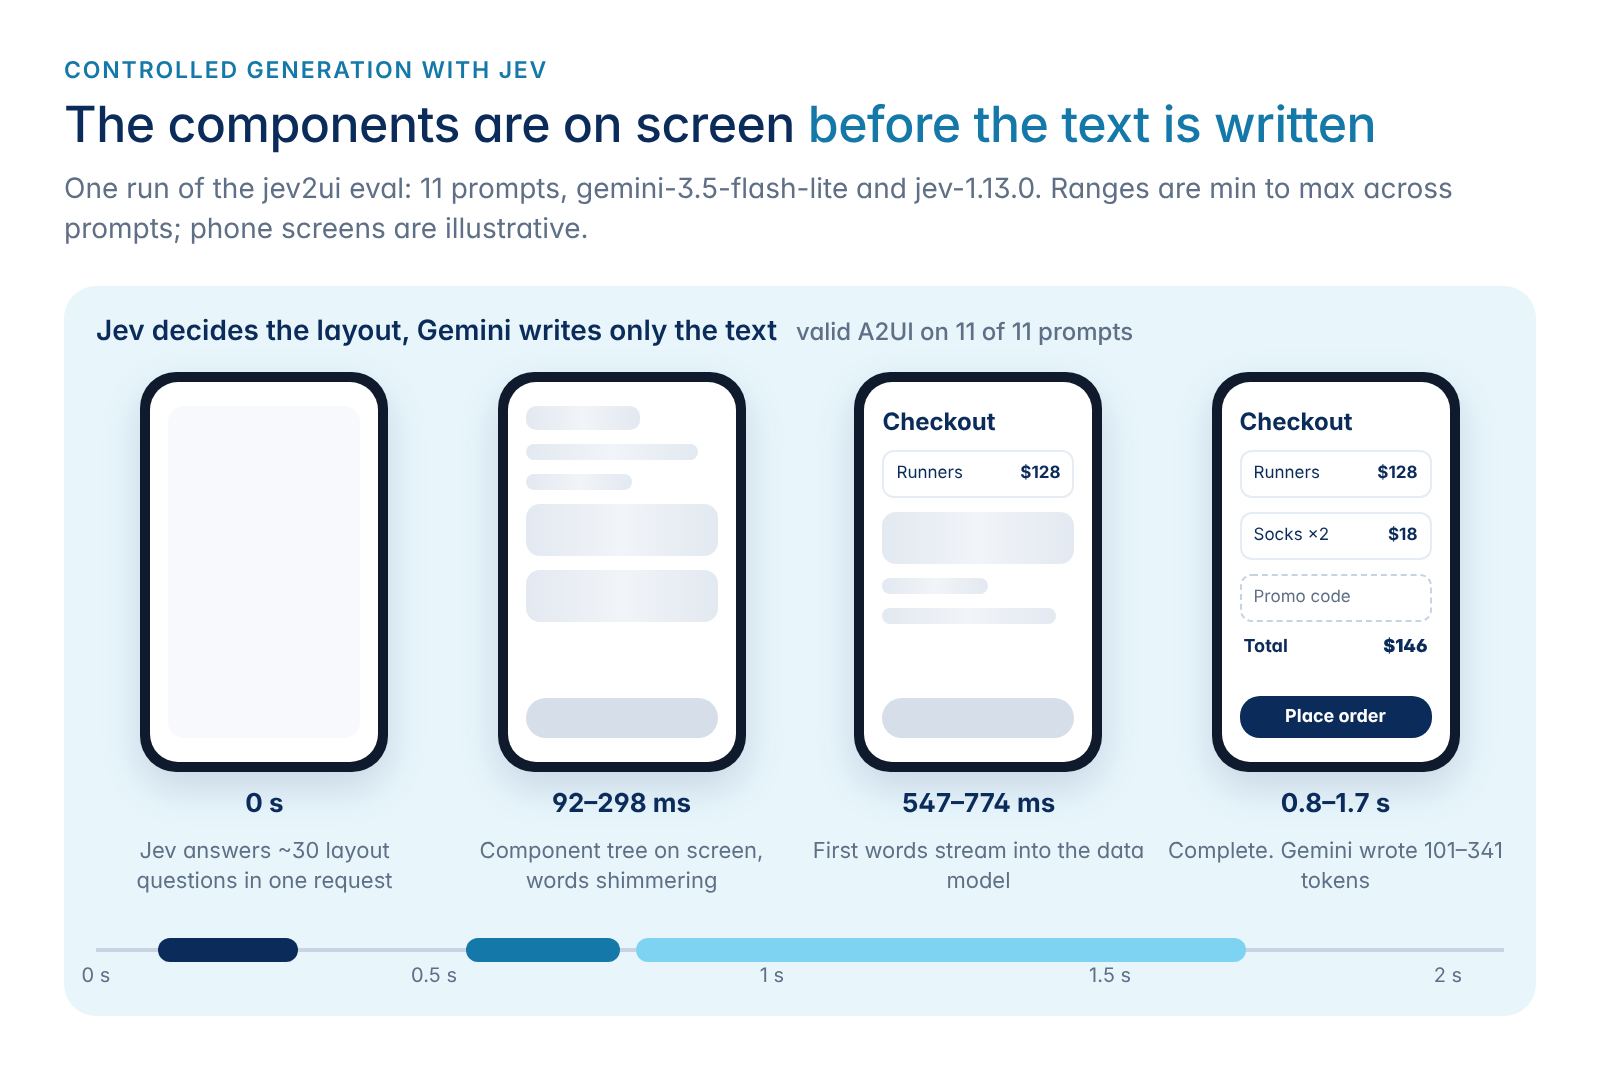
在一次包含 11 个提示词的运行中,组件树在 92 至 298 毫秒内显示在屏幕上,每个屏幕则在 0.8 至 1.7 秒内完成。文本生成器为每个屏幕生成了 101 至 341 个 token,而 Apparite 的两条 Jev 流水线在全部 11 个提示词中都生成了有效的 A2UI。项目将这些数据视为初步观察结果,因为样本量较小。In one run of 11 prompts, the component tree was on screen in 92 to 298 ms and each screen was complete in 0.8 to 1.7 s. The text writer generated 101 to 341 tokens per screen, and both of Apparite's Jev pipelines produced valid A2UI on all 11 prompts. The project treats these numbers as a first look, since the sample is small.
受控生成只能生成其语法所描述的布局。Apparite 的语法涵盖九种屏幕原型和十二种区块,因此对于形态未知的屏幕,Express 会更合适。A2UI Agent SDK 目前还未包含决策模型推理格式;apparite(jev2ui) 项目展示了如何根据决策模型的一批独立决策来组装 A2UI 消息。Controlled generation can only produce the layouts its grammar describes. Apparite's grammar covers nine screen archetypes and twelve blocks, so screens without a known shape are a better fit for Express. A2UI Agent SDKs, don’t include a decision model inference format yet; apparite(jev2ui) project is an example on how A2UI messages could be assembled given a batch of independent decisions from a decision model.
使用哪种模式Which mode to use
A2UI Express 速度很快,并保留了 A2UI 的全部表达能力,但由决策模型做出多个独立决策仍然更快。请根据你能提前定义屏幕内容的程度来选择:A2UI Express is fast and keeps the full expressivity of A2UI, but a decision model making multiple independent decisions is still faster. Choose by how much of the screen you can define ahead of time:
- 如果决策模型能够生成你所需的内容,就采用受控模式。如果你的屏幕遵循固定且明确的布局,决策模型可能是最快的选择。Controlled, when a decision model can produce what you need. If your screens follow set and defined layouts, a decision model may be the fastest option.
- 要实现完整的表达能力,请使用 Express。当某个屏幕需要基于你的目录实现更丰富的表达时,就回退到 A2UI Express。它速度很快,而且模型仍会编写整个组件树。Express for full expressivity. When a screen needs more expressivity based on your catalog, fall back to A2UI Express. It's fast, and the model still writes the whole component tree.
- 任何新内容都可以使用你自己的格式。由于推理格式可以互换,新的用例或未来的语法只需要一个提示生成器来教模型使用你的 DSL,以及一个用于在你的 DSL 和 A2UI 消息之间转换的转换器。你的目录和渲染器都无需更改。Your own format for anything new. Because inference formats are swappable, a new use case or a future syntax needs only a prompt generator that teaches the model your DSL and a converter that converts between your DSL and A2UI messages. Your catalog and renderers stay the same.
试试看Try it
在你的 agent 中使用 Express。使用 pip install a2ui-agent-sdk 安装 Python SDK,或使用 npm install @a2ui/agent 安装 TypeScript SDK;创建生成器时传入 ExpressFormatFactory(),并在关闭思考模式的情况下运行模型。你的目录和渲染器保持不变,Express 规范中记录了语法。Use Express in your agent. Install the Python SDK with pip install a2ui-agent-sdk or the TypeScript SDK with npm install @a2ui/agent, pass ExpressFormatFactory() when you create the generator, and run the model with thinking off. Your catalog and renderers stay as they are, and the Express specification documents the syntax.
要教 Gemini 或任何其他可加载技能的模型仅使用你的组件编写 Express,可使用 Python SDK 的 SkillGenerator 从你的目录生成技能:To teach Gemini, or any other model that loads skills, to write Express with only your components, generate skills from your catalog with the Python SDK's SkillGenerator:
import json
from a2ui.core import Catalog
from a2ui.inference_formats.express import ExpressFormat
from a2ui.skill import SkillGenerator

catalog = Catalog.from_json(json.load(open("catalog.json")))
skills = SkillGenerator(ExpressFormat([catalog])).generate_skillset()
skills.export_to_directory("skills")  # a2ui-core plus one skill per catalog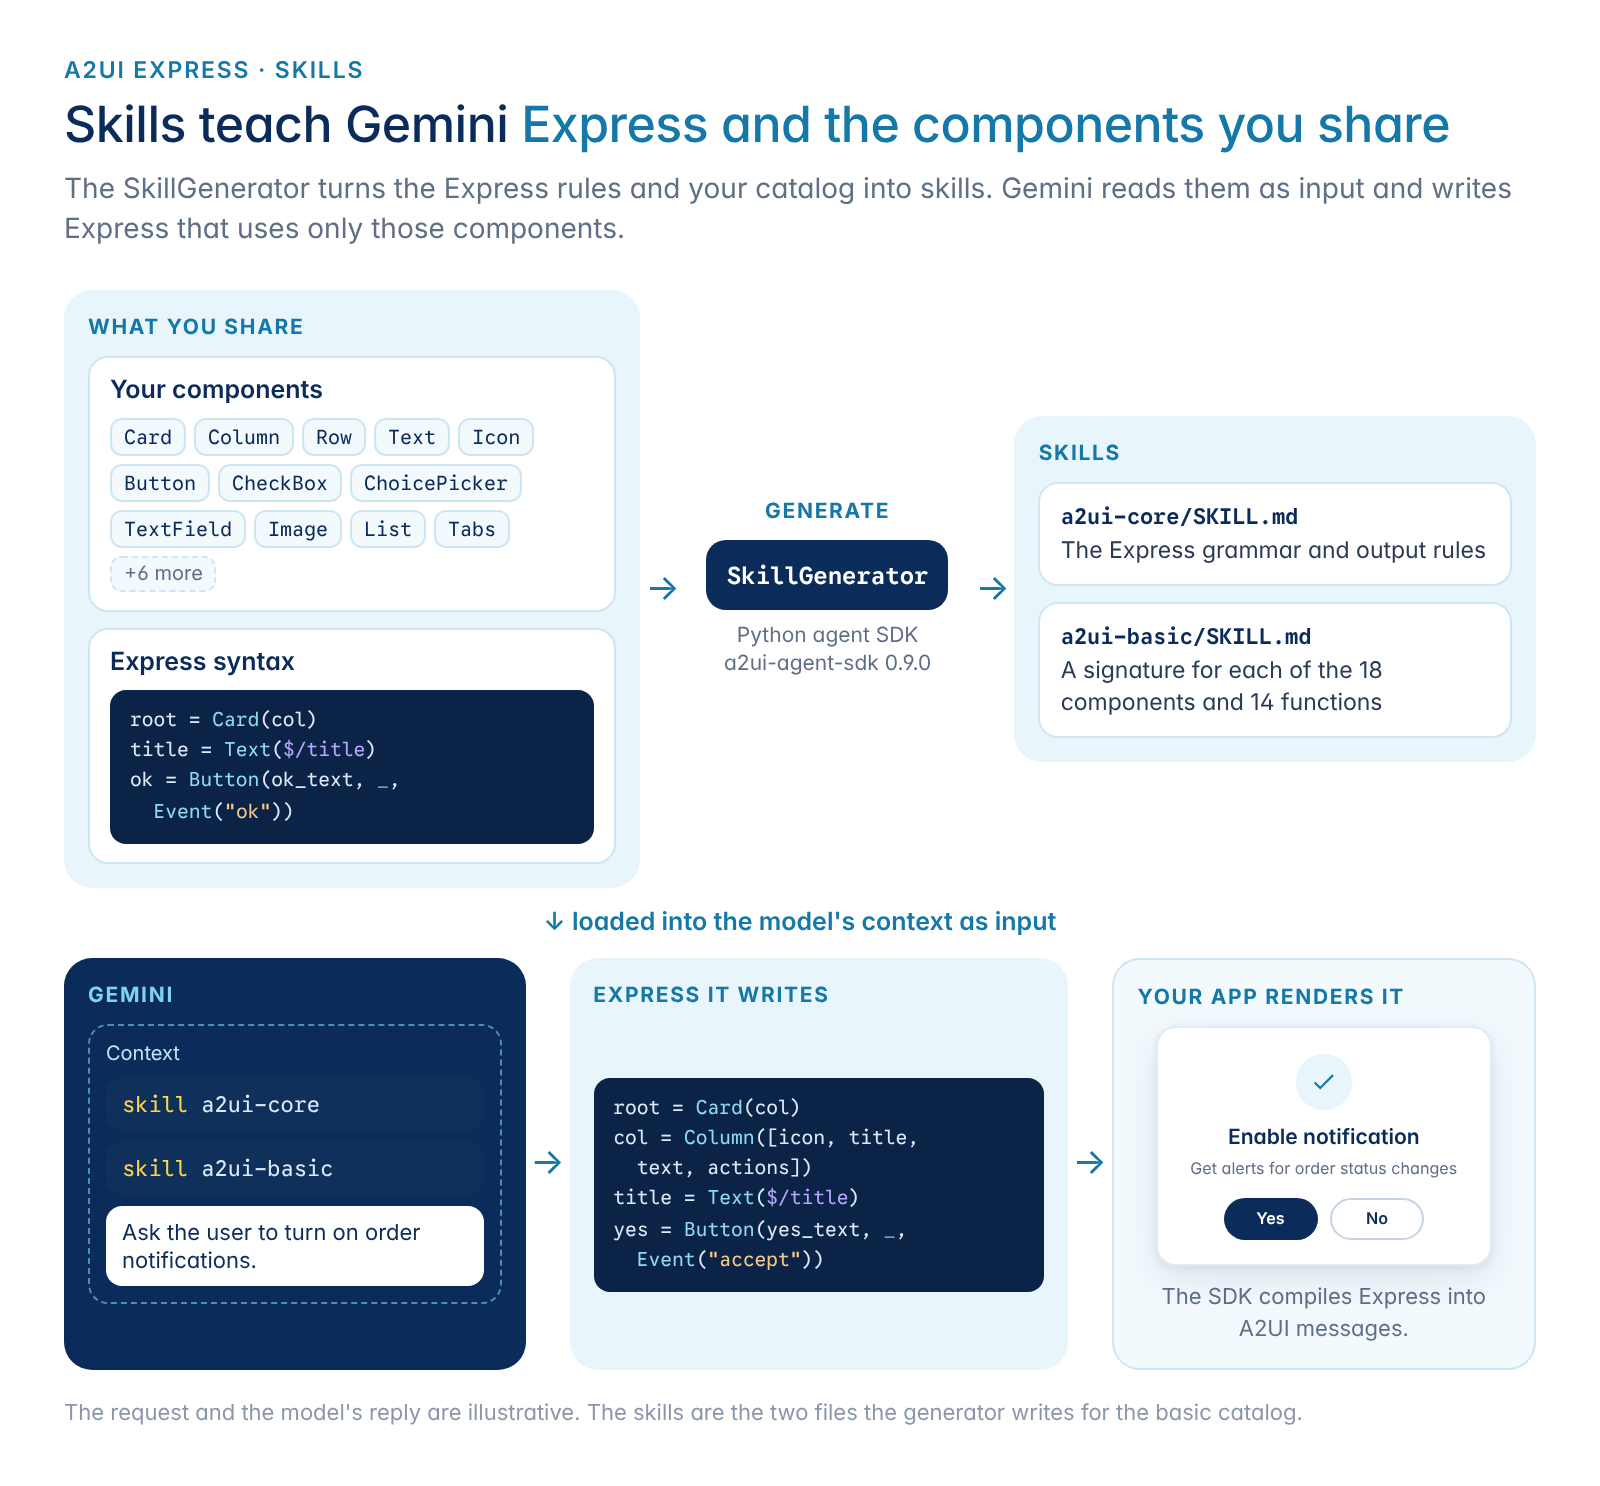
尝试受控生成。克隆示例 jev2ui 仓库,并按照其中的说明开始使用。Apparite(jev2ui) 的托管版本运行于 apparite.cnfg.ai。Try controlled generation. Clone the example jev2ui repository, and follow the instructions there to get started. A hosted version of Apparite(jev2ui) runs at apparite.cnfg.ai.
来源Sources
早期的 A2UI 文章:A2UI 简介(2025 年 12 月)、A2UI v0.9(2026 年 4 月)以及 A2UI + MCP Apps(2026 年 6 月)。Earlier A2UI posts: Introducing A2UI (December 2025), A2UI v0.9 (April 2026) and A2UI + MCP Apps (June 2026).
- A2UI Express 规范
- A2UI 基础元素规范和 A2UI 原子规范
- A2UI 评测中的推理格式基线Inference format baselines in the A2UI eval
- a2ui-agent-sdk changelog (0.9.0, October 17, 2026) and @a2ui/agent on npm (0.0.1)
- Python 智能体 SDK 中的技能生成器Skill generator in the Python agent SDK
- TypeSafe 提供的 Jev 文档Jev documentation from TypeSafe
- Apparite (jev2ui) README、“目前的成果”和“已知限制”,以及其屏幕语法Apparite (jev2ui) README, "Results so far" and "Known limits", and its screen grammar