
Apertus 1.5 发布说明
原题Apertus 1.5 Release Notes
读前速览
Apertus 1.5 在 8B 和 70B 模型的基础上,新增了对图像和音频的本地理解、将上下文窗口扩展了 4 倍,并提升了指令遵循和工具使用能力,同时保持开放源码的透明性和遵守 Apertus 章程。
原生多模态理解
得益于 Emu3.5 和 WavTokenizer 的集成,Apertus 1.5 能够将图像和音频与文本一道进行处理。这允许模型在无需独立编码器的情况下执行视觉-语言任务和语音识别。
扩展的上下文窗口
模型的上下文窗口已扩展至 262,144 个标记,比前一版本提升了 4 倍。这使分析非常长的文档和对话历史成为可能。
改进的推理和指令遵循
引入‘思考模式’,并针对推理跟踪进行专门的后训练,显著提升了模型处理复杂推理任务的性能,以及准确遵循指令的能力。
开放性和可复现性
Swiss AI 继续秉持透明原则,公开模型权重、训练数据和详细配方。使用 EvalEval 模式确保评估结果可复现并具有可比性。
完整摘要
Apertus 1.5 是对第一代模型的继续预训练,向 8B 模型增加了 4 万亿个文本和多模态数据标记,向 70B 模型增加了 2 万亿个。此次发布引入了本地多模态理解(图像和音频)、用于提升推理的“思考模式”、262k 标记的上下文窗口,以及增强的指令遵循和工具使用能力。训练过程包括四阶段的预训练,随后是五阶段的后训练(包括 SFT、RLVR 和 DPO),所有数据和配方均对外公开,以确保可复现性。
目录 · 11 节


- +4+4
Apertus 1.5 是在第一代模型基础上继续预训练的版本:为 8B 模型增加了 4 万亿个文本和多模态训练数据 token,为 70B 模型增加了 2 万亿个 token,使两者的 token 总数分别达到 19 万亿和 17 万亿。与每次发布 Apertus 一样,这些模型完全开放:开放权重、开放数据、开放价值观,并公开完整的训练细节。Apertus 1.5 is a continued pretraining of the first generation model: adding 4 trillion tokens of text and multimodal training data to the 8B model and 2 trillion tokens to the 70B model, for a total of 19T and 17T, respectively. As with every Apertus release, the models are fully open: open weights, open data, open values, and full training details.
主要改进内容 Key Enhancements
- 原生多模态理解:Apertus 1.5 支持在文本之外输入图像和音频,让文档、图表和照片也能参与对话。模型还可以处理口语,不过这项功能仍处于实验阶段。Native Multimodal Understanding: Apertus 1.5 accepts images and audio alongside text, bringing documents, diagrams, and photos into the conversation. The models can also process spoken language, though this remains experimental.
- 思考模式:可以将模型切换到思考模式,使其在回答前先对输入进行推理,从而提升其解决推理问题的表现。Thinking Mode: The models can be switched into a thinking mode to reason about the input before answering, which improves performance on reasoning problems.
- 长上下文:上下文窗口扩展至 262,144 个 token,是 Apertus 1.0 的 4 倍。Long Context: The context window grows to 262,144 tokens, a 4x increase over Apertus 1.0.
- 指令遵循能力提升:与 Apertus 1.0 相比,指令遵循能力更强,响应更可预测、更准确。Improved Instruction-Following: Better instruction adherence than Apertus 1.0 gives more predictable and accurate responses.
- 改进的工具使用:这些模型经过训练,能够更好地集成工具,从而更有效地使用外部工具和 API。Improved Tool Use: The models are trained for better tool integration, allowing more effective use of external tools and APIs.
- 开放价值观:更严格地遵循 Apertus 宪章,使模型的价值观和原则更加透明。Open Values: Stronger adherence to the Apertus Charter, which brings transparency to the model’s values and principles.
训练流程 Training Process
 The full Apertus 1.5 training pipeline
通过分词器实现多模态功能 Multimodality Through the Tokenizer
我们以早期融合的方式在 v1.5 模型中引入多模态:图像和音频作为离散词元,与文本词元一起进入 Apertus 的同一序列,而不是使用单独的视觉编码器。图像使用 Emu3.5 tokenizer 进行词元化(512×512 的图像会变成 1,024 个词元),音频则使用 WavTokenizer(每秒 40 个词元)。我们只扩展词汇表,因此架构保持不变,训练速度与纯文本训练相同。这些模型能够理解图像和音频,但只能生成文本。We introduce multimodality in v1.5 models in an early-fusion manner, where images and audio enter Apertus as discrete tokens in the same sequence with text tokens, instead of using a separate vision encoder. Images are tokenized with the Emu3.5 tokenizer (a 512×512 image becomes 1,024 tokens) and audio with WavTokenizer (40 tokens per second). We only extend the vocabulary, so the architecture stays unchanged and training runs at text-only speed. The models understand images and audio but generate only text.

预训练 Pre-Training
从 Apertus 1.0 开始,我们分四个阶段继续进行预训练:Starting from Apertus 1.0, we continue pretraining in four stages:
- 非配对:文本加上独立的图像和音频,让模型学习新的模态。Unpaired: text plus standalone images and audio, so the model learns the new modalities.
- 成对数据:图像–说明文字和音频–转录文本配对,使其与语言对齐。Paired: image–caption and audio–transcript pairs, so it aligns them with language.
- 冷却阶段:质量更高的数据,包含更多数学和代码。Cooldown: higher-quality data with more math and code.
- 长上下文:窗口逐步从 8k 扩展到 262k 个 token。Long context: the window grows step by step from 8k to 262k tokens.
总体而言,超过一半的训练 token 仅包含文本,从而保留了 Apertus 1.0 的语言能力。文本数据通过 FineWeb2-HQ+、FinePDFs 和 Nemotron-CC 等来源进行更新。所有新数据(包括多模态数据)都符合与此前相同的标准:公开可用、采用宽松许可,并追溯遵守 robots.txt 中的退出要求。所有数据来源均列于 apertus-data-transparency。Overall, more than half of the training tokens are text-only, which preserves the language abilities of Apertus 1.0. The text data is refreshed with sources such as FineWeb2-HQ+, FinePDFs, and Nemotron-CC. All new data, multimodal included, meets the same bar as before: publicly available, permissively licensed, and with robots.txt opt-outs respected retroactively. Every source is listed in apertus-data-transparency.
后训练 Post-Training
后训练分为五个阶段:SFT → 长上下文 SFT → RL → DPO → 章程对齐(SDPO)。Post-training runs in five stages: SFT → long-context SFT → RL → DPO → charter alignment (SDPO).
- 使用 370 万条文本样本以及图像和语音数据进行 SFT。仅对模型在没有推理轨迹时无法解决的提示添加推理轨迹。工具使用数据仅包含经过执行验证的轨迹。我们在 Hugging Face 上发布了所用的文本 SFT 混合数据集。SFT on 3.7M text samples plus image and speech data. Reasoning traces are added only to prompts the model can't already solve without them. Tool-use data is restricted to execution-verified trajectories. We release the text SFT mix we used on Hugging Face.
- 在完整的 262k 窗口上进行长上下文 SFT,可以恢复被短上下文 SFT 削弱的长上下文能力。Long-context SFT at the full 262k window restores the long-context ability that short-context SFT erodes.
- 在约 35 万条数学、代码、指令遵循、多语言和视觉提示上进行带可验证奖励的强化学习(RLVR),并混合使用开启和关闭思考模式的提示。RL with verifiable rewards (RLVR) on about 350k math, code, instruction-following, multilingual, and vision prompts, mixing thinking on and off.
- 使用由评审打分的偏好对进行 DPO,可提升聊天质量、工具使用能力和安全性。我们公开发布偏好池和训练对。DPO with judge-scored preference pairs improves chat quality, tool use, and safety. We release the preference pool and training pairs.
- SDPO 通过评审反馈和自蒸馏,使模型与 Apertus 宪章保持一致。SDPO aligns the model with the Apertus Charter through judge feedback and self-distillation.
评估结果 Evaluation Results
除了扩展模型能力之外,我们还大幅扩大了评估范围。在用于 Apertus 1.0 的现有文本评估基础上,我们新增了多模态评估(图像和音频)以及思考模式评估。Alongside the extended model capabilities, we also significantly expanded the scope of evaluations. Beyond the existing text-based evaluations used for Apertus 1.0, we added multimodal evaluations (image & audio), and thinking-mode evaluations.
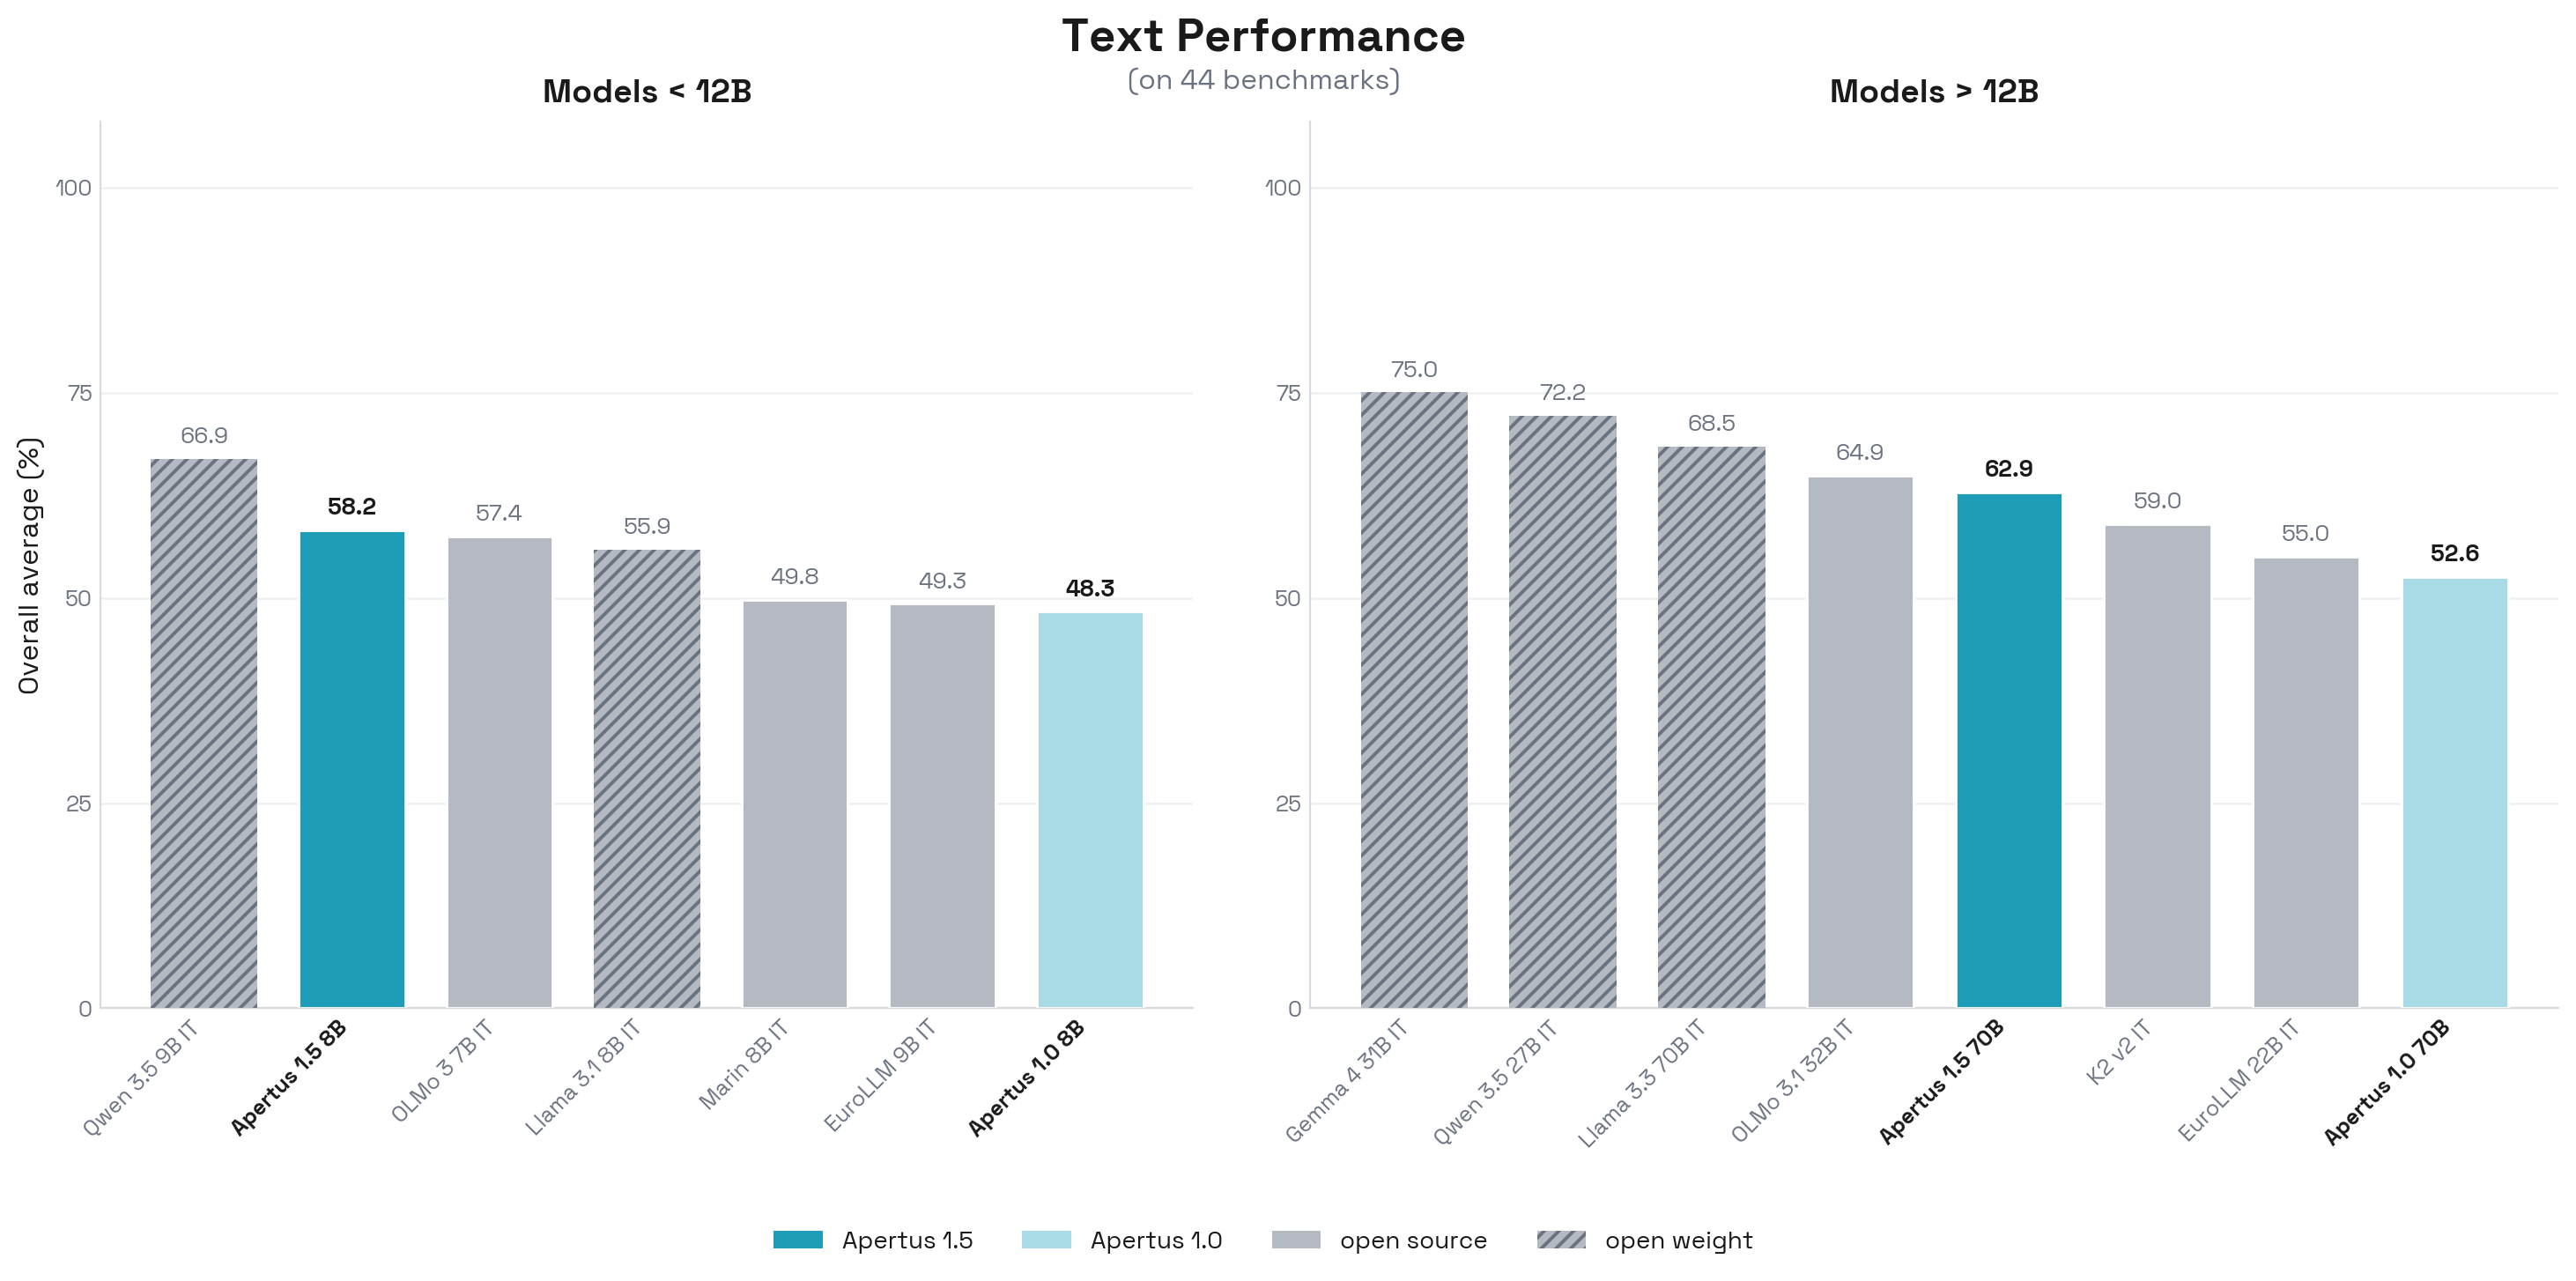
多模态评测通过 MLLM-eval-suite 流水线完成,该流水线融合了两个主要的多模态评测框架:lmms-eval 和 VLMEvalKit。我们还添加了一系列基于文本的基准测试,并扩展了针对翻译与多语言能力、安全性和工具使用能力的基准测试。这些内容可在我们的后训练评测代码库中找到,该代码库基于 lm-evaluation-harness 的一个分支。The multimodal evaluations are done through MLLM-eval-suite pipeline, merging two major multimodal evaluation frameworks lmms-eval and VLMEvalKit. We also added a series of text-based benchmarks, as well as extended benchmarking for translation and multilingual capabilities, safety, and tool use. These can be found in our post-training evaluation repository, based on lm-evaluation-harness fork.
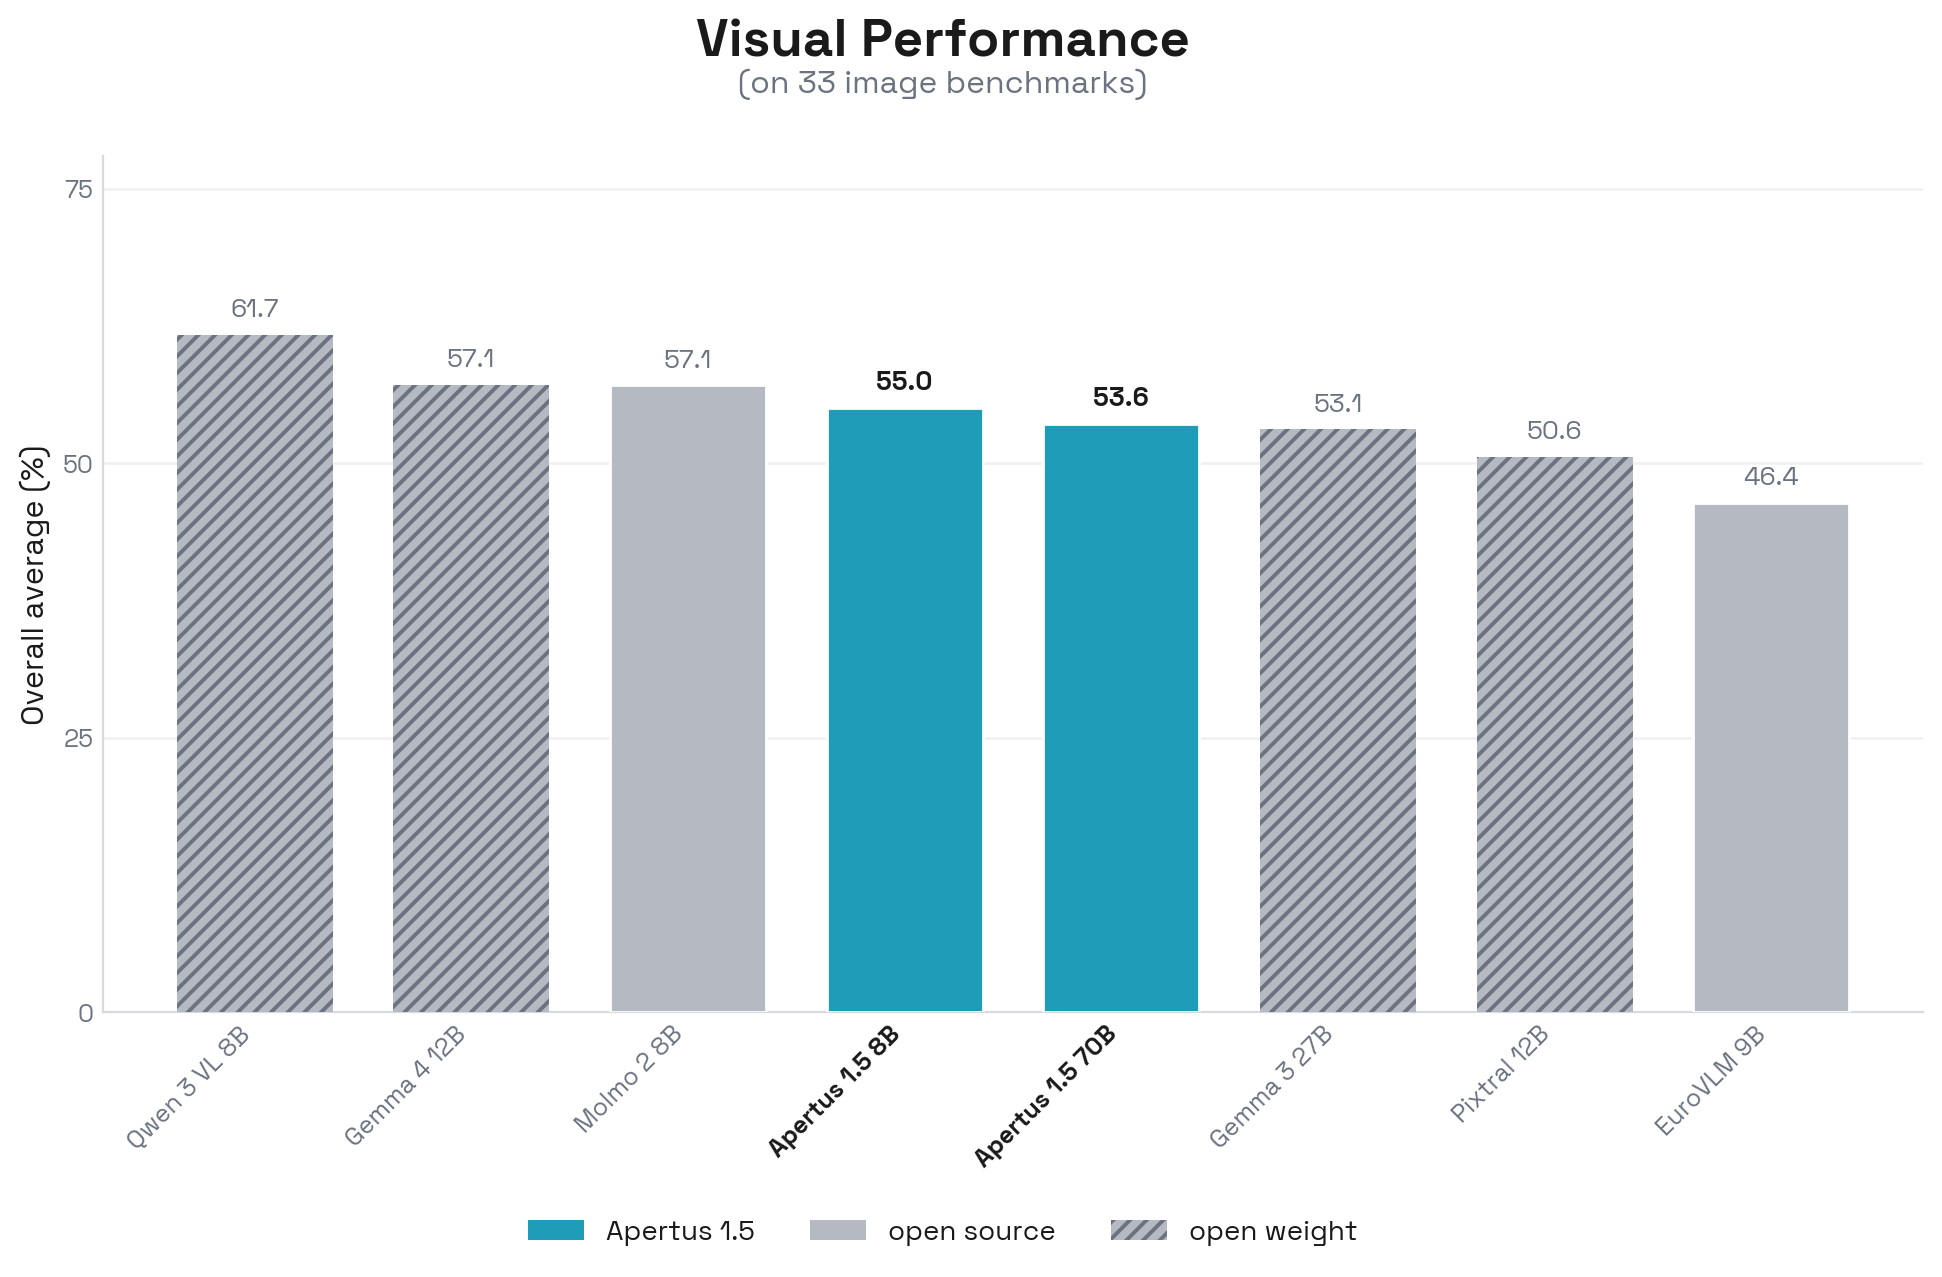
尽管仍落后于前沿开放权重模型,但这次新版本也显著提升了编码和指令遵循能力;Apertus 1.5 8B 在 IF 和多语言任务上的表现优于同等规模的开放权重模型。思考能力进一步提升了模型在 AIME 等推理难度较高的基准测试中的表现。该模型的多模态表现已接近 Gemma 4 12B 和其他当前的开放权重模型。在开放权重模型中,Apertus 1.5 的空间理解能力颇具竞争力;在开源模型中,其文档和图表理解能力也颇具竞争力。While still trailing frontier open-weight models, the new release has also significantly improved performance in coding and instruction following capabilities with Apertus 1.5 8B outperforming similarly sized open-weight models on IF and multilingual tasks. Thinking further improves performance on challenging reasoning-heavy benchmarks like AIME. The multimodal performance of the model is closer to Gemma 4 12B and other current open-weight models. Apertus 1.5 multimodal performance is competitive in spatial understanding among open-weight models and document/chart understanding among open-source models.
我们还要感谢合作伙伴和外部评估人员,感谢他们帮助高效评测 Apertus 的能力。尤其是,Apertus 1.5 在瑞士法律任务上表现出色,与领先的开放权重模型不相上下(博客、代码)。此外,在 Last Translation Benchmark 上,Apertus 1.5 8B 展现出的机器翻译能力可与 GPT-OSS-20B 媲美,并优于 Claude Haiku 4.5 或 Google 翻译等模型(排行榜、论文)。We also thank our collaborators and external evaluators for their help with efficient benchmarking of Apertus capabilities. In particular, Apertus 1.5 shows strong performance on Swiss Legal tasks, being on par with leading open-weight models (blog, code). Additionally, on Last Translation Benchmark, Apertus 1.5 8B presents machine translation capabilities which match GPT-OSS-20B and outperform models like Claude Haiku 4.5 or Google Translate (leaderboard, paper).
Evaluation Cards: Apertus ❤️ EvalEval
Apertus 与 EvalEval Coalition 合作,确保基准测试完全透明且可复现。我们以 Every Eval Ever (EEE) 架构发布 Apertus 1.5 的结果。该共享格式不仅记录得分,还记录了评估的执行者、模型的访问方式、生成设置,以及每项指标的解读方式:这些细节在排行榜中往往缺失,却常常能解释为何看似相近的分数实际存在差异。Apertus collaborates with the EvalEval Coalition to ensure fully transparent and reproducible benchmarking. We publish the Apertus 1.5 results in the Every Eval Ever (EEE) schema, a shared format that records not only scores, but also who ran the evaluation, how the model was accessed, the generation settings, and how each metric should be interpreted: details that are routinely missing from leaderboards and that often explain why similar-looking scores differ.
结果显示在下方的 Eval Card 中,其中将运行数据与基准测试和模型元数据整合为一份易于解读的记录;这些结果也可通过 Hugging Face Community Evals 获取。这与英国 AI 安全研究所用于公开发布评估结果的是同一套基础设施。由于我们的文本评估是在 lm-evaluation-harness 的公开分叉版本上运行的,而 EEE 为其提供了专用转换器,因此任何人都可以在相同设置下重新运行评估,并将结果与我们的数据进行比较。The results are shown in the Eval Card below, which combines the run data with benchmark and model metadata into one interpretable record, and are also available through Hugging Face Community Evals. This is the same infrastructure the UK AI Security Institute uses to publish its evaluations openly. Since our text evaluations run on our public fork of lm-evaluation-harness, which EEE supports with a dedicated converter, anyone can rerun them and compare their numbers against ours under identical settings.
结构化评估报告不仅对研究很重要。EvalEval 已将评估卡与 AI 治理要求进行了对应,包括《欧盟人工智能法案》第 55 条和《通用人工智能实践守则》,并发现 EEE 架构能够呈现这些框架要求的 60 项评估报告要素中的 56 项。这与我们发布 Apertus 的现有做法相契合:除模型外,我们还会发布《训练内容公开摘要》,并自愿提供《实践守则》文件。机器可读的评估记录是顺理成章的下一步:让监管机构、部署者和研究人员更容易找到、解读和比较模型背后的证据。Structured evaluation reporting also matters beyond research. EvalEval has mapped Evaluation Cards to AI governance requirements, including Article 55 of the EU AI Act and the GPAI Code of Practice, and found that the EEE schema can represent 56 of the 60 evaluation-reporting elements these frameworks call for. This fits how we already release Apertus: alongside the models, we publish a Public Summary of Training Content and, voluntarily, a Code of Practice document. Machine-readable evaluation records are a natural next step: making it easier for regulators, deployers, and researchers to find, interpret, and compare the evidence behind a model.
我们致力于通过 Eval Cards 和 EEE schema 推动可复现、透明的评估,并鼓励其他模型开发者也以相同方式报告结果,以便跨模型和组织比较得分。We are committed to promoting reproducible and transparent evaluation through Eval Cards and the EEE schema, and encourage other model developers to report their results in the same way, so that scores can be compared across models and organizations.
Apertus 1.5 可复现性 Apertus 1.5 Reproducibility
所有训练方案、消融实验和数据混合均记录在《技术报告》中。我们希望通过公开 v1.5 的训练流程并使其易于获取,推动开放模型开发的普及。中间检查点托管在我们的 Apertus 1.5 Hugging Face 集合中,包括基础权重、SFT、RLVR 和 DPO 检查点;我们精选的训练数据混合及自定义数据集则收录在 Apertus 1.5 数据集集合中。分享这些内容有助于研究人员探究各个阶段如何改变模型行为。All recipes, ablations, and data mixtures are documented in the Technical Report. We aim to popularize open model development by making the v1.5 training process public and accessible. Intermediate checkpoints are hosted in our Apertus 1.5 Hugging Face collection, including the base weights, SFT, RLVR and DPO, as well as our curated training data mixes/custom datasets in Apertus 1.5 datasets collection. Sharing them allows researchers to investigate how each stage changes the model behavior.
该报告涵盖了大量消融实验,探究后训练数据在不同阶段所产生的影响。我们观察到,在监督微调(SFT)期间与文本数据混合的多模态数据有助于提升所有模态的表现。我们还发现,多模态推理过程的益处在后续仅使用文本的强化学习中依然得以保留:与从仅使用文本数据训练的检查点开始相比,从使用多模态推理过程训练的 SFT 检查点开始进行强化学习,能够更大幅度地提升数学能力;而且这种在推理任务上的优势在整个训练过程中始终存在。The report covers numerous ablations on the effect of post-training data in different stages, where we observed that the multimodal data mixed in together with text data during SFT helps improve across all modalities. We also find that the benefits of multimodal reasoning traces survive the subsequent text-only reinforcement learning: starting from an SFT checkpoint trained with multimodal traces, RL improves mathematics more than when starting from a text-only checkpoint, and the advantage on reasoning tasks persists throughout training.
| Models | 8B | 70B |
|---|---|---|
| Pre-training (long-context base) | Apertus-v1.5-8B-base | Apertus-v1.5-70B-base |
| Supervised finetuning (SFT) | Apertus-v1.5-8B-SFT | Apertus-v1.5-70B-SFT |
| Reinforcement learning (RLVR) | Apertus-v1.5-8B-RLVR | Apertus-v1.5-70B-RLVR |
| Preference alignment (DPO) | Apertus-v1.5-8B-DPO | Apertus-v1.5-70B (final) |
| Charter alignment (SDPO) | Apertus-v1.5-8B (final) | – |
| Stage | Data | Code / recipe |
|---|---|---|
| Pre-training: Stages 1–2 (unpaired, paired) | All sources with versions and licenses in apertus-data-transparency; vision and audio processing recipes in multimodal-data | Megatron-LM, launch scripts in pretrain-code, apertus-omni-tokenizer, benchmark-image-tokenizer, benchmark-audio-tokenizer (incl. interleaved speech–text builder) |
| Pre-training: Stage 3 (cooldown) | apertus-data-transparency; curated image datasets NASA, Our World in Data, Smithsonian, swisstopo | Megatron-LM, launch scripts in pretrain-code |
| Long-context extension | apertus-data-transparency; synthetic long-context tasks in LongContextQA | Megatron-LM, launch scripts in pretrain-code |
| SFT | Apertus-v1.5-SFT-mix (multimodal SFT mix listed in the report) | posttraining-data, Megatron-LM (SFT launch scripts) |
| Long-context SFT | Subsets of the SFT mix (listed in the report), plus LongContextQA tasks | Megatron-LM |
| RL (RLVR) | Mixture listed in the report | verl, verl-recipe |
| DPO | Apertus-v1.5-Preference-Pool (annotated completions), Apertus-v1.5-Preference-Data (pairs) | posttraining, verl |
| SDPO (charter alignment, 8B only) | gretelai/gretel-safety-alignment-en-v1 | self-distillation |
模型可用性 Model Availability
Proton Lumo 和 Infomaniak Euria 是两款广泛使用的应用,近期已集成 Apertus 1.5。这些部署也与其他项目一同收录在 Community Showcase 中——可在此讨论帖中预览。Proton Lumo and Infomaniak Euria are two widely used apps that have recently integrated Apertus 1.5. These deployments are linked in the Community Showcase among others - see this discussion thread for a preview.
包括 Swisscom、Infomaniak、Phoeniqs 在内的多家服务提供商,以及我们《正式发布指南》中列出的其他公司,已宣布将以 API 的形式向开发者开放 Apertus 1.5。报告还详细介绍了我们如何与外部评估人员合作,对模型进行测试和准备。Access to Apertus 1.5 in the form of an API for developers has been announced by a range of providers, including Swisscom, Infomaniak, Phoeniqs, and other companies listed in our General Availability guide. The report also provides details on how we work with external evaluators to test and prepare the models.
有关运行这些模型的技术说明,请参阅 Hugging Face 上 Apertus 各版本的模型卡以及我们的快速入门指南。Technical instructions for running the models are in the model cards of the Apertus releases on Hugging Face and in our Quickstart guide.
如何参与其中 How to Get Involved
感谢您阅读这篇博客文章并成为我们社区的一员!我们刚刚在 Hugging Face 分析数据中庆祝了下载量突破 500 万 🤗,而且我们的脚步不会放慢。在近期于苏黎世举办的 AI+X 峰会上,我们的团队公布了 Apertus 2.0 的路线图:采用稀疏/MoE 架构,总参数量约为 600B,延长训练周期,并将智能体、数学和编程列为重点方向。Thank you for reading this blog post and being part of our community! We just celebrated five million downloads in our Hugging Face analytics 🤗 and are not slowing down. At the recent AI+X Summit in Zurich, our team announced the roadmap for Apertus 2.0: sparse/MoE architecture, ~600B total parameters, extended training schedule, with agents, mathematics and coding as priorities.
总之,我们诚邀您阅读我们的报告、下载模型、探索中间检查点、微调权重,并复现我们的评估结果。对于我们的出版物或网站常见问题中尚未涵盖的问题,我们始终欢迎您提出;我们也非常希望了解,您认为社区最需要我们今后深入探讨哪些主题。In summary: we invite you to read our report, download the models, explore the intermediate checkpoints, finetune the weights, and reproduce our evaluations. Questions that are not already covered in our publications or website FAQ are always welcome, and we would also love to hear which topics would be most useful to the community for future deep dives.
如果您使用 Apertus 进行开发或使用 Apertus,请填写 Showcase 表单,并通过 Contact 页面上的方式与我们联系。我们期待展示更多作品、了解您正在开发什么,并听取您对如何改进 Apertus 的建议!If you build with or use Apertus, please fill out the Showcase form, and reach out through the options on our Contact page. We are looking forward to highlighting more work, learning what you are building, and hearing how Apertus can be improved!
引用 Citation
Project Apertus, et al. “Apertus 1.5: From Open Text Models to Open Multimodal Reasoners.” arXiv:2610.15542. Preprint, arXiv, October 11, 2026. https://doi.org/10.48550/arXiv.2610.15542.
@misc{apertus2026apertus15opentext,
      title={Apertus 1.5: From Open Text Models to Open Multimodal Reasoners},
      author={Project Apertus and Yixuan Xu and Yassine Turki and Vinko Sabolčec and Valentina Pyatkin and Tommy Chu and Sven Najem-Meyer and Sean F. Carroll and Robert Smith and Raphael Kreft and Oscar Alessandro Tazza and Oleg Lavrovsky and Nicola Irmiger and Matteo Santelmo and Marian Schneider and Juan García Giraldo and Hanna Yukhymenko and Eduard Ďurech and Davit Melikidze and Dani Tamayo and Bettina Messmer and Aryan Ahadinia and Anunay Yadav and Allen Huang and Ahmad Fraij and Alessandro Bombarda and Alex Padula and Alexander Hägele and Alexander Sternfeld and Anna Hedström and Anna Kosovskaia and Arthur Wuhrmann and Arundhati Balasubramaniam and Badr Al Mahouri and Barna Pasztor and Bartosz Szostakiewicz and Bich Ngoc Doan and Bryan Schmid and Burak Sezen and Camille Challier and Clément Charmillot and Dana Shayakhmetova and Daniel Perruchoud and David Brüggemann and David Isztl and Elia Palme and Emma Anastassova and Fabian Bösch and Faruk Zahiragić and Fawzi Roberto Mohamed and Fiona Panicali and Florian Kolly and Flynn Guerra and Francesco Monti and Frederike Lübeck and Gennaro Oliva and Haofeng Yang and Haoliang Shang and Helen El Khoury and Henrique Mendonça and Jannis Vamvas and Jérome Landolt and Jessica Lam and Jingchun Xiao and Jonathan Coles and Joshua Oyebanji and Khanh Nguyen and Konstantinos Pitas and Lasse B. Strand and Li Mi and Loïc Deslarzes and Lorenzo Baggi and Lorenzo Noci and Luca Baumann and Luca Sartori and Lukas Drescher and Marco De Negri and Marco Passerini and Mark Klein and Marko Stojanovic and Martin Majsec and Matin Ansaripour and Mattea Busato and Mauro Pellonara and Max Neuwinger and Michael Graber and Michal Tešnar and Michelle Wastl and Miguel Gila and Mikolaj Boronski and Morgane Magnin and Moritz Reihs and Mukhammadali Sayfiddinov and Nathan Ranchin and Nicolas Cuveillier and Oscar Wohlfahrt and Qianqian Zou and Rada Kamysheva and Rita Sevastjanova and Roman Machacek and Sebastian Keller and Simon Matrenok and Simon Pierre and Stefano Schuppli and Suei-Wen Chen and Szabina Horváth-Mikulas and Taliesin Perez and Thilo Spinner and Thomas Kleine Buening and Tim Robinson and Tymoteusz Kwiecinski and Vilém Zouhar and Vinzenz Thoma and Xiaozhe Yao and Yannick Metz and Yuhei Fukuhara and Yusif Askari and Zixuan Chen and Alexander Ilic and Ana Klimovic and Andreas Krause and Andrei Kucharavy and Elliott Ash and Joost VandeVondele and Martin Rajman and Mennatallah El-Assady and Thomas Schulthess and Timo Kehrer and Torsten Hoefler and Antoine Bosselut and Martin Jaggi and Imanol Schlag},
      year={2026},
      eprint={2610.15542},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2610.15542},
}