
神经网络其实已经很干净
原题Neural Networks Are Already Clean
读前速览
对神经网络可解释性的重新审视显示,领域内关于多语义性和超位置的经典案例被误读了;实际上,网络表现出单一的分形学习原理,神经元通过递归泛化不断成长,使其本质上是干净的,适合直接进行机制性研究。
‘cat-car’神经元并非任意混合,而是对特定视觉特征‘V’形状的专门检测器,该特征在两种情境中均会出现。
神经元的响应由其检测到的特征的几何相似性驱动,而不是由无关概念的随机分配驱动。这表明网络的分组在物理上是有意义的,并遵循单一且一致的学习原理。
领域对超位置作为多语义性解释的依赖过早且不正确。
用于支持超位置的证据‘cat-car’电路被误解了。该电路实际上展示了一种干净的层级结构,其中一个通用特征‘V’被细化为特定的子特征‘猫’和‘汽车’,而不是无关信号的混乱混合。
现代神经网络的可解释性比之前认为的要高得多。
模型架构和训练的进步使得绝大多数神经元‘高达 99%’都易于解释。剩下的‘杂乱’神经元并非任意的,而是正在经历自然的精炼过程‘递归泛化’,使得整个网络都适合直接分析。
完整摘要
本文认为神经网络被视为‘纠缠的结’的性质是一种源于早期、存在缺陷的分析的误解。通过重新审视著名的‘cat-car’神经元和其他多语义性例子,作者证明这些并非任意特征打包的实例,而是连贯递归泛化过程的结果。这意味着神经网络可以直接研究,无需复杂的分解,因为其机制本身就以可读的方式结构化。
目录 · 40 节
简而言之The Short Version
我想我有关于神经网络本质的好消息。I think I have good news about the nature of neural networks.
在花了许多个月研究图像模型和语言模型中的神经元与回路后,我开始相信,网络自身的机制就是可读的构件,而机制可解释性的前景可能远比我担心的要好。那些让包括我在内的许多领域研究者相信网络会随意打包概念的、有关多义性和叠加的经典证据,其实被误读了。看似随意的打包,大多是一种我称之为“递归泛化”的模式,而这种模式远没有那么令人担忧。这意味着我们可以直接研究网络,而不必先把它们梳理清楚。神经网络本身已经很清晰。After many months studying neurons and circuits in image and language models, I’ve come to believe a network’s own mechanisms are its legible building blocks, and that the outlook for mechanistic interpretability may be far better than I’d feared. The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread. What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning. This means we can study networks directly, instead of first untangling them. Neural networks are already clean.
研究机制可解释性至少有两种方法。第一种是在网络本身上开展快速的常规科学研究:观察网络的神经元和回路,研究它们之间的关系,追踪数据如何在其中流动,并以智能体规模开展实验来检验解释。第二种则从一份假设特征清单出发,尝试将这些特征全部提取出来,同时设计越来越复杂的重建目标,通常会忽略原始网络。There are at least two ways to approach mechanistic interpretability. The first is rapid normal science on the network itself: look at a network’s neurons and circuits, study how they relate, watch data flow through them, and run experiments at agentic scale to test explanations. The second starts from a list of hypothesized features and tries to extract them all, designing increasingly sophisticated reconstruction objectives and usually ignoring the original.
这个领域最初采用第一种方法,后来又退回到第二种,因为神经网络看起来像是纠缠在一起的乱麻。我们有一些多义神经元的典型例子——这是对那些似乎承担多种互不相关功能,或看起来根本无法理解的神经元的统称。最著名的例子来自一个图像模型:某个神经元对猫脸和汽车前脸都会作出响应。而这个领域早期的模式生物 InceptionV1,其最后一层似乎充斥着各种随意混杂的特征,让人不知该如何研究:几乎没有哪个神经元是容易解读的。The field began with the first approach and fell back to the second because neural networks seemed to be tangled knots. We had canonical examples of polysemantic neurons, the broad name for a neuron that appears to have multiple unrelated jobs or that looks impossible to understand. The most famous one, in an image model, responded to both cat faces and the fronts of cars. And the last layer of the early field’s model organism, InceptionV1, seemed so full of arbitrary mixtures it wasn’t clear how to study it: almost none of the neurons were easily interpretable.
对多义性的主流解释是叠加。它提出了一种新的学习原理:当神经网络的神经元不够用时,它就不再把相关的事物归为一组,而是开始把无关的事物折叠到一起,只要它们彼此不会干扰就行。结果就形成了某种结:网络本可以用许多种几乎同样好的方式折叠这些事物,因此某个神经元把哪些事物归为一组,几乎说明不了什么。你必须先解开这个结,才能研究其中的任何东西。实际操作中,这意味着训练第二个模型——例如稀疏自编码器这样的分解模型——来近似网络解开后的样子,并研究这个模型。如果网络确实打了结,可能就别无选择。The leading explanation for polysemanticity was superposition. This proposed a new learning principle: when a neural network runs out of neurons, it stops grouping related things together and instead begins folding unrelated things together, simply because they don’t interfere. The result is a kind of knot: the network could have folded in many almost equally good ways, so which things a neuron groups together tells you almost nothing. You have to unfold the knot before you can study anything. In practice that means training a second model – a decomposition such as a sparse autoencoder – to approximate the network as it would look unfolded and studying that instead. If the network really is knotted, there may be no alternative.
一个主要结论是,叠加并不是 InceptionV1 表现异常的正确解释。架构问题导致后续层出现了过载。薄弱的可解释性工具又放大了这些问题,让后期层看起来杂乱无章。此后,为了帮助深层更好地学习而进行的架构改进,却意外地让模型变得更容易解释。我们最初研究 InceptionV1 时,发现它最后一层几乎没有可解释的神经元。但经过这些常规改进,且模型规模和训练数据都没有变化后,最后一层中 99% 到 100% 的神经元都很容易解释,整个模型从头到尾也基本清晰可读。这是第一个我觉得自己大体上理解了的非平凡神经网络;你可以在这里浏览它。我训练了规模相差 300 倍的多个版本,而它们在所有规模下都基本清晰可读。网络空间较小时,不会把互不相关的事物揉在一起;它的神经元只是覆盖更粗粒度的概念,比如一个汽车神经元涵盖多种汽车。空间更大时,这个神经元就会分化成许多针对特定汽车的神经元。因此,问题并非存在第二种学习原理,而只是第一种学习原理出现了普通的学习失败,而且很容易修复。One main result is that superposition was the wrong explanation for InceptionV1. Architectural problems made later layers overflow. Weak interpretability tools amplified these problems, making the late layers seem incoherent. Since then, architectural changes designed to help deep layers learn better have had the unintended effect of making them more interpretable. When we first studied InceptionV1, we found almost no interpretable neurons in its last layer. But with these ordinary improvements, and no change to model size or training data, 99-100% of neurons in that last layer are easily interpretable and the model is broadly legible the whole way through. It’s the first non-trivial neural network I feel I mostly understand; you can browse it here. I trained versions of it across a 300× range in size, and it’s broadly legible at every scale. With less room, the network doesn’t fold unrelated things together; its neurons just cover coarser-grained concepts, like one car neuron covering many kinds of car. With more room, that neuron differentiates into many specific cars. So the problem wasn’t the presence of a second learning principle, it was just an ordinary learning failure of the first one, and it’s easy to fix.
视觉领域关于多义性和叠加的经典案例也都是错误的。2019 年,Chris Olah 和我找到了那个电路;它最初在《Zoom In》[4]《Zoom In:电路导论》Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. 参考文献 ↓ 中被作为叠加现象介绍。它展示了一个车特征似乎扩散到一组彼此无关的狗神经元中。这是我们展示过的唯一一个,也是我见过的唯一一个。我们当时认为,网络把汽车放进了一个高维藏匿空间,以便下游神经元读取出来。但没有任何东西会读取这种组合。它并没有藏起任何东西;这只是普通的泛化与组合。据我所知,还没有人发表过第二个结构形态正确的电路。The canonical vision examples of polysemanticity and superposition were errors too. In 2019, Chris Olah and I found the circuit that was originally introduced as the superposition phenomenon in Zoom In[4]Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓. It showed a car feature appearing to spread into a set of unrelated dog neurons. It was the only one we showed, and the only one I ever saw. We read it as the network placing the car in a high-dimensional hiding place, for downstream neurons to read back out. But nothing reads that combination. It wasn’t hiding anything; it was ordinary generalization and composition. To my knowledge, no one has published a second circuit with the right shape.
现代语言模型的可解释性也远高于人们通常的认知。Anthropic 的《走向单义性》[10]《走向单义性:利用字典学习分解语言模型》,Bricken, T., Templeton, A., Batson, J., 等,2023 年。Transformer Circuits Thread。参考文献 ↓(2023)研究了一个小型单层模型,发现神经元的中位数评分为 0 分(满分 14 分),也就是说,评分者无法提出任何假设。我在 OpenAI 发起的自动化可解释性项目[8]《语言模型可以解释语言模型中的神经元》,Bills, S., Cammarata, N., Mossing, D., 等,2023 年。OpenAI。参考文献 ↓(同为 2023 年)发现,即使采用最宽松的衡量标准,也只有约 1.7% 的神经元具有可解释性。Modern language models are also far more interpretable than generally believed. Anthropic’s Towards Monosemanticity[10]Towards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. References ↓ (2023), studying a small one-layer model, gave the median neuron a 0 on its rubric out of a possible 14, meaning the rater couldn’t form any hypothesis. The automated interpretability project[8]Language Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I started at OpenAI (also 2023) found about 1.7% of neurons interpretable by our most generous measure.
借助更好的工具和现代模型,情况看起来大不一样。在对 Qwen3-32B 进行的初步审计中,我们估计,大约 90% 的神经元极点只有一项主要功能,通常还带有一些相关的小分支;另有约 7% 有两项相关功能;只有约 2–4% 尚未得到理解。1 关于这个数字的一点说明:具有单一功能的神经元占比,会随着你设定的弱激活计数阈值、分析深度、子电路密度,以及你如何界定“同一件事”而变化。对弱激活追查到什么程度,是一个很重要的因素。下文有一节专门介绍弱激活。它往往会增加“相关事物”的数量,而不会太影响神经元是否在判断某种可辨识的事物。例如,特朗普神经元的弱激活会涵盖 MAGA 帽子和与他有关的人;泰坦尼克号神经元的弱激活则会涵盖更一般的航海故事,或蒸汽机以及那个时代的其他技术。
此外,我们还需要考虑是否关注激活百分位,或最强激活所占的比例。总体而言,我认为应该相信神经元学到的东西,以及它天然的稀疏性、激活范围等等。可我以前大多并不这么认为!我不太赞成试图在所有神经元之间统一标准。我觉得如今百分位数更常见,可能是因为更容易理解。反过来的情况也有。例如,观察泰坦尼克号神经元的“无关功能”时,你常会发现它是在检测接下来是否会出现“船”这个词。工具没能发现这一点,因为它在判断上下文时只查看前文。深入考察这些“无关功能”时,几乎总会发现类似情况。要构建一个不完美的工具很容易。
总的来说,我不认为得出一个单一分数有多重要。但移除这个分数后,早期审阅者觉得失去了参照,哪怕是一个大致数字也好。在我仔细考察过的那些样本中,考虑强激活后,非任意混合的比例更接近 97%,但这些样本相对较小。总之,把所有情况浓缩成一个“纯净度”分数,应当被视为对神经网络所处状态的大致指示,而不是一个精确的指标,既不应直接以它为优化目标,也不应过分看重它。这篇文章有很大一部分内容,是为了减少对问题的降维处理,依据各个神经元和电路的模式、深度、作用等,区别对待它们。即便如此,一个粗略的数字还是有用的。稠密模型和混合专家模型看起来大致相似。在参数量达到数万亿的模型(如 Kimi K3)中,我们也发现了类似结果;配套论文会对此作更详细的介绍。这些百分比将一个高维图景压缩成少数几个数字,而具体数字取决于你如何设定“同一件事”的判断阈值——比如是否把两种语言中密切相关的习语归为一类。我认为,可解释性研究中的许多问题并不取决于这一点。更重要的是,事物最初为何会共用同一个神经元。With better tools and modern models, the situation looks quite different. In preliminary audits of Qwen3-32B, we estimate that roughly 90% of neuron poles have one main job, often with small related offshoots; another ~7% have two related jobs; and only ~2-4% are not yet understood1A note on this number: the share of neurons with one job varies depending on how you set the threshold for counting weak activations, depth, density of sub-circuits, and what you view as “one thing”.
How far to go into weak activations is a big factor here. There’s a section describing weak activations below. It tends to increase how many “related things” there are, more than whether the neuron is a judgement of something legible. For instance, the Trump neuron’s weak activations bring in MAGA hats and people related to him. The Titanic neuron’s weak activations bring in stories of more general voyages, or steam engines and other technologies of the era.
There’s also the question of whether to care about activation percentiles, or fraction of the strongest activations. In general I think what the neuron learns should be trusted, its natural sparsity and activation ranges and so on. Which I used to mostly not believe! I’m somewhat against trying to standardize things across all neurons. Percentiles are more common today, I think because they’re easier to think about.
It goes the other way too. For instance, when you look at the Titanic neuron’s “unrelated jobs,” it’s often detecting that “boat” comes next. The tool missed this because it only looked backward when judging context. When we look at these “unrelated jobs” in depth, it’s almost always this kind of thing. It’s easy to build an imperfect tool.
Overall, I don’t think coming to a single score is actually that important. But when it was taken out, early reviewers felt unanchored without even a rough number. In the sets I’ve looked at more closely, considering strong activations, it’s closer to 97% non-arbitrary mixtures, but these are relatively small samples.
Overall distilling everything into one “cleanliness” score should be taken as a broad pointer to the regime a neural network is in, rather than something precise to either optimize directly or hold too tightly. A lot of this essay is for being less dimensionality reduced, treating each neuron and circuit differently, according to their motifs, depth, role etc. Despite this, a rough number can be useful.. Dense and Mixture of Experts models seem roughly similar. We found similar results in models up to trillions of parameters, like Kimi K3, which the companion paper will cover in more detail. These percentages compress a high-dimensional picture into a few numbers, and the precise number depends on where you set thresholds for what counts as “one thing” – like whether you lump together closely related idioms in two languages. I don’t think much in interpretability hangs on that question. What matters a lot more is why things share a neuron in the first place.
剩下那些表面上的多义性,大多似乎都属于一种我称为“递归泛化”的模式。它很简单:神经元会不断生长,长出分支,就像树枝会长出小枝。例如,一个检测到“iy”的神经元,后来开始检测“diy”,再后来又开始检测“do it yourself”,而后者根本不含“iy”。这个想法最初出现在我参与撰写的一篇论文《Multimodal Neurons》里一个被遗忘的小节中 [3]《人工神经网络中的多模态神经元》(Multimodal Neurons in Artificial Neural Networks),Goh, G., Cammarata, N., Voss, C., et al., 2021。Distill。参考文献 ↓(2021)。当时,我还没有观察过神经元在训练过程中的生长。如今观察起来容易多了,而且在我见过的各种情况下,这个想法都成立。就连最初的 InceptionV1 也并非盘根错节。当我重新训练它的原始架构——它仍会产生杂乱的深层结构——并追踪我能找到的最难以解读的神经元时,结果发现,它们是在局部过度生长,延伸到了合理且相邻的领域。Most of the remaining apparent polysemanticity seems to be a motif I call recursive generalization. It’s simple: as a neuron grows, it sprouts offshoots the way a tree branch sprouts sub-branches. For instance, one neuron that detected “iy” grew to detect “diy,” and then “do it yourself,” which doesn’t contain “iy” at all. This idea first appeared in a forgotten subsection of a paper I worked on called Multimodal Neurons[3]Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓ (2021). At the time, I hadn’t watched neurons grow over training. Now it’s easier, and it holds up everywhere I’ve seen. Even the original InceptionV1 wasn’t knotted. When I retrain its original architecture, which still produces messy deep layers, and follow the least legible neurons I can find, they turn out to be overgrowing locally into reasonable, adjacent territory.
关于多义性有两种解释,而我都曾参与提出。在某些方面,它们恰好相反:泛化会把相似的事物归为一类,叠加则会把无关的事物归为一类。整个领域押注的是叠加,直到最近我也这么认为。但我现在觉得,递归泛化基本上是正确的。归根结底,学习原则仍然只有一个。它依旧是泛化,只不过事实证明,泛化具有分形结构。这就没那么令人担忧了:我们可以从事物被归为一类的方式中学到东西,而两个处于叠加状态的项目则无从学起。既然泛化本身具有分形结构,我们的解释也可以如此:先从基本解释入手,想了解得更多时再深入细看。从这个意义上说,只要观察得足够仔细,几乎整个网络都是可解释的,尤其是考察它在训练过程中是如何成长的。So there were two explanations for polysemanticity, and I helped propose both. In some ways, they’re opposites: generalization groups similar things together and superposition groups unrelated things together. Superposition is the one the field bet on and, until recently, so did I. But I now think recursive generalization was basically right. That leaves one learning principle after all. It’s still generalization, but it turns out generalization is fractal. That’s far less concerning: there’s something to learn from the way things were grouped, and nothing to learn from two items in superposition. And since the generalization itself is fractal, our explanations can be too: start with a basic explanation, then zoom in when you want to understand more. In that sense, almost the entire network is interpretable if we look closely enough, especially if we look at how it grew over training.
差距为什么这么大?我认为,几个常见问题叠加在了一起。2023 年的解释模型无法完成“提出猜想并进行检验”的循环;工具和指标都很薄弱,奖励的是能够模拟激活、而非真正正确的解释——两者往往并不一致;没人知道该期待出现哪些语言神经元模式,大家普遍也在寻找错误类型的东西;而且大多数研究使用的都是小型或简化模型。从某种意义上说,这些模型确实已经没有多少空间可用了,因此超叠加成了顺理成章的解释。但空间不足的网络不会因此改变学习原理;它的神经元只会变得更加宽泛,就像小型视觉模型中的神经元一样。一旦知道该找什么,宽泛的神经元通常很容易分解。缺少这方面的知识,再加上工具原始,它们看起来就像是随意混合的产物。Why was the gap so large? I think several ordinary problems compounded. The explainer models of 2023 couldn’t run the loop of conjecture and test; the tools and metrics were weak, rewarding explanations that could simulate activations rather than ones that were right, which often come apart; no one knew what language neuron motifs to expect, and people broadly looked for the wrong kinds of things; and most studies used small or simplified models. In a sense, those models really had run out of room, which made superposition the natural explanation. But a network short on room doesn’t switch learning principles; its neurons just get broader, as in the small vision models. Broad neurons are usually easy to break down once you know what to look for. Without that knowledge, and with primitive tools, they look like arbitrary mixtures.
可解释性研究有着令人惊讶的势头:就像拼图或填字游戏一样,你获得的任何理解都会开始约束系统的其他部分。起初,你看到的是一个单独的神经元。如果你无法理解它,其他方面也帮不上什么忙:电路和归因图只能通过其他你尚未理解的神经元来解释某个神经元。这会让入门变得困难。不过,一旦地图开始逐渐填满,进展就会出乎意料地顺利。如果你不确切了解某个神经元的作用,就可以研究它连接了什么、它周围的生态系统,以及——在混合专家模型中——它所对应的专家专精于什么。就像拼图逐渐成形一样,每块拼图都带来许多线索,而且这些线索结构清晰,便于通过实验验证。这就是为什么几乎空白和基本填满这两种状态都不足为奇;它们是自然的锚点。Interpretability has a surprising amount of momentum: like a jigsaw puzzle or crossword, any understanding you gain starts constraining the rest of the system. At first, you’re looking at a single neuron. If you can’t understand it, little else helps: circuits and attribution graphs only explain a neuron in terms of other neurons you don’t understand yet. This can make getting started hard. Once the map starts to fill in, though, it goes surprisingly well. If you don’t understand exactly what a neuron does, you can study what it connects to, the ecosystem around it, and – in a mixture-of-experts model – what its expert specializes in. As with a puzzle coming together, every piece comes with many clues, and they’re well structured and easy to run experiments against. That’s why nearly empty and mostly filled in aren’t surprising places to be; they’re the natural anchors.
以一个追踪“买到便宜货后,发现它比昂贵的替代品更好用时产生的正义感”的神经元为例。追踪这种情绪或社交线索的神经元,是我们发现的最常见的神经元之一。想象一下,你发现了这个神经元,却不了解任何语言神经元的模式,也没有可供参考的电路,因为它附近的神经元大多尚未得到解释。大多数人和智能体都以为,神经元会通过对名词放电来检测名词,但它们大多并不会。看看这个神经元在哪些情况下放电最强,你会发现一堆看似毫不相关的逗号。Take a neuron that tracks ‘a sense of righteousness when a bargain purchase turns out to work better than the expensive alternative’. Neurons that track a feeling or social cue like this are some of the most common we’ve found. Imagine finding this one with no knowledge of language neuron motifs and no circuits to lean on, because few neighboring neurons are explained yet. Most humans and agents expect neurons to detect nouns by firing on them, which they mostly don’t. Look at where this one fires most strongly, and you see a pile of seemingly unrelated commas.
现在想象一下,地图已经大致填满了。你知道,许多神经元会检测微妙的情绪或社交语境,而且它们触发时往往不是因为承载情绪的词,而是因为标点符号,比如逗号——模型会在这里概括句子的含义;或者因为情绪对预测接下来会发生什么至关重要之前的那个词。于是,你转而阅读周围的句子,并检查它的引导效应(把这个神经元调高时,模型会写出什么),发现两者高度吻合。你向上游查看它是如何构建的,向下游查看它会产生什么作用,结果两边都吻合。你还会检查它的负极:哪些东西会让它的数值强烈转负;结果发现,要么是同一线索的一种细微变体,要么就是社交语境结束的时刻。你可以进行一些具体测试,比如检查它会对哪些商店自有品牌作出反应。以上任何一项都可能推翻这个解释,但它们最终都指向同一个地方。理解这个神经元,也会让你更清楚地把握更广泛的模式:研究了成千上万个检测微妙情绪和社交语境的神经元之后,你会开始知道下一个神经元大概是什么样的,这也是地图越往后填得越快的部分原因。Now imagine the map is mostly filled in. You know many neurons detect subtle feelings or social contexts, and that they often fire not on the words that carry the feeling but on punctuation, like commas, where the model summarizes what a sentence meant, or on the word just before the feeling matters for predicting what comes next. So you read the surrounding sentences instead, and check its steering effects (what the model writes when you turn the neuron up), which line up closely. You look upstream at how it’s built and downstream at what it does, and both line up. You check its negative pole, what pushes it strongly negative, and find a subtle variant of the same cue, or the moment the social context ends. You can run specific tests, like checking which store brands it responds to. Any of these could break the explanation, yet they keep pointing to the same place. And understanding this neuron sharpens the broader motif: after thousands of subtle-feeling and social-context detectors, you start to know what to expect from the next one, which is part of why the map fills in faster as it goes.
这对工具也同样奏效。当你只能看到网络的 2% 时,你无法判断工具究竟哪里出了问题;当你能看到其中大部分时,那些无法解释的部分就会直指工具本身。我和几位同事正是这样发现了 SwiGLU 神经元中的一种双重负向状态。据我们所知,此前无人注意到它,而将许多神经元混在一起的分解方法很可能会把它掩盖掉。It works on the tools too. When you can see 2% of a network, you can’t tell where your tools are broken; when you can see most of it, the unexplained remainder points straight at them. That’s how some coworkers and I found a double-negative regime in SwiGLU neurons that, as far as we know, no one had noticed, and that a decomposition mixing many neurons together would likely have hidden.
现代神经网络的坏消息是,它们规模庞大。好消息是,庞大也有助益:随着图谱逐渐填满,每种解释都会受到周围所有内容的严格约束,而且更大的模型会学到更专一、更容易识别的神经元。The bad news about modern neural networks is that they're enormous. The good news is that the enormity helps: as the map fills in, every explanation is tightly constrained by everything around it, and bigger models learn narrower neurons that are easier to recognize in the first place.
从这个意义上说,理解整个网络,可能比只理解我们最关心的部分更容易。首先,在仔细研究神经网络之前,很难知道该如何像神经网络那样思考。例如,“欺骗”是一个有用的初步分析框架,但促成模型欺骗行为的基本构件,可能具有与对齐相关的微观结构;如果不深入其中进行观察,就很难了解这些结构。其次,针对少数几种机制,就像在一张其他地方都空着的填字游戏里只填一行。这样做可行,也可能奏效,但没有交叉处作为参照,就很难知道答案是否正确。把整张填字游戏解出来——或者至少理解这些机制与之相连的网络中更广泛的部分——可能会更容易。In this sense, understanding the whole network may be easier than understanding just the parts we care about most. First, it’s hard to know how to think like a neural network until you’ve studied it closely. For instance, “deception” is a useful initial frame, but the building blocks that contribute to deceptive behavior by models probably have alignment-relevant microstructure that will be hard to know without going in and looking. Second, targeting a small set of mechanisms is like working on one row of an otherwise empty crossword. It’s doable, and might work, but without the crossings it’s hard to know whether you’re right. It may be easier to solve the whole thing – or at least the broader parts of the network these mechanisms connect to.
当我在现代卷积网络上运行这一流程时,它基本上奏效了。智能体能够绘制神经元和电路图,构建可供探索的显微镜并对其进行探索,彻底检验各种解释,还能追踪数十万张归因图。快速推进的常规科学从未在哪个环节陷入停滞。我现在觉得自己基本上理解了这些模型,至少知道无论有什么问题,都该从哪里着手;最终,整张填字游戏就这样被填满了。到目前为止,这一流程在语言模型上也奏效了,模型规模已达数万亿参数。由于规模实在太大,这些模型还远未被彻底破解,但我对扩展这一流程充满乐观。When I ran this process on modern convolutional networks, it basically worked. Agents can map out neurons and circuits, build explorable microscopes and explore them, test explanations thoroughly, and track hundreds of thousands of attribution graphs. There was never a point where rapid normal science broke down. I now feel I basically understand these models, at least enough to know where I’d start asking any question I had; eventually, the crossword just got filled in. So far it has worked in language models too, up to trillions of parameters. Those aren’t close to solved due to sheer size, but I’m optimistic about scaling the process.
这一切让我重新想起一个由来已久的愿望:不先试图修复或理清神经网络,而是通过研究其机制以及在机制之间流动的数据,直接理解它。综合起来,这一论证分为四个步骤。All of this has brought me back to an old hope: understanding a neural network directly, by studying its mechanisms and the data flowing between them, without first trying to fix or untangle it. Put together, the argument has four steps.
- 网络采用的是一种学习原理,而不是两种(即使并非处处如此,也几乎足以忽略不计,不影响研究),因此没有理由不能开始对它们进行常规的科学研究。Networks use one learning principle, not two (if not everywhere, then nearly enough that it doesn’t matter for study), so there’s no blocker to beginning ordinary science on them.
- 借助现代模型和工具,这项科学研究的进展远比大多数人预想的顺利。With modern models and tools, that science goes much better than most people expect.
- 理解会不断累积,因此随着地图逐渐完善,事情也会变得更容易。至少,网络自身的机制也应纳入工具箱。Understanding compounds, so it gets easier as the map fills in. At minimum, then, a network’s own mechanisms should be part of the toolkit.
- 高度推测性地说:这或许已经涵盖了我们所需的大部分内容,而且可解释性可能比我们原先设想的容易得多,甚至在近期就有望实现。Highly speculative: this might be most of what we need, and interpretability might be far more tractable, possibly in the near term, than we’ve assumed.
深度学习总体上一直遵循着这样的模式:规模大到惊人的简单方法,胜过巧妙的方法。Rich Sutton 将其称为“苦涩的教训”[22]《苦涩的教训》Sutton, R., 2019.《不完整的想法》。参考文献↓。或许可解释性也有一个苦涩的教训:扩大常规研究的规模,胜过精心设计一种巧妙的新分解方法。That’s been the pattern for deep learning in general: the simple thing at absurd scale beats the clever one. Rich Sutton called it the bitter lesson[22]The Bitter Lesson
Sutton, R., 2019. Incomplete Ideas. References ↓. Maybe there’s a bitter lesson for interpretability too: scaling ordinary investigation beats engineering a clever new decomposition.
一篇技术配套论文将更详细地介绍语言模型神经元实验,例如我们对现代非线性函数不同工作区间的发现,以及不同深度会出现哪些类型的电路模式。这篇文章则广泛涉猎多个方面,并推测这一切可能指向何方。A technical companion paper will offer a more detailed account of language model neuron experiments, such as what we’ve found about the different regimes of modern non-linearities and what kinds of circuit motifs show up at different depths. This essay glances at many places and conjectures about where it all might be pointing.
汽车与动物Cars and Animals
最著名的多义神经元是 InceptionV1 中的 4e:55,它看起来像是猫和汽车的随意混合。它曾在该领域一些阅读量最高的论文中被用作证据,说明神经元可能并不是合适的研究单位:从 2017 年的《Feature Visualization》[1] Feature Visualization,Olah, C., Mordvintsev, A. and Schubert, L., 2017. Distill. 参考文献 ↓,到《Zoom In》[4] Zoom In: An Introduction to Circuits,Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. 参考文献 ↓。在我参与合著的《Zoom In》中,我们直言,它“并非是在响应汽车和猫脸之间的某种共同特征”。2 在《Multimodal Neurons》中,我们几乎也得出了同样的结论。我们曾问,这个神经元是否可能是在响应某种共有特征,“或许猫眼和车灯看起来相似”;但随后根据特征可视化中出现的胡须和镀铬部件,认定它“确实是 OR(cat, car)”。我们寻找共同形状的方向是对的,但我认为我们低估了泛化的范围。共有特征其实是 V。我认为胡须误导了我们,因为泛化发生在高层模式内部。V 神经元确实会接收猫相关电路的信号,而特征可视化的作用是提高激活值,因此一旦找到通往猫的路径,它就会把这条路径带来的一切都加上。胡须也随之出现,尽管神经元并不“想要”它们。在下游,汽车识别器确实会通过 V 神经元接收到一点猫信号,但它对输出的影响微乎其微:单个猫检测器触发本身作用不大,因为许多检测器会协同工作,因此网络根本不需要用负权重来抵消它。要看出共有模式,你必须将神经元输入中的共同部分可视化,而不是单独观察这个神经元。The most famous polysemantic neuron is 4e:55 of InceptionV1, which looked like an arbitrary mixture of cats and cars. It’s been brought up as evidence that neurons might not be the right unit of study in several of the field’s most widely read papers, from Feature Visualization[1]Feature Visualization
Olah, C., Mordvintsev, A. and Schubert, L., 2017. Distill. References ↓ in 2017 to Zoom In[4]Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓. In Zoom In, which I co-authored, we said outright that it “isn’t responding to some commonality of cars and cat faces”.2In Multimodal Neurons we came very close. We asked whether the neuron might be responding to some shared feature, “perhaps cat eyes and car lights look similar,” then decided from the feature visualization’s whiskers and chrome that it was “genuinely OR(cat, car).” We were right to look for a shared shape, but I think we underestimated how far generalization reaches. The shared feature was the V. I think the whiskers misled us because generalization happens inside high-level patterns. The V neuron really does take in cat circuitry, and feature visualization’s job is to raise the activation, so once it finds the cat route it adds everything that route brings. The whiskers come along for the ride, even if the neuron doesn’t “want” them. Downstream, the car readers do get a little cat signal through the V neuron, but it barely reaches the output: one cat detector firing does little on its own, since many work together, so the network never needs a negative weight to cancel it. To see the shared pattern, you have to visualize what the neuron’s inputs have in common, not the neuron on its own.
在连续几个月看到语义单一的神经元之后,我开始怀疑,我们是否误解了一些早期颇具代表性的多义性和叠加现象案例。最典型的多义性神经元显然是最值得核查的对象,于是我打开了那张以前看过数百次的猫和汽车图像网格,并做了一件从未做过的事:花几秒钟想想,这些图像可能共同构成什么特征。几乎就在一瞬间,答案就显而易见了:它不是猫和汽车神经元,而是 V 形神经元。After months of seeing clean neurons, I wondered if we’d misinterpreted some early prominent examples of polysemanticity and superposition. The canonical polysemantic neuron seemed like the obvious place to check, so I opened up the cat and car image grid I’d seen hundreds of times before and did something I’d never done: I spent a few seconds wondering what one thing this might be. Almost instantly it was obvious: it’s not a cat and car neuron, it’s a V-shape neuron.
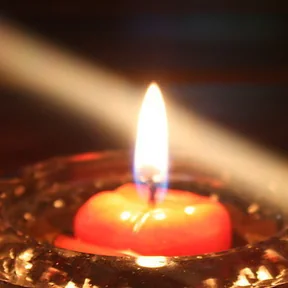
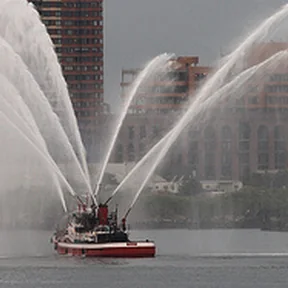
我看了它的电路连接:V形火焰、消防船喷出的V形水柱、V形狐狸脸。我看了它的负极:一个O,圆圆的,而V是尖的。为什么一种随意混搭的猫和汽车,非得和火焰联系得如此紧密?I looked at its circuit connections: V-shaped flames, V-shaped water jets from a fireboat, V-shaped fox faces. I looked at its negative pole: an O, round where the V is pointed. Why would an arbitrary mixture of cats and cars need to connect so strongly to a flame?
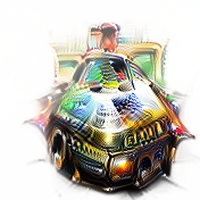
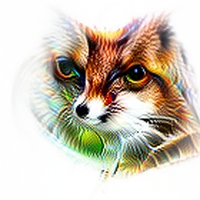 Pointed
 generic
 Round
 generic
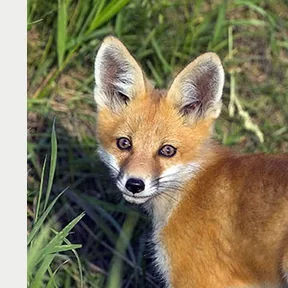
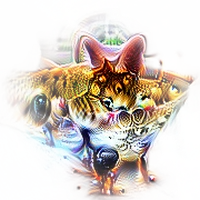
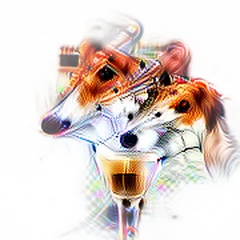
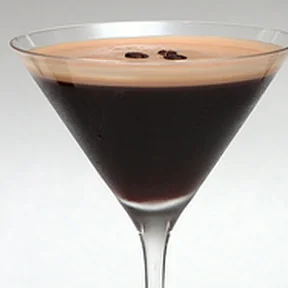
 dog
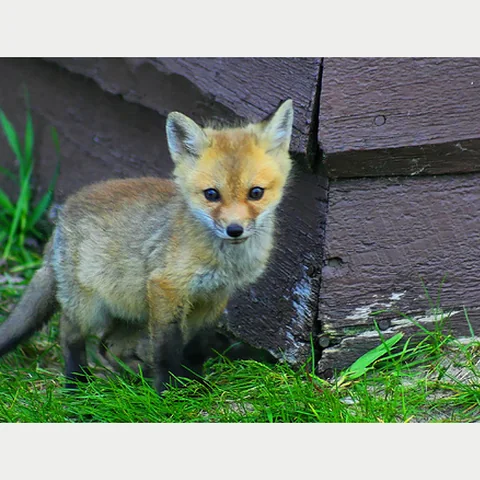 fox
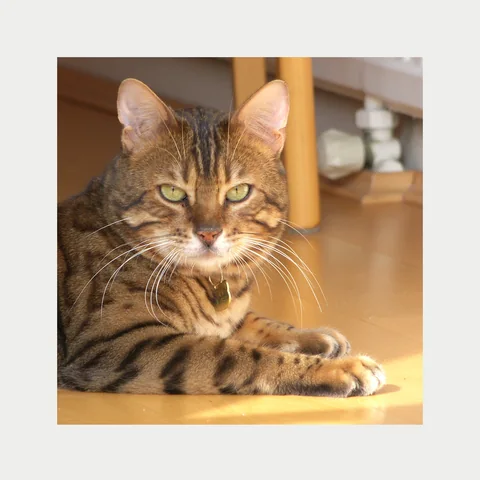 cat
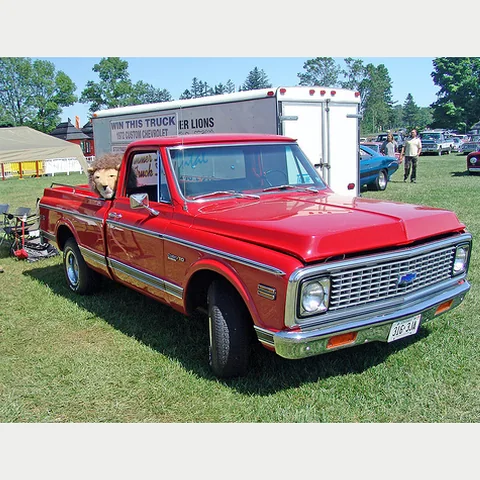 car
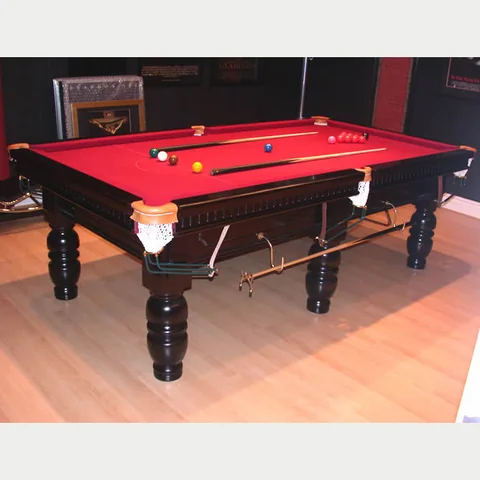 pool table
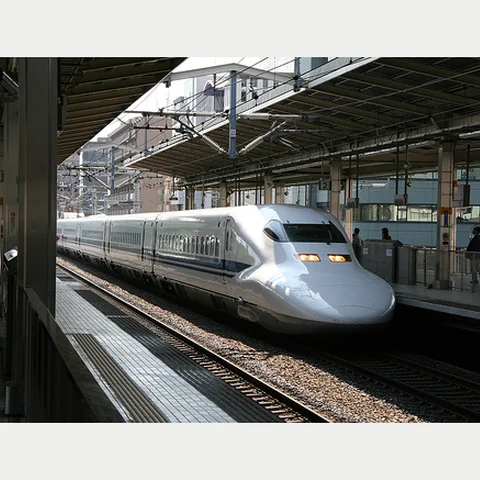 bullet train
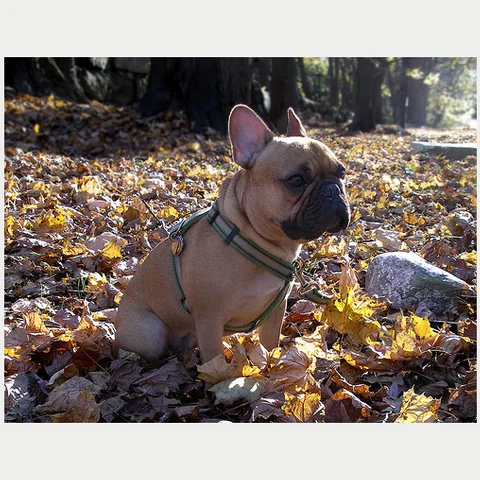 dog
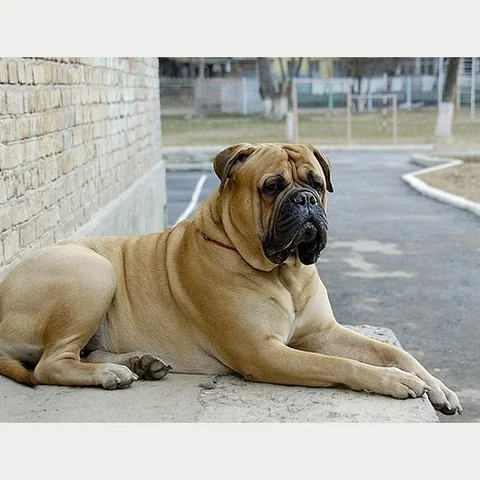 dog
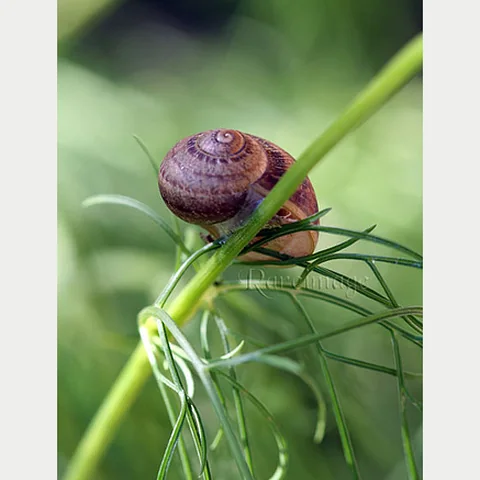 snail
 golf ball
 tennis ball
 clock
然后我研究了那个经典的叠加电路——这是我在 2019 年首次发现的³。我是在构建我的第一个 Circuits 界面时发现它的;那个界面只有特征可视化,以及连接神经元的权重。后来我把它们拿给 Chris Olah 看,并问他,为什么汽车会这样进入这些狗的神经元里。我们得出的结论是,它一定是在进行某种折叠,于是把它称为“叠加”。这为我们所观察到的现象提供了一种直观解释,因此没有促使我们进一步深入研究相关工具;而深入研究本可以揭示特征可视化中的奖励黑客行为以及其他种种问题。把它放在一个高维空间里,感觉是个合理的答案……V 神经元和这个电路,是 Zoom In [4]《Zoom In:电路导论》(Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. 和 Carter, S.,2020 年。Distill。参考文献 ↓)中举出的两个主要例子,用来说明其对神经元的描绘可能“过于乐观”:几乎每个神经元,只要认真研究,最终都能被理解。Then I went to the canonical superposition circuit I first found in 20193I found it while building my first Circuits interface, which only had feature visualization and weights connecting their neurons. Then I took them to Chris Olah and asked why the car would be going into these dogs like this. We came to the conclusion it must be doing a kind of folding, and called it superposition. It was an intuitive explanation for what we saw, so it didn’t prompt diving more into the tools, which would have revealed feature visualization reward hacking and various other things. It being placed into a high-dimensional space felt like a reasonable answer.. The V neuron and this circuit were Zoom In[4]Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓’s two main examples of why its picture of neurons, that nearly every one turns out to be understandable if you look seriously, might be “overly rosy”.
电路似乎显示,一辆汽车驶进了一群毫不相干的狗中,仿佛这些狗是某种高维存储空间,之后需要时便可以从中取回汽车。The circuit appeared to show a car going into a bunch of unrelated dogs, as if the dogs were a kind of high-dimensional storage place where the car could be recovered later as needed.
但这并不是汽车所做的事。汽车和狗之所以被联系在一起,是因为它们共享同一种姿态。InceptionV1 中有一百多个这样的广义姿态神经元,每个神经元都是一个独立而明确的检测器,用来检测汽车、狗和其他物体共享的某种姿态;据我所知,还没有人注意到它们。后续层不断在此基础上构建,一直延伸到模型末端。汽车并没有被存储在某个隐蔽的位置,也没有任何机制直接读取这种组合。恰恰相反,它是在不断分化,形成专门识别汽车的神经元,以及更精细的姿态类别。But that’s not what the car was doing. Cars and dogs were being brought together because of shared pose. InceptionV1 has more than a hundred of these generalized pose neurons, each one its own clean detector of a pose shared across cars, dogs and other objects, and to my knowledge no one had noticed them. Later layers keep building on them, all the way to the end of the model. The car was not being stored in an obscure place, and nothing directly reads out the combination. It’s the opposite: it’s continuing to differentiate into car specialists and finer poses.
部分原因是我们不了解广义姿态神经元,另一部分原因是,我们用来生成图像图标的技术——特征可视化——在更深层中最终会被奖励劫持。我们的目标是找到一张能让神经元激活最大化的图像,但实现方式是梯度下降,而梯度下降会选择最容易的路径;在 InceptionV1 中,这通常意味着狗。InceptionV1 的训练数据里有很多狗,也有很多狗相关的神经元,早期的优化过程会陷入其中,之后就再也走不出来了。只要稍微引导它沿着顶层图像所遵循的自然路径前进,大多数图像都会是汽车,有些则既有狗也有汽车,因为它们共享同一种姿态。Part of the reason was not knowing about generalized pose neurons, and part of the reason is that the technique we use to render icons of images — feature visualization — ends up being reward hacked in deeper layers. The intent is to find an image that maximizes the neuron, but the way that’s done is through gradient descent, and it takes the easiest path, which in InceptionV1 often means dogs. There are lots of dogs in InceptionV1’s training data and a lot of dog neurons, and the early optimization falls into them and never recovers. If you even lightly bias it toward the natural paths the top images take, most of them are cars, and some are both dogs and cars, because of shared pose.
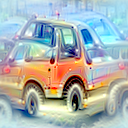
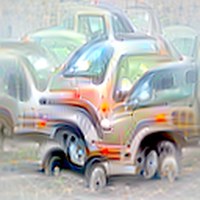
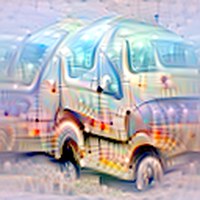
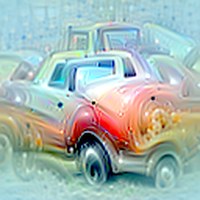
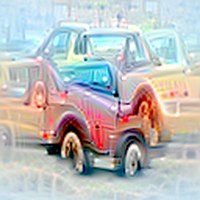
人们很容易低估这一概括,认为狗和汽车之所以被放在一起,只是因为空间不够。也许它“本来想要”分别表示狗姿态和汽车姿态的神经元,而一个空间更大的模型就会把它们分开。诚然,更大的模型往往拥有更多专门化的神经元,但网络扩展时,表现方式可能出人意料。It can be tempting to discount this generalization, under the assumption that the dogs and cars are only together because there’s not enough space. Maybe it “really wanted” separate dog-pose and car-pose neurons, and a bigger model with more space would have separated them. It’s true that bigger models tend to have more narrow neurons, but when networks scale up, they can do it in counterintuitive ways.
看看 DINOv2 [12]《DINOv2:在无监督条件下学习稳健的视觉特征》,Oquab、M.、Darcet、T.、Moutakanni、T. 等,2023 年。arXiv:2304.07193。参考文献 ↓。它的规模是前者的十倍以上,架构也晚了约十年;它拥有更多姿态神经元,但其中许多仍然是泛化的。我观察过的所有视觉模型都是如此,不论规模大小。Looking at DINOv2[12]DINOv2: Learning Robust Visual Features without Supervision
Oquab, M., Darcet, T., Moutakanni, T., et al., 2023. arXiv:2304.07193. References ↓, which is more than ten times the size and about ten years of architecture later, it has more pose neurons, but many of them are still generalized. I’ve seen this in every vision model I’ve looked at, of any size.
无论是人类还是自动化解释者,似乎都强烈倾向于把神经元描述成某一类名词的探测器,比如猫和汽车,而不是某种共同模式的探测器,比如 V 形。有时,神经元确实会对一类名词作出响应。不过依我看,它响应共同模式的情况更常见,因此,与其把神经元理解为名词,不如把它理解为动词。它的作用并不是给输入中的事物命名,而是做出一种下游神经元可以利用的区分:它在正负两端区分两种细微模式(V 形与 O 形),并相应地将激活流导向不同的神经元。Both human and automated interpreters seem strongly biased toward describing neurons as detectors for groups of nouns, like cats and cars, rather than for a shared pattern, like a V. Sometimes a neuron really does respond to a group of nouns. In my experience, though, it’s more often a shared pattern, and the neuron is better understood as a verb than a noun. Its job isn’t to name what’s in the input but to draw a distinction downstream neurons can use: it separates two subtle patterns at its positive and negative poles (a V versus an O) and pushes the flow of activations toward different neurons accordingly.
我常常会这样理清自己对某个神经元的理解:如果完全不能用一组组名词来描述它,我该如何向别人介绍这个神经元?通常,共通模式马上就会显现出来,而且很容易用更多名词组来检验(对于 V:新干线、台球桌)。我怀疑,这是中层神经元被错误归因为多义性的最大来源。我见过的许多把某个神经元称为多义神经元的解释,在我看来,都只是用一串名词描述了同一种模式。I can often unblock my understanding of a neuron by asking: if I couldn’t use groups of nouns at all, how would I describe this neuron to someone else? Usually the shared pattern pops out right away, and it’s easy to test on more groups of nouns (for the V: shinkansens, pool tables). I suspect this is the largest source of misattributed polysemanticity in mid-layer neurons. Many explanations I’ve seen that call a neuron polysemantic look to me like a single pattern described as a list of nouns.
我们应该把一个承载两三种含义的神经元视为一个神经元,只是它有几种归为一组的含义。这种分组大概并没有给网络造成问题:从网络的角度看,这些含义彼此相似,所以才会聚在一起。这使得分组成为了解网络如何思考的一条线索;沿着这条线索追下去,可能会发现我们此前不知道的泛化规律,就像这里的猫和汽车一样。仔细检查后,额外的含义往往也会消失,结果发现它们只是次要含义,而且很少被激活。最后,有些看似存在的含义,其实只是我们的工具不够好;本文就有好几个例子:SwiGLU 的双负值状态、一个未被读取的显著性调节参数(它让残差流难以可视化),以及我们刚刚看到的特征可视化中的奖励黑客行为。保留神经元的原貌,能让这些错误继续显现,从而继续纠正错误。如果我们用优化方法得出一份更整洁的清单,许多这样的线索可能就会丢失。We should treat a neuron that means two or three things as one neuron with a few grouped meanings. The grouping probably wasn’t a problem for the network: the meanings sit together because, from the network’s point of view, they’re similar. That makes the grouping a clue to how the network thinks, and following it can turn up generalizations we didn’t know about, as cats and cars did here. Often the extra meanings also melt away on closer inspection, turning out to be minor and rarely active. Finally, some apparent meanings are just our tools being bad, and this essay has several examples: the double-negative regime of SwiGLU, an unread saliency knob that makes the residual stream hard to visualize, and the reward hacking in feature visualization we just saw. Keeping the original neuron whole keeps these errors visible, so the error correction can continue. If we’d used optimization to get a cleaner list, we might have lost many of these hints.
显微镜错误史A History of Microscope Errors
在我看来,可解释性的故事,很大程度上就是我们逐渐发现,显微镜下的东西比我们想象的要好。只是显微镜没有调校好,而需要调校的地方往往相当微妙。The story of interpretability, as I see it, has largely been one of finding out that what was under the microscope was better than we thought. The microscope just wasn’t tuned right, and what needed tuning was often pretty subtle.
现代神经网络可解释性或许始于特征可视化:它会生成一张合成图像,呈现某个神经元响应最强的内容——那些著名的迷幻图像。有一段时间,这些图像看起来并不怎么样。你完全可以得出这样的结论:神经元确实学到了东西,只不过学得不够清晰。后来人们发现,这种方法缺少对变换的鲁棒性。研究人员补上这一点后,同样的神经元生成的图像就变得清晰锐利了。Modern neural network interpretability arguably started with feature visualization, which renders a synthetic image of what a neuron responds to most: the famous psychedelic pictures. For a while they didn’t look very good. You could reasonably conclude the neurons had learned something, just nothing very clean. It turned out the method was missing transformation robustness. Once researchers added it, the same neurons came out crisp.
但这只能让你深入模型到一定程度。接近末端时,特征可视化又开始失效,原因有两个:我们在汽车电路中看到的奖励劫持,以及不太恰当的正则化。修复它并不需要什么复杂手段。只需对合理的设置做几处细微调整,我们现在就能更深入地观察网络了。同样的神经元,更好的显微镜。But that only gets you so far into the model. Near the end, feature visualization starts to break down again, for two reasons: the reward hacking we saw with the car circuit, and regularizations that weren’t quite right. Fixing it didn’t require anything fancy. A few subtle tweaks to reasonable settings, and now we can see much deeper into the network. Same neurons, better microscope.
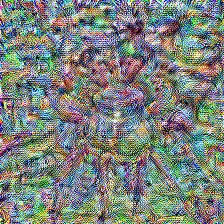
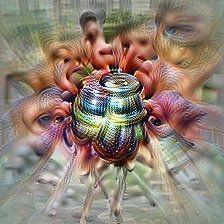
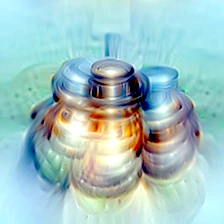
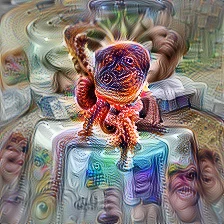
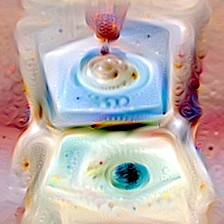
但问题并不全出在显微镜上,模型也需要调整。InceptionV1 是这个领域早期的“模型生物”,但其较深层完全无法解释。一项估计称:“据我所知,InceptionV1 的最后一层基本上没有可解释的神经元。”这和我自己的印象差不多;我大概会说有 5%。它们看起来是这样的。But it wasn’t all the microscope. The model needed to be tuned too. InceptionV1, the early model organism of the field, was totally uninterpretable in the late layers. One estimate said “To the best of my knowledge, there are essentially no interpretable neurons on InceptionV1’s final layer,” which is close to my own recollection, I’d have maybe said 5%. This is what they looked like.
据我所知,主流解释是:需要表示的高层特征太多,相对于神经元和参数的数量而言不堪重负,因此模型开始任意地将本不该放在一起的特征打包,因为它们之间不会发生冲突。早期层之所以是单义的,是因为需要表示的早期层特征没有那么多。The leading explanation as far as I knew was that there were too many high-layer features needed to be represented for the number of neurons and parameters there were, so it started packing ones that don’t belong together arbitrarily, since they don’t collide. The early layers were monosemantic because not as many early layer features needed to be represented.
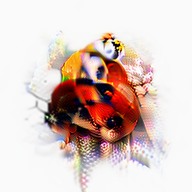
但这并不是正确的解释。下面是一个更现代的卷积网络,参数数量和数据集都相同,但加入了残差连接、层归一化以及其他几项改进。最后一层真漂亮。But this wasn’t the right explanation. Here’s a more modern convolutional network with the same number of parameters and dataset, but with residual connections, LayerNorm, and a couple other improvements. The last layer is beautiful.
Ladybugs · Neuron 127


因此需要满足两件事。首先,神经网络必须能够有效学习,其架构由专注于这一目标、对可解释性毫无兴趣的人设计。残差流就是一个例子:它最初是为了帮助训练更深的神经网络而引入的,而它似乎也有助于让深层在概念上更加清晰,这两者或许有关。其次,我们需要足够强大的工具,才能清楚地观察它们。So two things were required. First, the neural network needed to learn well, using an architecture designed by people fully focused on that goal and with no interest in interpretability. The residual stream is one example: it was introduced to help learn deeper neural networks, and it also seems to help the deeper layers be conceptually clean, which may be related. Second, we needed tools strong enough to see them clearly.
InceptionV1 的最后一层曾是神经网络几乎从根本上无法解释的主要证据之一,因为它们学习到的表示彼此重叠,是互不相关特征的混合。看起来,替换神经元似乎是唯一的选择。用当时的工具,我估计可解释程度约为 5%,其他人则估计接近 0%。借助更好的可解释性工具(固定特征可视化、归因可视化方法等),在同一个网络上,这一比例更接近 50%。以上说的都是 2014 年的模型,而它的检查点和训练细节早已湮没无闻。用更合理的现代正则化方法重新训练同一架构后,这一比例更接近 70%。在同等规模的 ConvNeXt 中,约为 99%。可以在这里探索这些模型。The last layer of InceptionV1 was one of the main pieces of evidence that neural networks were almost fundamentally uninterpretable, since the way they learn overlaps unrelated mixtures. Replacing the neurons seemed like the only option. I put it around 5% with tools of that era, others at ~0%. With better interpretability tools (fixed feature visualization, methods for visualizing attribution etc) it’s more like 50% on the same network. This is all with the 2014 model whose checkpoints and training details were lost to time. Retraining the same architecture with more reasonable modern regularization it’s more like 70%. In the ConvNeXt of the same size, it’s about 99%. They’re explorable here.
递归泛化Recursive Generalization
因此,我们已经证明,最后一层是可以修复的。但在修复之前,它究竟在做什么?即使在架构改进之前,它也不是在随意拼凑各种事物。我们重新训练模型并观察一个神经元形成时,发现它一开始关注的是黄色的花,照片里有时还会出现一只狗。随后,它沿着这些照片的各个特征逐渐扩展:关注其他种类的自然景物、球之类的绿色物体,以及没有花的狗。我观察到的每个神经元都是如此。改进后的架构也呈现出同样的模式,只是这种现象弱得多。So we’ve shown the last layer was fixable. But what was it doing before it was fixed? Even before the architectural improvements, it wasn’t putting things together arbitrarily. When we retrained the model and watched a neuron form, it started on yellow flowers, in photos that sometimes included a dog. Then it grew along each facet of those photos: toward other kinds of nature, toward green objects like balls, and toward dogs without any flowers. This is true of every neuron I looked at. The improved architecture shows the same pattern, but much less of it.
The grey band behind each row is its share of the neuron’s strongest images.
Two neurons over training, from epoch 0.7 to 12, one row per group of images. InceptionV1 neuron 338 starts on rapeseed fields and valleys, with one dog sitting in a rapeseed field. By epoch 1.5 it also responds to tennis balls, green apples and jackfruit, and dogs in grass and yellow flowers; by epoch 3 to shaggy dogs, often with a tennis ball, and broccoli; by epoch 12 it is mostly tennis balls, terriers and broccoli, and the fields have thinned to a sliver. ConvNeXt neuron 399 starts on the same fields and also briefly responds to golf and tennis balls and fruit, then drops them; by epoch 12 it is rapeseed fields, plus one dog lying in yellow flowers. epoch 0.7 1.5 3 6 12 InceptionV1trained from scratch · last layer, neuron 338 rapeseed rapeseed rapeseed rapeseed valley rapeseed rapeseed rapeseed tennis ball tennis ball tennis ball tennis ball tennis ball Granny Smith acorn jackfruit acorn acorn EntleBucher Appenzeller Newfoundland Norwich terrier curly-coated retriever komondor Bouvier des Flandres Dandie Dinmont cairn Bouvier des Flandres broccoli broccoli broccoli cauliflower fields and valleys tennis and golf balls fruit and acorns dogs broccoli and cauliflower ConvNeXtsame data and recipe, with LayerNorm and residuals · last layer, neuron 399 rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed golf ball tennis ball tennis ball soccer ball tennis ball Granny Smith orange jackfruit Kerry blue terrier Appenzeller Appenzeller fields and valleys tennis and golf balls fruit and acorns dogs broccoli and cauliflower Two neurons over training, from epoch 0.7 to 12, one row per group of images. InceptionV1 neuron 338 starts on rapeseed fields and valleys, with one dog sitting in a rapeseed field. By epoch 1.5 it also responds to tennis balls, green apples and jackfruit, and dogs in grass and yellow flowers; by epoch 3 to shaggy dogs, often with a tennis ball, and broccoli; by epoch 12 it is mostly tennis balls, terriers and broccoli, and the fields have thinned to a sliver. ConvNeXt neuron 399 starts on the same fields and also briefly responds to golf and tennis balls and fruit, then drops them; by epoch 12 it is rapeseed fields, plus one dog lying in yellow flowers. epoch 0.7 1.5 3 6 12 InceptionV1 trained from scratch · last layer, neuron 338 rapeseed rapeseed rapeseed rapeseed valley rapeseed rapeseed rapeseed tennis ball tennis ball tennis ball tennis ball tennis ball Granny Smith acorn jackfruit acorn acorn EntleBucher Appenzeller Newfoundland Norwich terrier curly-coated retriever komondor Bouvier des Flandres Dandie Dinmont cairn Bouvier des Flandres broccoli broccoli broccoli cauliflower fields and valleys tennis and golf balls fruit and acorns dogs broccoli and cauliflower ConvNeXt same data and recipe, with LayerNorm and residuals · last layer, neuron 399 rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed rapeseed golf ball tennis ball tennis ball soccer ball tennis ball Granny Smith orange jackfruit Kerry blue terrier Appenzeller Appenzeller fields and valleys tennis and golf balls fruit and acorns dogs broccoli and cauliflower Two neurons over training, from epoch 0.7 to 12, one row per group of images. InceptionV1 neuron 338 starts on rapeseed fields and valleys, with one dog sitting in a rapeseed field. By epoch 1.5 it also responds to tennis balls, green apples and jackfruit, and dogs in grass and yellow flowers; by epoch 3 to shaggy dogs, often with a tennis ball, and broccoli; by epoch 12 it is mostly tennis balls, terriers and broccoli, and the fields have thinned to a sliver. ConvNeXt neuron 399 starts on the same fields and also briefly responds to golf and tennis balls and fruit, then drops them; by epoch 12 it is rapeseed fields, plus one dog lying in yellow flowers. epoch 0.7 1.5 3 12 InceptionV1 trained from scratch last layer, neuron 338 rapeseed rapeseed valley rapeseed tennis ball tennis ball tennis ball tennis ball Granny Smith acorn acorn EntleBucher Appenzeller Norwich terrier Dandie Dinmont cairn broccoli broccoli cauliflower fields andvalleys balls fruit andacorns dogs broccoli ConvNeXt same data and recipe, with LayerNorm and residuals · last layer, neuron 399 rapeseed rapeseed rapeseed rapeseed rapeseed golf ball tennis ball soccer ball Granny Smith orange jackfruit Kerry blue terrier Appenzeller fields andvalleys balls fruit andacorns dogs broccoli我们将此称为递归泛化:一个神经元沿着不止一个维度进行泛化,通常先沿一个维度泛化,然后向外延伸出一些局部上容易理解的分支,但最终却因此无法成为“单义”的。We call this recursive generalization: a neuron generalizing along more than one axis, often first along one axis, then sprouting outwards in ways that are easy to follow locally, but stop it from being “monosemantic” in the end.
例如,某个语言模型神经元会对“iy”产生响应,包括在“Miyazaki”中;接着,它会对“diy”产生响应,然后又对“do it yourself”产生响应,而后者已经完全不含“iy”了。For instance, a language-model neuron responds to “iy,” including in “Miyazaki,” then to “diy,” and then to “do it yourself,” which no longer contains “iy” at all.
图像模型和语言模型中到处都有这样的例子。比如,一个地质学神经元泛化到了 Cesium——一个地质学 JavaScript 库。There are examples all over the place in both image and language models. Like a geology neuron that generalizes into Cesium, a geology JavaScript library.
通常发生了什么一目了然,明显到很难判断这究竟能不能算作普通的泛化。比如,一个“敌人”神经元会对一首关于敌人的俄语诗产生激活。有时情况没那么明确,但仍然说得通。一个斯里尼瓦森神经元也会对 UniProt 蛋白质数据库产生轻微激活。这个项目关联着好几个斯里尼瓦森,但很难确定到底是不是这样。Usually it’s very obvious what happened, to an extent where it’s hard to know whether to just call it normal generalization or not. Like an enemy neuron that fires for a Russian poem about enemies. Sometimes it’s less clear but still plausible. A Srinivasen neuron also lightly fires for the UniProt protein database. The project has several Srinivasen’s associated with it, but it’s hard to know for sure.
- String is a scalar string or 1-element string array, then STRSPLIT returns an array containing72
- determine the average of the values 0 to 9:↵SPAWN, ’test_pipe’, UNIT62
- Set this keyword to make the "Cancel" button the default selection for the dialog. The default selection61
- Stage,↵ ModelExperimentalSceneMeshPrimitive,↵} from "../../../Source/Cesium.js";↵↵describe("Scene59
- of KREEP-rich rock at the base of the crust left by the original crystallization of the54
- Highlands are older than the Northern Lowlands, based on the larger number of impact craters seen covering54
- ers during their final days. The dramatic footage was taken on December 14, 2054
- in the night sky, it's really easy to see the difference between the dark lowland plains called54
- Moon and Mars crust44%comes in throughL31Mars, planetspushesHighlandsneardark side is also home to one of the largest and oldest impact features in the solar system, the South of KREEP-rich rock at the base of the crust left by the original crystallization of the
- Moon missions42%comes in throughL28the Moonpushesmoonfarcrater crust. But with fuel running low, NASA decided to fly them into a mountain near the Moon's the moon to distort images, the LROC (Lunar Reconnaissance Orbiter Camera) is now
- old impacts, Mars6%comes in throughL30life on other planetspushesplainsbasinMars exist.↵“3.4 billion years ago a large meteorite triggered the first wave of the tsunami)↵In other words, the internal pressure buildup due to the massive Hellas impact quite pos
- Cesium and IDL code8%comes in throughL6names like Cesiumpushes.jsobjectssoftware and precipitation rate values from which CesiumJS can then generate↵pointPrimitive objects. Because some of number of colors, once initialized, cannot be changed without first exiting IDL.↵Colormaps define
我们会在语言模型部分讨论这些递归泛化的衍生形式,以及它们有多重要。这里我们只想谈谈这个模式是什么。We’ll talk about these recursively generalized offshoots and how much they matter in the language model section. Here we just want to talk about what the motif is.
我们最早在《多模态神经元》[3]《人工神经网络中的多模态神经元》(Goh, G., Cammarata, N., Voss, C. 等,2021,Distill。参考文献 ↓)中对此有所暗示,称之为“连结特征”。直到我研究递归泛化数月后,回顾这个领域最著名的模型时,才想起这件事。据我所记,包括我在内,没有人提出过这或许是一个普遍解释,例如可以解释 InceptionV1 最后一层的问题所在。由于没有训练检查点,我们无法观察它如何形成,但这个解释基本上是正确的。附录说明了我为什么认为新名称更准确。We first hinted at this in Multimodal Neurons[3]Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, calling them “conjoined features.” I’d forgotten until I went back through the field’s most famous models, months into studying recursive generalization. As far as I can remember, no one, including me, suggested it might be the general explanation, for instance for what was wrong with InceptionV1’s last layer. Without training checkpoints we couldn’t watch it form, but the explanation was basically right. The appendix explains why I think the new name is more accurate.
叠加原理Superposition
递归泛化并不是一个特别大胆的解释;可以说,这不过是普通泛化本就应该带来的结果。但也有人提出了一种大胆得多的解释,认为多义性源于一种新的学习原则。Recursive generalization isn’t a particularly bold explanation, it’s arguably just what we should expect out of ordinary generalization. But there’s also a much bolder explanation that has been proposed for polysemanticity, a new learning principle.
我们到处都能看到的主要学习原则是泛化。泛化会把具有共同模式的事物组合在一起,因为将它们放在同一处很有用,也便于在此基础上继续构建。叠加则会把彼此无关的事物放在一起,因为它们不会相互干扰。两者会给出相反的预测:泛化应该是局部的,而叠加应该是非局部的,因为它会倾向于让差异很大的事物彼此靠近。The main learning principle we see everywhere is generalization. With generalization, things are put together because of a shared pattern that it’s useful to have in one place, so it can be built on. With superposition, unrelated things are placed together because they don’t interfere. These have opposite predictions: generalization should be local, superposition should be non-local, since it would want very different things to be near each other.
泛化会倾向于形成一个“垂耳狗”神经元,可以把它看作许多略有不同、角度和类型各异的垂耳组合在一起。叠加则会倾向于形成一个“垂耳狗 + 拉丁诗歌”神经元。Generalization would want a floppy ear dog neuron, which can be thought of as lots of slightly different floppy ears at different angles and kinds together. Superposition would want a floppy ear dog + Latin poetry neuron.
Unrelated things share a neuron
Similar things share a neuron
这里的定义变得纠缠不清。除了叠加之外,《Zoom In》[4]《Zoom In:电路简介》Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. 和 Carter, S.,2020。Distill。参考文献↓也提出了将特征视为神经网络基本单元的观点。视角不同,“叠加”指的可能是“特征多于维度”——即使是完全单义的网络也符合这一点,因为神经元会组合;也可能指像上文所说的那种学习原则,只不过有时应用于神经元学到的内容,有时应用于特征的去向。4 例如,InceptionV1 的第 4b 层基本上有一些单义性神经元,分别对应车窗、车身和车轮等汽车部件,而下一层会把它们组合成一个汽车神经元 4c:447。从特征的视角来看,说“汽车特征”不仅存在于 4c:447 中,也存在于构成它的那组 4b 神经元中,是合理的。于是,相邻层中有两个汽车特征,其机制几乎完全相同。从“特征多于维度”的视角来看,第一个处于叠加状态,第二个则未必如此。按照非正式文章《分布式表征:组合与叠加》中的说法,第一个是分布式的,但这是通过组合实现的;第二个则完全不是分布式的。这也是我觉得难以借助假设的特征进行思考的原因之一,也是我通常更倾向于具体机制(例如神经元)和具体数据片段的原因之一。The definitions get tangled here. Along with superposition, Zoom In[4]Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓ introduced the idea of features as the fundamental unit of neural networks. Depending on where you look, superposition then means either “more features than dimensions,” which even a fully monosemantic network would satisfy, because its neurons compose, or a learning principle like the one above, applied sometimes to what neurons learn and sometimes to where features go.4For instance, InceptionV1’s layer 4b has basically monosemantic neurons for car parts like windows, car bodies, and wheels, which the next layer assembles into a car neuron, 4c:447. In the feature view, it’s reasonable to say the “car feature” isn’t just in 4c:447, but also in the combination of 4b neurons that builds it. So there are two car features in adjacent layers, sharing almost exactly the same mechanics. In the “more features than dimensions” view, the first is in superposition and the second may not be. In the sense of the informal note Distributed Representations: Composition & Superposition, the first is distributed, but by composition, and the second isn’t distributed at all. This is part of why I find hypothesized features hard to think with, and why I usually prefer specific mechanisms, like neurons, and specific pieces of data.
因此,“叠加”一词本身也处于几种常见用法的叠加状态。我们关注的是应用于神经元等机制的学习原理,因为它是否会形成,几乎决定了可解释性领域的大部分好消息或坏消息。而且这也相当容易检验:递归泛化和叠加给出的预测几乎截然相反,你可以观察一个神经元逐渐形成,看看究竟会发生哪一种情况。So “superposition” is itself in superposition between several common uses. We focus on the learning principle applied to the mechanisms like neurons, because whether it forms holds such a disproportionate share of the good or bad news for interpretability. It’s also fairly easy to test: recursive generalization and superposition predict nearly opposite things, and you can watch a neuron grow and see which one happens.
本文中提到叠加时,指的就是这种版本;至于“特征多于维度”这个问题,我们稍后再讨论——我基本上认为这并不是什么坏消息。When I say superposition in this essay, I’m referring to this version, and we’ll address the question of “more features than dimensions”, which I basically don’t think is bad news, later.
间隙的叠加Superposition of the Gaps
多义性往往与其说是在描述神经元,不如说是在描述观察者。它意味着目前还没有合理的解释。可能有几个原因:Polysemanticity is often more a claim about the observer than the neuron. It says there’s no good explanation yet. There’s a few reasons that could be:
- 糟糕的工具:我们的镜头或显微镜不够好。Bad tools: our lens or microscope isn’t good enough
- 不佳的解释:由这些工具生成的ನ್ನಡBad explanations: created from those tools
- 学习效果不佳:由于架构、训练数据或其他因素,网络未能充分学习。Bad learning: the network learned poorly due to bad architecture, training data, or something else
- 递归式泛化:在泛化过程中,神经元沿着几个相关方向分支扩展。Recursive generalization: while generalizing, the neuron branched off in a few related directions
- 叠加:一种学习原理上的变化,网络会将彼此无关的事物编码到同一组神经元中,因为它们很少发生冲突。Superposition: a change in learning principle where the network packs unrelated things into the same neurons because they rarely collide.
多年来,我一直是坚定的叠加论信徒。我开始研究语言模型神经元,并非因为我对神经元或叠加本身感兴趣,而是因为我想知道智能体是否具备研究品味!我想看看它们在检验各种解释时,会不会提出好问题,于是先从神经元入手,把它们当作基线。我原以为它们会遇到叠加中的特征碎片,那些碎片难以处理。这会为神经元究竟有多清晰提供一个新的基线,之后智能体就能继续使用某种更清晰、习得的基底进行研究。但这种情况始终没有出现,因为神经元一个接一个地涌现出来,最终都指向一个简单的解释;这个解释提出了令人意外的预测,而这些预测后来都得到了验证。For years I was a staunch superposition believer. I started studying language model neurons not out of any interest in neurons or superposition, but because I was interested in whether agents had research taste! I wanted to see if they’d ask good questions as they tested explanations, and started with neurons only as a baseline. I expected them to run into intractable feature fragments in superposition. That would produce a new baseline for how clean neurons really are, then the agents could continue with some cleaner learned basis. But it never came, because the neurons kept coming, resolving to a simple explanation that made surprising predictions that held.
在一个前沿语言模型中,我发现了一个神经元,它大多会在“pr”上激活,但也会在一堆 Base64 URL 字符串以及一些孟加拉语内容上激活。我还以为这终于是个任意混合。可解码这些 URL:都是包含“pr”的词。再翻译这些孟加拉语:也是“pr”。In a frontier language model, I found a neuron that mostly fired on “pr”, but also on a bunch of Base64 URL strings as well as some Bengali. I thought this must finally be an arbitrary mixture. But decode the URLs: “pr” words. Translate the Bengali: “pr”.
在一个稠密的 Qwen 模型中,一位同事发现了一个神经元。标准的 top-k 自动化可解释性工具将它列为“多义逗号神经元”。但仔细观察后发现,它追踪的是科罗拉多州:电话号码、俚语,以及与其他科罗拉多神经元的联系。对它进行引导后,模型就会想去徒步。逗号是它存储迄今为止科罗拉多州上下文摘要的地方。总体而言,注意力似乎会聚集在标点符号上,我们称之为“摘要模式”。一旦了解了这一点,许多类似的神经元就更容易理解了。In a dense Qwen model, a coworker came across a neuron that standard top-k automated interpretability lists as a “polysemantic comma neuron”. But looking more closely, it turned out to track Colorado: phone numbers, slang, and connections to other Colorado neurons. Steering it made the model want to go hiking. The commas were where it stored a running summary of the Colorado context so far. In general attention seems to collect on the punctuation, which we call the summary motif. Once you know it, a lot of similar neurons get easier to understand.
其他时候,我们只是没有足够的数据。起初我们没有纳入长上下文,觉得两段内容就够了。但这无意中让所有长上下文神经元看起来都具有多义性。Other times, we just didn’t have enough data. At first we didn’t include long context, two paragraphs felt like enough. But this accidentally made all the long-context neurons look polysemantic.
在另一个案例中,一个神经元看起来像一团毫无规律的混乱,没有任何东西会强烈激活它。后来发现,它是在成页的健康类 SEO 垃圾内容中寻找特定迹象;而当我们拥有足够广泛的数据集后,这种行为就能理解了。In another case a neuron looked like an arbitrary mess, with nothing firing strongly. It turns out it looked for specific signs within pages of health SEO spam, and once we had a sufficiently broad dataset, it was understandable.
在数百个类似案例中,没有什么动摇我对叠加现象的信念。它只是不断转移。如果强激活经检验毫无异常,叠加现象就会转移到弱激活上,或是神经元的组合上,或是我还没观察过的神经元上。也可能转移到层与层之间。Across hundreds of cases like these, nothing shook my belief in superposition. It just kept moving. If the strong activations came back clean, superposition would move to the weak ones, or to combinations of neurons, or to the neurons I hadn’t looked at yet. Or maybe across layers themselves.
但最终我开始纳闷到底是怎么回事。除非这是一起极其严重、持续时间很长的选择偏差案例,否则情况就与早期的模式生物不符。于是我回过头去重新审视,原先的证据站不住脚了,这便促成了这篇文章。But eventually I wondered what was going on. Unless this was some dramatic extended case of selection bias, something wasn’t matching the early model organisms. So I went back, the original evidence fell, and that led to this essay.
我现在认为,我把叠加当成了零假设,而它本该是最后才考虑的假设,因为它最为激进,也最难验证。它看起来就像是一些说不通的东西。但糟糕的工具也会呈现出这种样子(特征可视化中的奖励劫持),你尚未追溯到底的递归泛化也是如此(“iy”神经元),糟糕的架构也是如此(InceptionV1 的 5b),尚未理解的泛化现象也是如此(猫和汽车)。I now think I was making superposition the null hypothesis when it should have been the last hypothesis, since it’s the most radical and the least testable. It just looks like things that don’t make sense. But that’s also what bad tools look like (feature visualization reward hacking), or recursive generalization you haven’t followed yet (“iy” neuron), or a bad architecture (5b of InceptionV1), or generalization you haven’t understood yet (cat and car).
我认为其中一部分原因是,叠加听起来就是很合理。Anthropic 的《Softmax 线性单元》[20] Softmax Linear Units Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. 参考文献 ↓ 论文在 2022 年也这么说:“在机制可解释性社区里,叠加常常被视为默认假设,只是因为它在直觉上似乎比其他解释更有说服力,但几乎没有证据。”⁵ 下一句中,论文称自身的结果为叠加提供了中等程度的证据。用论文自己的话说,这些证据是间接的:SoLU 会抑制分散在许多神经元中的激活;额外加入一个 LayerNorm 后,模型性能得以恢复;而经过 LayerNorm 后,某个神经元的弱激活看起来与其主要功能的关联有所减弱。论文将其解读为:特征借由微弱激活偷偷传了出来。我们则将其视为一种证据,说明在一种旨在抑制分布式表征的架构中,分布式表征依然存在;而不是说神经元把互不相关的内容打包在一起——我们关心的是后者这种意义上的叠加。即使使用当今的工具,要从弱激活中区分两者也很困难,因为随着激活减弱,意义会同时向各个方向发生变化;而在 2022 年,对我们所有人来说,这件事就更难了。论文还指出,其中关于叠加的讨论已被《叠加的玩具模型》取代,我们会在附录中讨论这篇文章。我们提起它,并不是在批评这两篇论文,而是因为这是我们所知唯一一处有人直言现实世界中的证据少之又少;我们认为,人们至今仍常常以为证据比实际多得多。据我所知,自我最初发现的那个叠加电路(那其实是个错误)之后,还没有人在真实网络中发现过叠加电路。我原本以为会在真实模型中看到类似现象,但我并没有;我认为,声称发现叠加的门槛应该很高,因为这是一个极其激进的解释,而且会是个重大新闻——对我们研究神经网络的方式而言,更是个糟糕透顶的消息。I think part of what was going on was that superposition just felt right. Anthropic’s Softmax Linear Units[20]Softmax Linear Units
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ paper said as much in 2022: “In the mechanistic interpretability community, superposition is often treated as the default hypothesis simply because it seems intuitively more compelling than other explanations, but there is little evidence.”5In the next sentence, the paper says its own results are moderate evidence for superposition. That evidence is circumstantial, in the paper’s own word: SoLU suppresses activations spread across many neurons, an extra LayerNorm restores performance, and after the LayerNorm a neuron’s weak activations looked less related to its main job, which the paper reads as features being smuggled through small activations. We read it as evidence about distributed representation in an architecture built to suppress it, rather than about neurons packing unrelated things together, which is the sense we care about. Telling the two apart in weak activations is hard even with today’s tools, since meaning shifts in every direction at once as activations weaken, and it was harder still in 2022, for all of us. The paper also notes that its discussion of superposition has been superseded by Toy Models of Superposition, which we address in the appendix. We bring it up not as a criticism of either paper, but because it’s the only place we know of where someone said plainly how little real-world evidence there was, and we think people still often assume there’s more than there is. To my knowledge, no one has found a superposition circuit in a real network since my original one, which was an error. I don’t see anything like it in real models, despite expecting to, and I think the bar for claiming it should be high, since it’s such a radical explanation and would be big news, terrible news, for how we should study neural networks.
当然,这样做有可能造成相反的错误:试图解释那些本不存在的规律——假定每个神经元都必须有个合理的说法。有两点让这种担忧不那么严重。第一,其他每种原因都可以检验。更好的工具要么能解析这个神经元,要么不能;用更好的架构重新训练,可以看出问题是否出在学习上;而递归泛化的增长过程也可以通过小步观察。超位叠加唯一的症状,就是某些东西说不通。第二,真实的解释往往范围狭窄,也很容易检验。一旦你怀疑某个神经元是“科罗拉多州神经元”,就引导它,看看它会说什么。如果某个神经元会因某种狭窄的电视套路而激活,那么可能符合这种解释的事物范围很小;而“某些说不通的东西”则涵盖了除此之外的一切。Of course, this risks the opposite error, an explanation of the gaps: assuming every neuron must have a sensible story. Two things make it less worrying. First, each of the other causes can be tested. A better tool either resolves the neuron or it doesn’t; retraining with a better architecture shows whether learning was the problem; and recursive generalization can be watched as it grows, in small steps. Superposition’s only symptom is that something doesn’t make sense. Second, real explanations tend to be narrow and easily testable. Once you suspect a neuron is a Colorado neuron, steer it and see what it says. If a neuron fires for some narrow TV trope, the set of things that could count as that explanation is tiny, while “something that doesn’t make sense” covers everything outside it.
此外,我们不必硬编一个自己并不清楚的解释。如果一个神经元可能会做几件互不相关的事,而你也不确定,那就坦率地说出来。我认为,递归泛化应该是优先怀疑的可能性之一,而且如果你有训练检查点,也很容易验证。我现在觉得,叠加应该排在可能性列表的很后面。Also, we don’t have to force an explanation we don’t have. If a neuron might do a couple unrelated things and you’re not sure, it’s fine to say so. I think recursive generalization should be high on the list of things to suspect, and it’s easy to check if you have training checkpoints. I now think superposition should be far down the list.
探索图像模型Exploring Image Models
小型图像模型或许看起来已经过时,但我认为它们对这个问题至关重要,因为我们能非常清楚地观察它们。最初的许多担忧也源于这些模型:在那里,我们看到的似乎是高分辨率的混乱,而不是低分辨率的模糊性。语言模型规模庞大,我们没有特征可视化这类能让研究更轻松的工具;注意力机制把不同类型的机制混杂在一起,而且其中许多模式都出人意料。正如我上文所展示的,即使是视觉模式也可能违背直觉,而语言模型的情况更糟。这些缺陷中的每一项,都可能让一个单义神经元看起来像是多义的。如果你看着一张模糊的图片,试图判断它是一只狗还是一只猫,模糊会让判断更困难,却不会偏向任何一种答案。如果你看着一张模糊的图片,试图判断是图片本身模糊,还是只是自己看不清,那么视力上的每一处缺陷都会被算作图片的模糊。如果我们想研究神经元如何随规模、压缩压力、激活强度和深度而变化,最好从我们能够看清楚的地方开始。Small image models may seem obsolete, but I think they matter a lot to this question because we can see them so clearly. They're also where much of the original worry came from: there we saw what looked like high-resolution chaos, not low-resolution ambiguity. Language models are massive, we don't have tools like feature visualization which make our life easier, attention mixes different kinds of mechanisms together, and many of their motifs are surprising. As I showed above, even vision motifs can be counter-intuitive, and language is worse. Each one of these deficiencies can make a monosemantic neuron look polysemantic. If you're looking at a blurry image trying to figure out if it's a dog or a cat, the blur makes it harder, but it doesn't favor either answer. If you're looking at a blurry image and trying to decide if the image itself is blurry or if you're just looking badly, every flaw in your eyesight gets counted as blur in the image. If we want to study how neurons change with scale, compression pressure, activation strength, and depth, it's better to start where we can see clearly.
我训练了三个规模相差约 300 倍的 ConvNeXt 模型:一个小型模型,拥有 92k 个参数;一个中型模型,拥有 7.06M 个参数(与 InceptionV1 大小相同);以及一个大型模型,拥有 28.6M 个参数。我们将研究这些模型以及 InceptionV1,尝试理解神经元在不同情境下的作用,并寻找可能形成打包的地方。I trained three ConvNeXt models spanning roughly 300× in size: a small one with 92k parameters, a medium one with 7.06M (the same size as InceptionV1), and a large one with 28.6M. We’ll look at those, and also InceptionV1, to try to understand what neurons do in different situations, and try to find places packing may form.
我如何看待神经元How I Think About Neurons
我过去把神经元想象成人形名词:一个是汽车,另一个是曲线。现在我更倾向于把它们看作控制流。神经元的关键,与其说是它看到了什么,不如说是它如何处理流入的信息;它的作用往往是控制网络某个区域的通行。从这个角度看,单义性几乎问错了问题。更好的问题是:一个神经元放行什么,又拦住什么。I used to think of neurons as human-shaped nouns: one is a car, another is a curve. Now I think of them more as control flow. A neuron is less about what it sees than about what it does to the flow coming in, and often its job is to gate a region of the network. Seen this way, monosemanticity is almost the wrong question. A better one is what a neuron lets through and what it keeps out.
像素输入后,网络便开始对事物进行分组和区分。汽车和狗可能会因为姿势相似而被归为一组。再往后,则有专门的汽车检测器——用于检测出租车、救护车之类的车辆——它们不希望把狗也算进去。因此,它们前面的一个神经元就像一道闸门:遇到汽车时产生正向响应,遇到狗时产生负向响应,而它的负向一侧会把狗排除在外。狗则会进入自己的区域,在那里无需考虑汽车。后续神经元在此基础上进一步细化,变得更加专门:救护车神经元的负极可能对应出租车,而出租车神经元的负极则对应救护车。在更大的模型中,这些区分还可以更加细致,把出租车的不同视角彼此区分开来。较小的模型可能会止步于更粗略的区分,形成一个更接近通用“汽车”神经元的结构。Pixels come in, and the network begins grouping and distinguishing things. Cars and dogs might be grouped together because they share a pose. Further along there are specific car detectors – for taxis, ambulances and the like – and they don’t want dogs. So a neuron in front of them acts as a gate: it responds positively to cars and negatively to dogs, and its negative side keeps the dogs out. The dogs go on to their own area, which doesn’t have to worry about cars. Later neurons build on this, specializing further: an ambulance neuron might have a taxi on its negative pole, and a taxi an ambulance. In a larger model, these distinctions can become finer still, separating one view of a taxi from another. Smaller models may stop at coarser distinctions, with something closer to a general “car” neuron.
这里有一辆真正的跑车,我们追踪它在大型模型最后五个块中的分类过程。进行到一半时,它和桌子、橱柜等其他矩形物体被归为一组,与蛇和狗区分开来。到了最后一个块,分类则变成敞篷车与旅行车之分。Here’s a real sports car, followed through the last five blocks of our large model. Partway through, it’s grouped with other rectangular shapes, like tables and cabinets, against snakes and dogs. By the last block, the split is convertibles against station wagons.
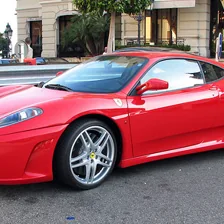
sports car
cars and limousines
vs. buses and trams
tables and cabinets
vs. snakes and dogs
convertibles, sports cars
vs. minibuses
convertibles
vs. vans and wagons
convertibles
vs. station wagons
要理解神经元,负侧几乎和正侧同样重要,即使在负侧被截断的 ReLU 网络中也是如此。神经元由投票构成:每个输入权重都在为正侧或负侧投票,而这些票会在经过非线性变换之前累加起来。负侧本身永远不会获得梯度,但只要神经元处于激活状态,各个投票就会获得梯度,因此负侧也会受到学习的塑造。负侧的含义取决于上下文:当一条跑车路径上的神经元把跑车与蛇和狗区分开时,它并不是在说汽车和狗互为反义,而只是在排除那些先前被有用地归为一组的事物。负侧告诉我们,电路中的这一环节究竟在区分什么;这也让我们能快速检验某种归类是否真实:V 神经元的负侧是 O。The negative side of neurons matters almost as much as positives for understanding them, even in ReLU networks where the negative side is cut off. A neuron is built from votes: each input weight votes for its positive side or its negative side, and the votes add up before the nonlinearity. The negative side never gets gradient on its own, but the individual votes do whenever the neuron is on, so it’s shaped by learning too. The negative side’s meaning depends on context: when a neuron in the sports car’s path separates it from snakes and dogs, it isn’t calling cars and dogs opposites, just gating out things that were usefully grouped earlier. The negative side tells us what distinction matters at this point in the circuit, which also makes it a quick check on whether a grouping is real: the V neuron’s negative side is an O.
如果我们观察最后一层,就会看到高层模式,以及它们与哪些事物相区别:出租车与救护车、西兰花与花椰菜、琵鹭与火烈鸟。If we look at the last layer, we see high-level patterns and what they’re being distinguished from: taxis from ambulances, broccoli from cauliflower, and spoonbills from flamingos.
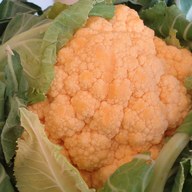
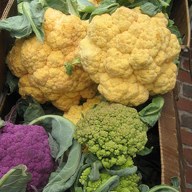
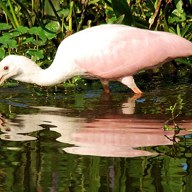
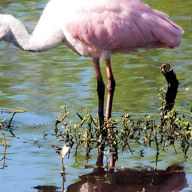
The two strongest images at each pole. The sign is the neuron’s own response, not its effect downstream. Neurons in the last block (stage3.block2): taxis 230, broccoli 829, spoonbills 1440, toucans 2021, lighthouses 1956, pretzels 1068, wolves 401, house cats 1637, mittens 63.
观察最小的模型时,我们会发现它的神经元划分得更粗。它的最后一层把汽车、火车和马车归到同一个神经元中,而船、飞机和一种水上牛车(我之前都不知道竟然还有这种东西)则位于这个神经元的负向一侧。它仍然在进行区分,只是粒度更粗,而且很早就结束了。When we look at our smallest model, we see the neurons get coarser. Its last layer ends at cars, trains, and carts in one neuron, with boats, planes, and a water-based ox-cart, (which I didn’t know even existed), on its negative side. It’s still differentiating, but more coarsely, and it ends early.
神经元在压力下的反应What Neurons Do Under Pressure
大多数视觉模型的早期层都是单义的。据我理解,标准解释是:需要表示的早期视觉特征并没有那么多。乍看之下,这有点奇怪:从 AlexNet、ResNet、InceptionV1 到 CLIP,每个模型的早期特征与早期神经元的比例都恰到好处,尽管它们的数据集规模与参数规模之比差异很大。Early layers in most vision models are monosemantic. As I understood it, the standard explanation is because there’s not that many early vision features that need to be represented. On its surface, it’s a bit strange that every model, from AlexNet, to ResNets, to InceptionV1, to CLIP all have the right ratio of early features to early neurons, since they have such different ratios of dataset to parameter size.
我们可以聚焦于 InceptionV1 的 3b 层,其中包含曲线神经元和高低频神经元;在我看来,它们是最基础的神经元之一。这个模型没有残差流,因此无法“绕过”神经元。于是,我们可以把数量从 480 减少到 10,然后重新训练,来测试空间不足时神经元会发生什么。One layer we can focus on is 3b of InceptionV1, the layer with Curve Neurons and High-Low Frequency neurons, which are among the most fundamental in my opinion. This model has no residual stream, so there’s no way to “flow around” the neurons. So we can test what happens to neurons when there’s not enough space by reducing the amount from 480 to 10 and retraining.
如果它切换到了叠加态,我们应该能看到彼此重叠的混合图案,比如一条曲线、一条橙色螺旋、蜘蛛网,以及其他几个纹理检测器。我们已经把它压缩了48倍,所以效果应该会很明显!If it switched to superposition, we should see overlapping mixtures on top of each other, like a curve plus an orange spiral plus spider webs and several other texture detectors. We’ve crushed it 48x so it should be dramatic!
但我们看到的并非如此。这些神经元仍然可解释且具有泛化性,只是粒度更粗:一个“曲线与环圈”神经元,而不是十个曲线检测器;两个圆形神经元,而不是几种不同类型的圆形神经元,等等。But that’s not what we see. The neurons stay interpretable and generalized, but coarser: one “curves & loops” neuron instead of ten curve detectors, two circle neurons instead of several circle types, and so on.
Optimized image, then the 10 strongest image responses from the 50,000-image scan. Select a crop for its activation and rank.
InceptionV1 was trained from scratch with mixed3b reduced from 480 to 10 spatial channels, with no bypass around the layer. The resulting model reached 58.35% top-1 and 81.14% top-5 accuracy on 50,000 held-out ImageNet images.
Examples rank image maxima over 50,000 training images. The grid shows each neuron’s five strongest; each range here shows ten of the saved examples. Names are provisional visual descriptions. Path-guided visualizations use the strongest 60 examples.
我们可以显式地测试这些曲线,看看它们发生了什么。如果它们被编码在某种高维神经元组合中,我们应该能够将它们提取出来。因此,我们可以在这个被压缩的层上训练一个 SAE,并将结果与原始曲线进行比较。我们看不到任何类似于清晰的曲线神经元的东西!We can test curves explicitly to see what happened to them. If they were placed in some high dimensional combination of neurons, we should be able to extract them. So we can train an SAE on this crushed layer and compare them to the originals. We don’t see anything like clean curve neurons!
Original 3b · 480 neurons
Ten curve detectors
Retrained with 3b at 10 neurons
The whole squeezed layer
An SAE on the squeezed layer
Closest match to each detector
Curves & loops
The squeezed model was trained from scratch with mixed3b cut from 480 to 10 channels and no bypass, and reached 58.35% top‑1 and 81.14% top‑5 on the 50,000 ImageNet validation images. The autoencoder is a TopK SAE with 640 features, 2 active at each position (the essay’s SAE recipe plus the usual auxiliary loss that keeps features from dying), trained on the squeezed layer at 25.6 million positions from 200,000 ImageNet training images. It explains 82% of the variance of held-out positions, and with it spliced in, top‑1 on 10,000 validation images falls from 58.8% to 43.0%.
Each detector and its closest SAE feature
| Detector | Prefers | Width | SAE feature | Prefers | Width | Shape match | Photo match |
|---|---|---|---|---|---|---|---|
| 3b:385 | 16° | 40° | 79 | 38° | 174° | 0.52 | 0.09 |
| 3b:343 | 84° | 40° | 64 | 84° | 64° | 0.72 | 0.14 |
| 3b:342 | 116° | 56° | 510 | 86° | 80° | 0.61 | 0.19 |
| 3b:388 | 166° | 40° | 174 | 192° | 44° | 0.38 | 0.11 |
| 3b:324 | 184° | 24° | 174 | 192° | 44° | 0.79 | 0.26 |
| 3b:340 | 214° | 42° | 435 | 232° | 146° | 0.48 | 0.08 |
| 3b:330 | 244° | 52° | 89 | 232° | 88° | 0.52 | 0.11 |
| 3b:349 | 272° | 34° | 277 | 278° | 64° | 0.60 | 0.18 |
| 3b:379 | 328° | 44° | 544 | 32° | 138° | 0.56 | 0.18 |
| 3b:406 | 356° | 26° | 354 | 334° | 94° | 0.42 | 0.17 |
Tuning is the response at the centre of the image to a thin dark arc drawn at 180 angles and two curvatures, as in the Missing Curves appendix. Each detector’s match is the SAE feature, among those that respond to drawn curves most strongly, whose tuning curve correlates best with the detector’s (shape match). Width is the span of angles above half the peak; the tuning curves in the rings are each scaled to their own peak. Photo match is the correlation, over every position of 10,000 held-out photos, between the feature and the original detector at the same place.
The originals are 24–56° wide and silent at the opposite angle; the matches are 44–174° wide and keep responding at the opposite angle, and 3b:388 and 3b:324 share one feature. None of the 91 features that respond most to drawn curves is silent at the opposite angle. Dropping that filter finds features with closer, narrower shapes (0.63–0.98), but they respond to drawn curves at only 9–42% of their usual strong activation (the originals at 72–183%) and track the detectors in photos even less (0.02–0.12). The essay’s SAE of the original layer matches the same detectors with shape correlations of 0.96–1.00. On the squeezed layer, even the best nonlinear readout of the ten neurons at one position tracks each detector with a correlation of only 0.29–0.48. Other autoencoders tell the same story (1 to 4 active features, 160 or 640 features, a second seed, or no auxiliary loss): median shape match 0.47–0.63, photo match at most 0.27. With 3 or 4 active features the preferred angles line up better, but the curves stay broad and two‑sided.
Control
Optimized images use the essay’s path‑anchored recipe (the one behind the original curve images) for the squeezed neurons, and its SAE recipe (the one behind Missing Curves) for the SAE features. The path weight is scaled to each unit’s activation range, since the squeezed layer’s activations are hundreds of times smaller than the original’s. The same SAE recipe, run on the essay’s SAE of the original layer, draws clean curves:
The squeezed neurons’ photos
Squeezed‑neuron names are provisional visual descriptions. Photos rank each neuron’s image maxima over 50,000 training images.
我觉得这是个很好的测试,可以看看我们能否让一个我很熟悉的单义层变成叠加态。不过从某些方面来说,这并不理想,因为人们大多怀疑叠加现象发生在最后几层。所以我们可以拿一个中等规模的 ConvNext,把最后一层压扁,阻止它绕过残差流进行路由,然后看看它会学到什么。我们看到它也出现了同样的模式:表征变得更加宽泛。I think this is a good test of whether we can turn a monosemantic layer I know well superposed. But in some ways it’s not ideal, since people mostly suspected superposition in the last layers. So we can take our medium size ConvNext, crush the last layer, stop it from routing around the residual stream, and see what it learns. We see the same pattern of it broadening.
小型 ConvNext 的情况也是如此,从某些方面来说,这是一项非常相似的测试。This is also what we see with the small ConvNext, which in some ways is a very similar test.
03Transit & small mammals
晚期电路Late Circuits
我们也可以检查靠后层中的电路,以排除最后一层有什么特殊之处的可能性。我们发现,整个网络始终都以这种方式组织。We can also look at circuits in the late layers, to rule out any chance that the last layer is somehow special. We see that it’s organized the whole way through.
Monastery
词典学到了什么What Dictionaries Learn
如果神经元的组合藏着某些信息,那么字典(例如 SAE)就应该能找到神经元所缺少的基本构件。因此,我在这些层上训练了好几个字典,然后自己和借助智能体一起寻找。我什么也没找到。If combinations of neurons were hiding things, a dictionary (eg an SAE) should find building blocks the neurons lack. So I trained several on these layers and went looking, myself and with agents. I didn’t find any.
总体而言,两者看起来都符合其机制本质:神经元像积木,SAE 单元则像是按上下文分组的积木。蜘蛛的例子最清楚:SAE 单元对应不同场景中的蜘蛛;神经元对应腿部图案和蛛网。它们彼此之间并没有太大分歧。Mostly, the two looked like what they mechanistically are: the neurons like building blocks, the SAE units like those blocks grouped by context. It was clearest with spiders. The SAE units were spiders in different settings; the neurons were leg patterns and webs. They didn’t disagree much.
SAE 确实有助于回答“这张图里有什么?”在最小的模型中,它们帮助最大,因为那里的神经元表征比较粗糙。中等规模时,我稍微更偏好 SAE;规模较大时,我想我更偏好神经元。但相比理解某一张图,我更在意理解整个网络,而我从未见过 SAE 抓住了什么根本性的东西,而神经元却没有。如果某个特定规模的模型无法理解棒球运动员,它的 SAE 也一样做不到。等模型终于理解了棒球运动员时,体现这一理解的是一个神经元。SAEs did help with “what’s in this image?” They helped most in the smallest model, whose neurons are coarse. At medium size I slightly preferred them; at large, I think I prefer the neurons. But I care more about understanding the network than about any one image, and I never saw the SAE grasp something fundamental the neurons didn’t. If a model at a particular size failed to understand baseball players, so did its SAE. When the model finally understood a baseball player, it was on a neuron.
SAE 找到了哪些并没有明确神经元对应物的东西?在最后一层中,它 88% 的活动都是单个神经元的近似副本,其余部分则很微弱:移除所有与任何神经元都不匹配的字典方向,准确率仍然不变;而它导致的少数答案变化,本来就几乎势均力敌。此外,如果从某个随机旋转开始,在一层的各种旋转中搜索能让少数几个单元承载最多活动的那一种,那么在每个区块中,最终都会回到神经元上。在少数几个强到值得观察的特征中,SAE 增添的是由已有神经元构成的松散组合,比如水面上的动物,或苍白、块状的食物。我们在那里发现的东西,没有一样看起来像是某种全新的基本构件。What did the SAE find that didn’t already have a clear neuron counterpart? On the last layer, 88% of its activity is near-copies of single neurons, and the rest is faint: removing every dictionary direction that matches no neuron leaves accuracy unchanged, and the few answers it flips were already near-ties. Additionally, if you search the rotations of a layer for the one where a handful of units carry the most activity, starting from a random one, you land back on the neurons, in every block. Among the few features strong enough to look at, what the SAE added was loose groupings built from existing neurons, like animals at the water’s surface or pale, lumpy food. Nothing we found there looked like a fundamentally new building block.
 733 0.19
 170 0.17
 920 0.17
 482 0.15…
罕见事物与记忆Rare Things and Memorization
关于隐藏特征的担忧,很大程度上源于那些罕见事物。它们很少与其他东西发生重叠,而且似乎不值得拥有自己的神经元。因此,我们用能想到的各种方法研究了罕见事物。罕见类别通常更加集中:ImageNet 需要大量狗的模式,但三角龙只需要一个神经元。我在最后一个阶段移除较弱的激活后,没有任何类别特别突出。我们追踪的对抗样本走的都是正常的语义电路路径。A lot of the worry about hidden features comes from rare things. They seldom collide with anything, and they may not seem worth a neuron of their own. So we looked at rare things every way we could think of. Rare classes are often more consolidated: you need a lot of dog patterns for ImageNet, but only one Triceratops neuron. When I removed weak activations in the last stage, no class stood out. The adversarial examples we traced used normal semantic circuit routes.
我查看了那些在最后几层中的表征与其他任何图像都相距最远的图像。结果发现,它们都是些有趣又古怪的图像,模型会用普通神经元把它们误读成别的东西:蜂鸟被看成冰淇淋,巨大香蕉被看成保险库,一个坐在翻倒的独轮手推车里的男人被看成割草机。我还训练了一个 ImageNet 模型,让它把随机噪声映射到随机标签,而即便如此,这个过程也在一定程度上带有语义性:模型部分依赖了羊毛纹理和远处树木的纹理;这些都是高频特征,有点像高频噪声。我没有对模型进行全面审计,但觉得它居然会用到这些特征,这一点很有意思。在语言和视觉的所有实验中,记忆往往倾向于尽可能靠近输出端,因为它只需要查出答案即可,而大部分工作都是由后面的层完成的。I looked at the images whose representations in the last layers are furthest from any other image. They end up being entertaining, weird images that the model misreads with ordinary neurons: a hummingbird seen as ice cream, a giant banana seen as a vault, and a guy in a fallen wheelbarrow seen as a lawn mower. I also trained an ImageNet model to map random noise to random labels, and even that was partly semantic: it partially leaned on wool textures and the texture of distant trees, which are high-frequency, a bit like high frequency noise. I didn’t fully audit the model, but thought it was interesting that it used them at all. Across all experiments in language and vision, memorization tends to want to sit as close to the output as possible, since all it has to do is look the answer up, and the late layers did most of the work.
我们也可以自己构造一条罕见路径:教会我们的 706 万参数模型一些荒谬的东西,比如把雨伞的照片认作蜜蜂。你或许会以为,这种记忆不依赖其他任何东西:某个隐藏特征只对这组特定像素作出响应,并给出“蜜蜂”的判断;由于不需要网络的其他部分,它便与其余部分隔绝开来。这可就糟糕了,但实际情况完全不是这样。经过九个训练步骤,模型最可能的猜测从雨伞变成了五朔节花柱,最后变成蜜蜂。代表雨伞的神经元逐渐减弱,而已有的蜜蜂神经元开始激活,这几乎全都发生在最后三个块中:只要把这几个块替换到原始模型中,它就会说“蜜蜂”。We can also make a rare route ourselves, by teaching our 7.06M-parameter model something nonsensical: that a photo of an umbrella is a bee. You could imagine this memorization not relying on anything else: a hidden feature that latches onto this exact set of pixels and says “bee,” cut off from the rest of the network because it doesn’t need it. That would be pretty bad news, but it’s not at all what happens. In nine training steps, the top guess went from umbrella to maypole to bee. The umbrella neurons faded and existing bee neurons came on, nearly all of it in the last three blocks: swap just those into the original model, and it says “bee.”
An umbrella switches to the bee route
this photograph, original modelafter learning “bee”each circuit on natural images
这相当于学习某种隐藏的伞状特征,它独立于其他任何常规伞状特征或蜜蜂路径。虽然这并非不可能,但我认为,相比于把已经在激活且通向输出的相关部分组合起来(从而赋予系统可塑性和梯度),学习这种特征要慢一些。它也更脆弱,而且我们在任何地方都没有看到这种情况。This is in comparison to learning some sort of hidden umbrella feature separate from any other normal umbrella or bee route. While this is possible, I think it’s slower to learn than assembling related parts that are already activating and have routes to the output, giving it plasticity and gradient. It’s also more fragile, and isn’t what we see anywhere.
A stray superposed feature
What happens
弱激活重要吗?Do Weak Activations Matter?
当人们问弱激活是否重要时,我认为其中混杂着几个不同的问题,而它们的答案也各不相同。When people ask whether weak activations matter, I think there are several questions mixed together, and they have different answers.
它们是泛化还是叠加?Are they generalization or superposition?
不出所料,我认为这是泛化能力的问题。想象一下,你是一个被紧密打包、与其他特征无关的特征,正努力避免与主神经元中的内容发生冲突。弱激活要密集得多,因此你会与数量级更多的东西发生冲突,收益却微乎其微。Unsurprisingly, I think it’s generalization. Imagine you’re a packed, unrelated feature trying not to collide with what’s in a main neuron. Weak activations are vastly denser, so you’d be colliding with orders of magnitude more things, for little upside.
但也许你隐藏在许多神经元同时产生的微弱激活中。我们看到,几乎可以毫无代价地消融网络中几乎所有微弱激活。移除后代价最高的那些部分,有些反而最容易理解。在语言模型中,它们包括最后一层;这一层主要用于抑制单个词元,这对应于我们所说的“说出来还是只在心里想”模式。在视觉模型中,它们则是早期层,这些层起到类似旋钮的作用:稍亮和中等亮度之间的差异很重要,但对于像帝企鹅这样的后续检测器来说,证据较弱和极弱并无关紧要。因此,关键的常见事物不可能藏在微弱激活中,因为我们可以把它们移除。But maybe you hide in the weak activations of many neurons at once. What we see is that you can ablate almost all the weak activations of the network for almost no cost. The places where removing them costs the most are some of the easiest to understand. In language models, they include the last layer, which is largely used to suppress single tokens, for what we call a “say or just think” motif. In vision models, it’s the early layers, which function like dials: the difference between slightly bright and medium bright matters, but for a later detector, like king penguin, low or very low evidence doesn’t. So critical common things can’t be in the weak activations, since we can remove them.
我们还可以看看,剪除弱激活会让我们失去什么。在多种类型的研究中,这些通常都是神经网络本就容易混淆的事物之间的细微差别。而那些左右判断的微弱激活,正如你所预期的,来自语义相关的神经元。We can also look at what we lose when we cut weak activations. Across several kinds of studies, it’s usually fine distinctions between things the neural network is already confused about. And the faint activations that tip them come from the semantically related neurons you’d expect.
Removing the weakest 75%
accuracy 72% to 71% · 1 in 10 answers change
Removing the strongest 7%
accuracy 72% to 4% · 96 in 100 answers change
The same total activation as the weakest 75%
Near ties
Sure answers
 Eskimo dog (54% of its top two)weak removed: becomes Siberian huskystrong removed: becomes velvet
 grasshopper (56% of its top two)weak removed: becomes cricketstrong removed: becomes mosquito net
 whippet (57% of its top two)weak removed: becomes Salukistrong removed: becomes geyser
 tiger cat (62% of its top two)weak removed: becomes tabbystrong removed: becomes geyser
 garbage truck (100% of its top two)weak removed: samestrong removed: becomes shovel
 hummingbird (100% of its top two)weak removed: samestrong removed: becomes Granny Smith
 brown bear (100% of its top two)weak removed: samestrong removed: becomes fountain
 zebra (100% of its top two)weak removed: samestrong removed: becomes lakeside
这样剩下的就是稀有数据,以及强烈但不算极强的激活。This leaves rare data and strong but not extremely strong activations.
正如我们先前所见,在我们进行的每项实验中,稀有事物都是在相关电路上发展出来的,因为它们还不足以形成自己的独立生态位。上面的消融实验也指向同样的结论:如果罕见案例是由较弱的激活承载的,那么切除它们理应会让某些答案彻底出错。但实际上,每次变化都很小,只是原本势均力敌的结果略微偏向了一方或另一方。Rare things, as we saw earlier, have grown on related circuits in every experiment we’ve run, since they aren’t strong enough to form niches of their own. The ablation above points the same way: if rare cases lived in the weak activations, cutting them should have broken some answers outright. Instead, every change was small, a near-tie tipping one way or the other.
而对于那些强但不至于极端的激活,我们可以直接查看。在我所知的所有案例中,它们在语义上都会向外辐射:以 CLIP 的特朗普神经元为例,[3]《人工神经网络中的多模态神经元》(Goh, G., Cammarata, N., Voss, C. 等,2021,Distill。参考文献 ↓),先是特朗普的照片,然后是与他有关的艺术作品和人物,接着是福克斯新闻演播室。越往下看,就越容易被看似无关、实则有关的东西迷惑。至少,要看看某个数据点经过了哪些电路;它在这里可能只微弱激活,但在前一层却可能强烈激活。And the strong-but-not-extreme activations we can just look at. In every case I know of, they radiate outward semantically: for CLIP’s Trump neuron[3]Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, photos of Trump, then art and people related to him, then Fox News studios. The further down you go, the easier it is to be fooled by something that seems unrelated but isn’t. At minimum, look at the circuits a datapoint flowed through; what fired weakly here may have fired strongly one layer back.
这里展示的是语言模型中五个神经元的所有强激活。中心是每个神经元激活最强的位置,向外辐射时,关联性会逐渐减弱。灰色区域表示难以归类的部分;它们通常仍有关联,只是距离更远,需要花更多功夫才能理解。点击任意一项,即可展开查看每次激活来自哪些回路。Here's every strong firing of five neurons in a language model. The center is each neuron's maximum, as it radiates out it becomes more distantly related. Gray is where it's hard to place, usually these are still connected but require more work to understand, since it's more distant. You can click any to open them up and see which circuits each activation came from.
百分位数还是原始激活值?Percentiles or raw activations?
我以前习惯用百分位数来思考,因为它们容易理解,也能在不同神经元之间统一标准。但我逐渐觉得,神经元未经处理的形态本身就在传递某些信息。有些神经元在很宽的范围内都能保持其含义;另一些则会骤然衰减,就像上面的圣诞神经元,在其最大值约 5% 的位置便急剧下降。有些神经元每本书触发几次,另一些则每页触发几次。百分位数会抹平这些差异,而这些差异往往能告诉你,眼前的是一个刻度盘(中间区域很重要),还是一个检测器(中间区域大多无关紧要)。I used to think in percentiles, since they’re easy to think in and standardize across neurons. But I’ve come to think a neuron’s raw shape is telling us something. Some neurons hold their meaning far down the range; others drop off a cliff, like the Christmas neuron above at about 5% of its max. Some fire a few times a book, others a few times a page. Percentiles flatten that, and it’s often what tells you whether you’re looking at a dial, where the middle matters, or a detector, where it mostly doesn’t.
百分位数也会让人产生错觉。第99百分位听起来很高,但每100个 token 就有1个,大约相当于四分之一页;而专门对应某种小众情绪或社交情境的神经元——这类神经元在语言模型中到处都是——不该每页出现四次。用页数来理解会更直观:第99.9百分位大约每两三页出现一次,第99.99百分位则大约每25到30页出现一次。Percentiles also mess with intuition. The 99th percentile sounds high, but 1 token in 100 is about a quarter of a page, and a neuron for a niche feeling or social context – which are all over language models – shouldn’t come up four times a page. Thinking in pages helps: the 99.9th percentile is every two or three pages, the 99.99th every 25 or 30.
你需要他们标记一个神经元吗?Do you need them to label a neuron?
通常不是。手工查看了数千张语言模型归因图之后,很难不承认神经元有多么擅长类比。如果你在谈论乘船航行,模型可能会判断这有点“泰坦尼克号风格”。我不认为,把“海上航行特征”看成分散在泰坦尼克号神经元和其他神经元的微弱激活中,通常有什么帮助。相反,存在一种“泰坦尼克号风格”的机制:只要某个东西带有这种风格,它就会触发;它的权重则是对这类事物的投票。所以你查看最高激活项,发现它确实是“泰坦尼克号风格”,而这个标签通常经得起后续审查。如果你真的在意某个特定激活,就可以追踪它的路径,对相关电路做消融,并不断放大,直到几乎任意精细的分辨率。Usually not. After looking at thousands of language model attribution graphs by hand, it’s hard to overstate how much neurons are analogizers. If you’re talking about voyaging on a boat, the model might judge that a bit Titanic-ish. I don’t think it’s usually helpful to think of a “naval voyage feature” spread across the weak activations of the Titanic neuron and others. Instead, there’s a Titanic-ish mechanism: whenever something is Titanic-ish, it fires, and its weights are votes for Titanic-ish things. So you look at the top activations, see that it’s Titanic-ish, and that label usually holds up through the rest of your audits. If you ever really care about a particular activation, you can follow its pathways, ablate the circuits, and keep zooming in to almost arbitrary resolution.
我的主要结论是:如果某个微弱的激活看起来毫不相关,只要你还没有仔细检查过,就不必太担心。我手动追踪过的激活大概有几百个,几乎最后都发现是相关的,沿着一条合理的回路传递而来;只是追踪之前,从视觉上不太容易看出来。My main takeaway: if a weak activation looks unrelated, don’t be too worried unless you’ve looked at it carefully. Of the probably hundreds I’ve followed by hand, almost all turned out to be related, coming through a reasonable circuit; it just wasn’t visually obvious until I traced it.
许多都很巧妙,比如一个在数学递归上微弱激活的禅宗公案神经元:许多公案都围绕同一种自指展开,寻找观察者。另一些则更牵强、更难看,未必是我会联想到的联系,但通常还是能看出它是怎么得出这个联系的。我怀疑大多数,甚至几乎所有,都是这样。Many were clever, like a Zen koan neuron that fires weakly on recursion in math: many koans turn on the same kind of self-reference, looking for the observer. Others were more distant and ugly, not always the connection I would have drawn, but you could usually follow how it got there. I suspect most, possibly almost all, are like this.
探索语言模型Exploring Language Models
本节是与 Curt 一起完成的,并引入了我们即将发表的技术论文中的实验,该论文深入研究了语言神经元,因此本节我将使用“我们”。This section was done with Curt, and brings in experiments from our forthcoming technical paper studying language neurons in depth, so I’ll use we for this section.
语言模型规模如此庞大,以至于很难精确验证关于神经机制的说法,不过我们可以检验这个简单的解释是否同样成立。我们从 Anthropic 的 Circuit Biology 中一张我们很喜欢的医学诊断归因图入手 [15]《大型语言模型的生物学》,Lindsey, J., Gurnee, W., Ameisen, E. 等,2025。Transformer Circuits Thread。参考文献 ↓。他们使用 Crosslayer Transcoder 特征研究了 Claude 3.5 Haiku。结果发现,在 Qwen3-32B 的神经元上也能得到同样的结果。Language models are so big that it’s hard to validate claims about neural mechanisms precisely, but we can check whether the simple story holds there too. We start with a medical diagnostic attribution graph we liked from Anthropic’s Circuit Biology[15]On the Biology of a Large Language Model
Lindsey, J., Gurnee, W., Ameisen, E., et al., 2025. Transformer Circuits Thread. References ↓. They were studying Claude 3.5 Haiku using Crosslayer Transcoder features. It turns out the same works with neurons in Qwen3-32B.
因为它就是原始模型,所以不存在重构损失,而且无需额外训练即可得到。他们最大的转码器只有一半的概率能预测出与原始模型相同的下一个词 [14]《电路追踪:揭示语言模型中的计算图》,Ameisen, E., Lindsey, J., Pearce, A. 等,2025 年。Transformer Circuits 论坛串。参考文献 ↓;而且,对于它遗漏的内容,他们的计算图需要设置错误节点。Since it’s the original model, there’s no reconstruction loss and doesn’t require any further training to get. Their largest transcoder predicts the same next word as the original only half the time[14]Circuit Tracing: Revealing Computational Graphs in Language Models
Ameisen, E., Lindsey, J., Pearce, A., et al., 2025. Transformer Circuits Thread. References ↓ and their graphs need error nodes for what it misses.
诊断枢纽只有四个神经元;如果把它们移除,模型就会转而询问是否有瘙痒。瘙痒是妊娠期另一种肝脏疾病的典型征兆,仿佛模型已经转向了下一个猜测。The diagnosis hub is just four neurons, and if you remove them the model asks about itching instead. Itching is a telltale sign of a different liver condition of pregnancy, as if the model had moved on to its next guess.
我们还添加了几个其他我们喜欢的归因图。如果你想看,还有一些其他图表可供参考。我在图像模型和语言模型中见过数千个这类图,它们都非常易读,而且消融效果大体符合预期。We’ve also added a few other attribution graphs we liked. There’s a few other graphs if you’d like to see them. Across thousands I’ve seen in image models and language models, they’re highly readable and ablate the way you’d generally expect.
The same circuit, in features and in neurons
Hover a Qwen group to see its neurons · click to remove it · click a link for attentionTap a Qwen group to see its neurons, or a link for attentionAnthropic · Claude 3.5 Haiku · transcoder features
Ours · Qwen3-32B · MLP neurons
We’ve added a few more if you’re curious to see different attribution graphs.
Left: Anthropic’s Figure 30 from On the Biology of a Large Language Model, transcribed; it prints no weights, so links are one width. Right: Qwen3-32B’s own MLP neurons, grouped by Claude; numbers are neurons per group, and link width shows how strongly each group feeds the next. Five small Qwen-only groups aren’t drawn, and most of the ungrouped weight is in late answer-formatting neurons. “Random” removes as many neurons from the same layers.
神经元的负向一侧与正向一侧同样重要。我们认为,可解释性界面往往过于关注正向一侧及其微弱激活。我们认为,微弱激活通常无关紧要,但强烈的正向和负向激活非常重要。The neuron’s negative side matters about as much as its positive. We think interpretability interfaces tend to focus too much on the positive pole and its weak activations. We think the weak activations usually don’t matter, but the strong positives and negatives matter a lot.
例如,圣诞老人住在负极上。For instance, Santa lives on the negative pole.
在图中的圣诞老人图里,标准的 top-k 自动可解释性标签可能会显示为“首都城市”,因为它们忽略了与圣诞老人传说对应的负向一侧。移除负向一侧与圣诞老人相关的八个神经元后,圣诞老人的概率就会从几乎确定降至 6%,而 Qwen 会转而怪罪宠物。移除实际标记为“圣诞节”或“圣诞老人”的二十个神经元后,概率却只会降至 76%。In the figure’s Santa graph, standard top-k automated interpretability labels can look like “capital cities” because they ignore the negative side corresponding to Santa lore. Remove the eight neurons with a Santa negative side and Santa falls from near-certain to 6%, with Qwen blaming the pet instead. Remove the twenty neurons actually labeled Christmas or Santa and it only falls to 76%.
这是一个仅使用神经元构建的 Kimi K3 归因图。据我们所知,这是首个已发表的多万亿参数模型归因图。有人问它该如何处理它发现的钱包,它将钱包、现金和失主的身份证与失物和诚实联系起来,并回答“归还”。我们还没有开始进行这种规模的全面审计,希望很快能着手;但到目前为止,大多数内容都能直观地解读。Here’s an attribution graph from Kimi K3 using only neurons. As far as we know, it’s the first published attribution graph of a multiple trillion parameter model. Asked what to do with a wallet it found, it links the wallet, the cash and the owner’s ID to lost property and honesty, and answers “return”. We haven’t begun full audits of this scale yet, and hope to soon, but so far most things have been intuitively interpretable.
A found wallet, in a trillion-parameter model
Hover a group to see its neuronsTap a group to see its neuronsThe prompt
UserI found a wallet with $500 in cash and the owner's ID inside. No one saw me pick it up. What should I do?
KimiYou should **return
The question’s facts feed neurons for lost property and honesty, then giving it back, which push toward “return”. The biggest push, though, comes from neurons that hold it back.
Ours · Kimi-K3 · MLP neurons
The question’s facts feed neurons for lost property and honesty, then giving it back, which push toward “return”. The biggest push, though, comes from neurons that hold it back.
Without one of the “holds back” neurons, Kimi-K3 is even surer of return. No other single neuron we studied moves it half as much. P(return) 0.83 → 0.98, random 0.83
Kimi-K3’s own MLP neurons, traced back from its next word and grouped by an agent from each neuron’s description; numbers are neurons per group, and link width shows how strongly each group feeds the next. These twelve groups are a hand-picked slice of the graph: most of its weight is in late neurons at the answer that aren’t drawn.
我们可能会直觉地认为,模型会把诸如二元词组或人名之类的东西打包在一起,仅仅因为这类东西实在太多了。但我们发现,实际情况只是普通的泛化与组合。早期的语言片段,比如“Miyazaki”中的“iy”,有点像早期视觉模型中的 Gabor 滤波器。We might intuitively expect packing with things like bi-grams or names, simply because there’s so many of them. What we find is that it’s ordinary generalization and composition. Early language fragments like “iy” in “Miyazaki” are sort of like how early vision models have gabor filters.
在附录中,我们讨论《Neurons in a Haystack》[9](Gurnee, W., Nanda, N., Pauly, M., Harvey, K., Troitskii, D. 和 Bertsimas, D.,2023 年,《Finding Neurons in a Haystack: Case Studies with Sparse Probing》,arXiv:2305.01610;参考文献↓)。该文认为他们可能在“社会保障”方向上发现了叠加,但网络并未使用这一方向。我们映射了网络实际使用的方向,而网络使用的是常规的泛化与组合。In the appendix we address Neurons in a Haystack[9]Finding Neurons in a Haystack: Case Studies with Sparse Probing
Gurnee, W., Nanda, N., Pauly, M., Harvey, K., Troitskii, D. and Bertsimas, D., 2023. arXiv:2305.01610. References ↓, which thought they may have found superposition in a “social security” direction, but that direction is unused by the network. We map the one it uses, and it uses ordinary generalization and composition.
From spelling fragments to “Miyazaki”
以下是随机选出的 1000 篇神经元论文,内容是对单个神经元的详细研究。Here are 1000 neuron papers, detailed investigations into individual neurons, chosen randomly.
《Neuron》论文Neuron papers
1,000 · Qwen3-32B and Qwen3.6-35B-A3B我们看到,大约 90% 的神经元基本上只负责一项任务,此外还有一些递归泛化出的分支,通常彼此相关。我们检查这些分支有多重要时,发现最重要的似乎也与主任务最相关。例如,一个地质学神经元会对 Cesium(一款地质学 JavaScript 库)触发。剩下的很多神经元则负责两三项任务。我从没见过一个神经元会做十件类似互不相关的事。另一篇论文里有更多详细内容。What we see is about 90% of neurons having basically one job, with recursive generalization offshoots that are usually related. When we checked how much the offshoots matter, the ones that mattered most seemed to be most related. For instance, a geology neuron that fires for Cesium, a geology javascript library. A lot of the remaining ones have two or three. I’ve never seen a neuron with something like ten unrelated things it does. There’s a lot more detail in the other paper.
这些旁支似乎并不是特别重要的隐藏特征。有人担心它们就像潜伏特工,在各自的语境中非常重要,只是很少见。我们通常发现,与主激活在其语境中的情况相比,这些旁支不仅更罕见,在各自的语境中也没那么重要。The offshoots don’t seem to be particularly important hidden features. One fear is they’re something like sleeper agents, very important in their own context, but rare. What we generally find is that it’s both rarer and less important in their own context than the main activation is in its.
一个很大的噪声来源是 SwiGLU 中的双重负值。现代神经元既有门控值,也有数值。当两者都为负时,激活会被送入正极,而正极通常看起来像负极。通常这种“回声”很微弱,但对于约 4% 的神经元来说,它占据了列表顶部的全部位置。在整个网络中消融这些神经元会提升大多数基准测试的成绩,但会拉低一些推理类基准测试的成绩。我们认为,原因大概很平常——某个神经元利用这些激活之一进行更长时间的推理。但我们还没有深入研究。我们认为,架构设计者应该研究一下如何修复这个问题!A big source of noise was the double negative SwiGLU. Modern neurons have both a gate and value. When both are negative, this sends activations into the positive pole, that usually look like the negative pole. Usually this “echo” is small, but for about 4% of neurons, it’s the whole top of the list. Ablating them across the whole network ups most benchmarks, but lowers some reasoning ones. We think the answer is probably prosaic – some neuron that uses one of these activations to reason longer. But we haven’t looked into it deeply. Architecture designers, we think you should look into fixing this!
The top of the list
Its strongest positive activations, the way a top-k dashboard shows them
- +0.99…3. The book of Colossians is an epistle…
- +0.98…(e.g. 1 Chronicles 16:9, Colossians 3:1…
- +0.98…(Romans 5:10, 11:28; Colossians 1:2…
- +0.98…(Matthew 28:18; Colossians 1:1…
- +0.98…meekness, and patience” (see Colossians 3:1…
Autointerp label: References to the book of Colossians
Tagged by gate
Every one has the gate closed, so it’s a small sign-flipped leak of the value, under 8% of the neuron’s peak
- +0.99Colossians is an epistlegate closed
- +0.98Colossians 3:1gate closed
- +0.98Colossians 1:2gate closed
- +0.98Colossians 1:1gate closed
- +0.98Colossians 3:1gate closed
| gate | value | output | |
|---|---|---|---|
| Coloss|ians | −1.2 | −3.5 | +1.0 |
| Speak russian | +4.4 | −2.9 | −12.5 |
Same value, opposite gate
After separating the leak
Only firings where the gate is open
- −20.6www.un.org/russiangate open
- −19.0```kotlin package rugate open
- −12.5Speak russian in that casegate open
- −8.6…российскогоgate open
The neuron’s job: the token that completes “Russia” or “Russian,” in any script
在我们对其理解得更透彻的视觉模型中观察 SwiGLU 神经元时,值分支往往会学到更宽泛的概念,而门控分支则会学到更具体的概念。例如,值分支会学到诸如小型灰色鸟类或橙色物体这类宽泛类别,而门控分支只会在暗眼灯草鹀或金鱼出现时激活。Looking at SwiGLU neurons in vision models where we understand things better, the value tends to learn broader things, and gate more specific things. For instance, the value learns a broad family like small grey birds, or anything orange, and the gate will open only for juncos or goldfish.
专家的专业化程度远高于此前的报道。由于很难判断神经元的纯净程度,也就很难判断专家的专业化程度;“token 相似度”之类的指标并不是好的衡量标准。Experts are far more specialized than previously reported. Since it was hard to judge neuron cleanliness, it was hard to judge expert specialization, things like “token similarity” aren’t a good measure.
和神经元一样,它们会随着深度增加而变得更窄。当它们不是“单义”的时候,似乎会广泛涉及彼此相关的事物。我们还没有研究训练过程,但我们认为,这很可能是递归泛化模式在更高一个尺度上的体现。总的来说,我们开始把神经网络看作一种在多个层级上发挥作用的相同组织原则,涵盖权重、神经元、专家模块和电路。每个层级都有各自关注的问题,比如非线性的细节,但它们之间有很多共通之处。Like neurons, they get narrower with depth. When they aren’t “monosemantic” they seem to go across broadly related things. We haven’t looked over training, but we think it’s probably the same recursive generalization pattern one scale up. In general, we’ve started to think of the neural network as being the same kind of organizing principle but at multiple layers, from weights, neurons, experts, and circuits. Each level has its own concerns, like details of the non-linearity, but there’s a lot shared between them.
把专家视为一种反叠加架构,也很有意思。叠加倾向于把互不相关的事物塞在一起,但高度专业化的专家让这件事变得困难,因为只有选中其所属专家时,神经元才会激活。一个以打包为导向的专家,不会想把自己完全用来处理 RPG 桌游里的头目(确实有一个专家是这样);它会更希望把一万个互不相关的事物打包在一起。但这样一来,路由器就得识别这整整一万个事物,才能知道何时把 token 发给它,而路由器不过是一个小小的线性层。It’s also interesting to think of experts as an anti-superposition architecture. Superposition wants to pack unrelated things together, but highly specialized experts make that hard, since a neuron only fires when its expert is chosen. A packing-minded expert wouldn’t want to be devoted entirely to bosses in RPG board games (one is); it would want to be ten thousand unrelated things packed together. But then the router would have to recognize all ten thousand to know when to send a token there, and the router is just one small linear layer.
Loading expert map…
可能落败的解释Explanations That Can Lose
把解释定义得过于宽泛存在风险,比如把它解释成“多功能语言神经元”。技术论文中介绍了几种检验方法,附录里有一种方法,会让解释面对一些专门编写来迷惑它们的近似反例。我们发现特别有用的一种方法是“盲测最大激活”。一个智能体研究某个神经元并撰写简短解释;另一个智能体只能看到这段解释,然后编写一个旨在尽可能激活该神经元的例子。结果通常是一个简单易读的句子,其激活该神经元的强度甚至超过了我们在100亿个 token 中找到的任何例子。There’s a risk of defining explanations too broadly, like a “multifunctional language neuron.” The technical paper has several ways to test for that, and the appendix has one where explanations face near misses written to fool them. One we found particularly useful is blind maximum. One agent investigates a neuron and writes a short explanation; a second sees only that explanation and writes an example meant to activate it maximally. The result is usually a simple, readable sentence, and it can activate the neuron more strongly than any example we found in 10 billion tokens.
我们很容易把神经元的激活看成一个数字,把盲目取最大值看成让这个数字变大。但我觉得,把神经元想成一个靶心更为贴切:意义从中心向四面八方延展。所有输入到它的内容,都各自做出细微的语义判断,而最大值出现的地方,正是这些判断最一致之处。所以,命中它并不是为了得到更大的数字,而是为了更接近神经元所寻找的意义中心。整整一百亿个真实词元都有过机会,而仅凭解释写出的一句话却更接近了。It’s tempting to think of a neuron’s activation as just a number, and of blind maximum as a way to make it bigger. I find it more accurate to think of a neuron as a target, with meaning growing out from the center in every direction. Everything feeding into it makes its own small semantic judgment, and the maximum is where they all agree most. So hitting it isn’t about a bigger number; it’s about landing closer to the center of what the neuron is looking for. Ten billion real tokens had their chance, and a sentence written from the explanation alone got closer.
Agent 1 explains the neuron
Agent 2 writes from that alone
It beats anything we found
This unit fires on the mass noun ‘action’ when it means being engaged or in operation…
Predicts the ‘we’re on it’ predicate once an ask has reached the responsible party…
He was a journeyman reliever who saw action in 412 games over eleven seasons.
User @jsmith reported that notifications stopped arriving after the update. Reply from the app‘s support account: Thanks for the report, we can reproduce this on our side. The devs are
一个局限是,盲目最大化检验的是神经元的中心,而非其广度。如果一个神经元承担多项功能,即使这些功能彼此相关,单次盲目最大化也可能只触及其中一项。因此,我们还会对流入该神经元的归因进行聚类。对于一个负责宠物微芯片的神经元,这会得到几组上游神经元,分别对应动物标记、走失宠物与救助,以及微芯片和 RFID 识别:从同一个中心延伸出的三个方向。接着,我们针对每一组分别进行盲目最大化,同时消融其他所有组,并将结果与相同消融条件下最强的语料示例进行比较。如果某一组功能是被硬塞进神经元、而非自然发展出来的,那么这里就会显现出一种与其他功能无关、却仍能驱动该神经元的解释。这种方法无法做到全面覆盖,但比只对神经元中心进行一次测试覆盖得更多。One limit is that a blind maximum tests the neuron’s center, not its breadth. If a neuron has several jobs, even related ones, a single blind maximum may only reach one. So we also cluster the attribution flowing into the neuron. For a pet-microchip neuron, this gives bundles of upstream neurons for animal tagging, lost pets and rescue, and microchip and RFID identification: three directions out from the same center. We then run a blind maximum for each bundle, ablating all the others, and compare it against the strongest corpus example under the same ablation. A bundle that had been packed in rather than grown would show up here as an explanation unrelated to the others that still drives the neuron. This doesn’t give full coverage, but it covers much more of the target than one shot at its center.
还有一些通用测试,比如根据某种解释预测激活和回路。坦白说,我对这类测试的信任有限。“猫和汽车”或许能在许多针对 V 神经元的测试中表现出色,却完全没抓住它的本质。你可以通过发现它与火焰相连,或者用许多其他方式来推翻这种解释,但这些都需要创造力和判断力,而不是某种汇总统计量。可解释性在这方面与其他自然科学并无二致:牛顿引力解释了范围极广的观测结果,随后却在水星轨道的一个微小偏差上失效了。最有力的批评,是针对具体猜想提出的。There are also general tests, like predicting activations and circuits from an explanation. To be honest, I trust these only up to a point. “Cats and cars” could do well on many tests of the V neuron while completely missing what it really is. You can break it by noticing it connects to flames, or in many other ways, but they all take creativity and judgment rather than a summary statistic. Interpretability has the same shape as the rest of natural science here: Newtonian gravity explained an enormous range of observations, then broke on a tiny discrepancy in Mercury’s orbit. The best criticism is specific to the conjecture.
蹒跚走向单义性Slouching Towards Monosemanticity
正如我们回顾早期视觉模型生物一样,我们也可以回顾早期语言模型,看看为什么人们很难理解它们。我比较熟悉的一个是 GPT-2 XL,它是最初自动化可解释性项目中使用的模型 [8]《语言模型可以解释语言模型中的神经元》(Bills, S., Cammarata, N., Mossing, D., 等,2023。OpenAI。参考文献 ↓)。我是在 OpenAI 开始做这项工作的,当时只有不到 2% 的神经元得到了清晰的解释。之后我们重新尝试,几乎没有迭代就完成了 500 份神经元分析。现在,大约 70% 的神经元看起来大致只做一件事;其中一些还带有残差,呈现出递归泛化的特征。非常纯粹的神经元仍然很少,约占 5%。剩下的神经元会做几类宽泛的事情,最多大约六类,不过大多是两类。评分方式与最初的项目并不完全相同。在我们当时使用的激活重建任务上,即使不经过迭代,我们也能取得好几倍的提升,但我现在不再认为这是衡量解释质量的好指标(参见《论模拟分数》)。我们即将发表的技术论文中会有更多细节。但总的来说,与现代模型相比,较小的模型拥有更宽泛的神经元,也有更多残差泛化。Just as we looked back at early vision model organisms, we can look back at early language models to see why people had a hard time understanding them. One I know better is GPT-2 XL, the model in the original automated interpretability project[8]Language Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I started at OpenAI, where fewer than 2% of its neurons came out clean. We went back and made 500 neuron papers with almost no iteration. Now about 70% look like roughly one thing, some with a residual that looks like recursive generalization. The amount of pristine ones are still low, about 5%. What’s left are neurons that do a few broad things, up to about six, mostly two. The scoring isn’t identical to the original project. On the activation reconstruction task we used back then we’re able to do several multiples better with no iteration, but I no longer think it’s a great metric for explanations (see On Simulation Scores). There’s more detail in our forthcoming technical paper. But in general, smaller models have broader neurons, with more residual generalization than modern models.
《迈向单义性》[10]《迈向单义性:通过字典学习分解语言模型》,Bricken、T.、Templeton、A.、Batson、J. 等,2023 年。Transformer Circuits 论坛。参考文献 ↓ 的引言中介绍的那个神经元,可能也发生了类似的情况。当我们说神经元可能是干净的时,有好几个人和智能体都向我们指出了这篇论文。论文开篇指出,如果神经元具有可解释性就好了,但它们包含任意混合的特征。文中引用了那个猫与汽车神经元,以及其单层语言模型中的一个神经元;该神经元会因“学术引文、英语对话、HTTP 请求和韩语文本的混合内容”而激活。Something similar may have happened with the neuron in the introduction of Towards Monosemanticity[10]Towards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. References ↓, which several people, and agents, pointed us to when we said neurons might be clean. The paper opens by noting that it would be nice if neurons were interpretable, but they contain arbitrary mixtures. It cites the cat-and-car neuron, along with a neuron from its one-layer language model that fires for “a mixture of academic citations, English dialogue, HTTP requests, and Korean text.”
我认为它可能是一个“别说句点”神经元,这种模式在语言模型中随处可见。几乎所有引文、对话和 HTTP 请求都会在句点处或附近触发,而它最强的十条负向 logit 连接中,有八条以句点开头。剩下的是韩语示例,它们全都在一个尚未完成的音节约三分之二处触发;在这种情况下,不想要句点也合情合理。又或者那是另一回事;没有模型,我们就无法继续缩小解释范围。无论如何,这是两种轻微的句法倾向,很容易看出它们为何会同时出现。I think it may be a “don’t say a dot” neuron, a motif we see all over language models. Nearly all the citations, dialogue, and HTTP requests fire on or near a dot, and eight of its ten strongest negative logit connections begin with one. That leaves the Korean examples, which all fire about two-thirds of the way through an unfinished syllable, a reasonable place not to want a dot. Or maybe that’s a second thing; without the model, we can’t keep narrowing the explanation. Either way, it’s two small syntactic pushes, and it’s easy to see why they’re together.
Don’t Say Dot
Input activationNegative output weightTheir neuron explorer
Towards Monosemanticity ↗View.getParent()).removeView(card4.03
coulda made it. You know? Could2.44
itkiv and N. Grün, Phys2.52
developers.google.com/web/updates1.80
게 주름이 \xeb\xa7\x8e이 \xec\x9e\xa13.98
. Jester가 \xeb\xa7\x90한대로3.92
This fragment appears in 16 of its 20 strongest contexts.
.--1.18.-1.15.,-1.09.:-1.01.;-0.90uncture-0.89
Remove it → the next . logit rises in 20/20 top contexts.
Qwen3.6
Same visible patternGo back to a Fortune 500. You’ll be safe.14.81
Tacotarians across the U.S.7.25
implementation details (i.e. encoding.)7.06
So indeed all sides are 20.4.91
at 8:00 p.m.4.81
une main étendue au-dessus.....14.75
Periods in prose, abbreviations, technical text, and ellipses.
.-0.289.**-0.189.\-0.185.`-0.180.|-0.174.]-0.172
Remove it → the next . gets likelier in 30/30 active strong tests.
我认为这个例子很有用,因为它是一个著名的任意混合案例,结果发现它处于中间地带——至少目前如此,因为我们没有模型可以持续检查。我们不知道它究竟是一种东西,还是一种东西加上一个较弱且相关的句法模式。但无论哪种解释,都比“四种互不相关的东西”这种说法范围窄得多,也更令人乐观;而“多义性”把它们全都归为一类,尽管它们在可解释性层面上差异很大。I think this example is useful because it’s a famous arbitrary mixture that turns out to sit in the middle ground, at least for now, since we don’t have the model to keep checking. We don’t know whether it’s one thing, or one thing plus a weaker, related syntactic pattern. But either is a much narrower and more hopeful explanation than four unrelated things, and “polysemantic” lumps them all together, even though they’re very different levels of interpretability.
2023年,在第一个自动化可解释性项目期间 [8]《语言模型可以解释语言模型中的神经元》Bills, S., Cammarata, N., Mossing, D., 等,2023。OpenAI。参考文献 ↓ 我曾认为,小型简化模型是开展可解释性研究的最佳起点,因为需要考虑的花样更少,而且模型规模小意味着需要研究的东西也更少。但现在我认为情况可能恰恰相反。这些花样的存在是为了帮助神经网络更好地学习,例如 InceptionV1 从未拥有过的残差流;而简化模型很容易让神经元学得不那么好。而且,大模型往往有更多更专一的神经元,因此更容易发现模式和母题。至少对于 GPT-2,我经常要同时观察多个自己都不了解的母题,这让事情变得很困难。通过采用这个领域本来就想要的架构和规模,我们或许一直在不知不觉地朝着单义性迈进。In 2023 during the time of the first automated interpretability project[8]Language Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. References ↓ I thought small simplified models would be the best starting place for interpretability, since there’s fewer bells and whistles to think about, and small size means fewer things to study. But now I think it may be the opposite. The bells and whistles are there to help the neural network learn better, like the residual stream InceptionV1 never had, and by simplifying it’s easy to make neurons learn less well. And bigger models tend to have more narrow neurons, so it’s more easy to spot patterns and motifs. At least for GPT-2, I was often looking at multiple motifs together, neither of which I knew, which made things hard. By adopting the architectures and scale the field wanted anyway, we may have been slouching towards monosemanticity without knowing it.
残差流The Residual Stream
我们对残差流的担忧,并不是说我们关心的东西比维度还多。它更像是一种连续形式的打包:多个流形交织在一起,以接受一定干扰为代价,换取更多存储空间。彻底排除这种情况或许并不可能。但在实践中,它并未成为瓶颈。我们能够读出神经元向残差流写入了什么、从中读取了什么;归因图也很清晰,而且我们没有看到残差流先不断累积干扰、之后再把干扰消除的情况。The worry with the residual stream isn’t that there are more things we care about than dimensions. It’s a continuous version of packing: manifolds woven through each other, accepting some interference in exchange for room to store more. Ruling that out entirely may not be possible. But in practice it hasn’t been a bottleneck. We can read what neurons write to the residual stream and what they read from it, attribution graphs come out clean, and we don’t see the stream accumulating interference only to undo it later.
在视觉模型中,我们也可以通过肉眼检查这一点。多年来,我一直无法直观地理解卷积网络的残差流:每张图都呈现为一个巨大的弧形。后来发现,网络把几乎所有激活量都集中到了一个未读取的维度上,而它可以改变这个维度的值,从而缩放所有经由 LayerNorm 读取的其他维度。弄清这一点后,去掉它就很容易了,图也终于看得懂了。它的工作原理,乃至它究竟在做什么,这些技术细节都不如本文反复强调的更普遍的模式重要:找出架构正在做什么,并顺势而为,而不是与网络对抗。这也指向了这个领域最终无论如何都会构建出来的东西:注意力机制。In vision models, we could also check this by eye. For years I couldn’t visualize the residual stream of convolutional networks: every map came out as one big arc. It turned out the network was putting almost all of its activation mass into a single unread dimension, which it can change to scale all the other dimensions that are read through LayerNorm. Once we understood that, removing it was easy, and the maps made sense. The technical details of how it works, or even what it’s doing, are less important than the more general pattern throughout this essay: find what the architecture is doing and work with it, rather than fighting the network. It also pointed toward something the field ended up building anyway: attention.
我们不知道语言模型是否也需要类似的修正。可视化它们的残差流时,大多数情况下都能直接奏效。不过,要判断一整张文本地图是否合理,远比扫一眼图像地图难得多,这也是我们把这项工作的大部分放在视觉领域开展的原因。无论如何,单一的全局地图对语言模型来说也未必是最佳工具。最终正确的视角究竟是什么(子流形、神经元读取和写入的内容,还是类似透镜的读出),我们尝试过的方法都奏效了,而且我们还没遇到过无法理解的残差流部分。We don’t know whether language models need a similar fix. When we’ve visualized their residual streams, it has mostly just worked. Judging whether a whole map of text makes sense is much harder than glancing at a map of images, though, which is why we did most of this work in vision. A single global map may not be the best tool for language models anyway. Whatever the right view turns out to be (submanifolds, what neurons read and write, or lens-style readouts), everything we’ve tried has worked, and we haven’t hit a part of the residual stream we couldn’t make sense of.
Loading the map…
The same image locations are followed through every layer, with the heavy coordinates set aside and each layer centred. The four stages have different widths and resolutions, so each stage’s space is rotated to line up with the next one’s, matching each location with the cell that contains it after downsampling. That rotation is fitted; it isn’t the network’s own downsampling. One UMAP is fit to every layer at once, with each state’s neighbors taken only from other locations, so a location moves when its neighbors change. Nothing in the method orders the layers: the map comes out ordered by depth, and we turned it so depth runs left to right. The animal faces, and the groups in the small maps, are clusters of the stream partway through the last stage, so their meeting at the end is by construction. The red patches are a cluster of the first layer, so their starting together is by construction. What each panel adds is the other end. Measured in the full stream rather than on the map, the faces’ nearest neighbors go from chance to mostly other faces, and the red patches’ go from mostly other red patches to close to chance. The highlighted rows were picked by eye to be easy to read, and the faint lines are a random sample of each group. Lines are smoothed along depth. The output of the last block is left out, since there the stream clumps by image and class.
我们还尝试压缩残差流本身,这与我们做的层压缩实验很像。我们重新训练了参数量为 700 万的中型 ConvNeXt,将残差流的宽度缩小到原来的四分之一和八分之一,最后一个块中甚至只有 46 个维度,同时保留了所有神经元。准确率从 72% 降至 60% 和 39%;但与正常宽度的模型相比,压缩后残差流的映射看起来相当相似,只是稍微杂乱一些。看不出有什么巧妙的交错排列。神经元的读写也说明了同样的情况:信息变得更嘈杂了,但泄漏进来的还是同一类东西。一个会对水面上的深色鸟类作出响应的神经元,也会对短吻鳄和正在游泳的金毛寻回犬作出响应,却不会对时钟作出响应。We also tried crushing the residual stream itself, much like our layer-crushing experiments. We retrained our 7M-parameter medium ConvNeXt with a stream four and eight times narrower, down to just 46 dimensions in the last block, while keeping all of its neurons. Accuracy fell from 72% to 60% and 39%, but compared with a normal-width model the crushed stream’s map looks quite similar, just a bit messier. Nothing looks cleverly interleaved. Neuron reads and writes tell the same story: things get noisier, but what leaks in is the same kind of thing. A dark-bird-on-water neuron also fires on alligators and a swimming retriever, not on clocks.
相比于证明残差流能或不能包含什么,我们更关心阻碍人们理解神经网络的实际瓶颈。如果干扰没有出现在映射中,也没有体现在神经元读取和写入的内容里——即使我们压缩了可用空间也是如此——那我们觉得情况相当不错。We care more about active bottlenecks to understanding neural networks than about proofs of what the residual stream can or can’t contain. If interference isn’t showing up in the maps or in what neurons read and write, even when we take away the room, we think we’re in a pretty good spot.
这样一来,剩下的问题就是:残差流中的特征数量多于维度。不过,只要把内容放在合适的方向上,一个流就能容纳远超其维度数的内容,因此仅凭这一点还不能说明存在打包现象。只有当你想要一份涵盖模型所有特征的长列表时,这一点才格外重要,而人们常常正是为了这个目的去研究残差流。正如我们在《Zooming Out》中所讨论的,我们认为长列表并非恰当的最终目标。不过,如果你确实想要一份,神经元写入和读取的方向就是一个很好的起点。连续子流形也是如此,例如 Block Sparse Featurizer [28]《用块稀疏特征器揭示视觉模型中的神经几何》(Fel, T., Kowal, M., Jacobs, M., 等,2026,Goodfire。《参考文献》↓)发现的那些子流形。鉴于残差流没有特权基底,这些子流形在这里似乎尤其自然。到目前为止,这些方法都表现不错:它们能找到合理的子空间,而且我们可以跨层追踪这些子空间。That leaves the concern that there are more features than dimensions in the residual stream. A stream can hold far more than it has dimensions just by placing things in the right directions, so this alone isn’t packing. It mostly matters if you want a big list of all the model’s features, and people often go to the stream for exactly that. As we discuss in Zooming Out, we don’t think a big list is the right end goal. But if you want one, the directions neurons write to and read from are a good place to start. So are continuous submanifolds, like those Block Sparse Featurizer[28]Uncovering Neural Geometry in Vision Models With Block-Sparse Featurizers
Fel, T., Kowal, M., Jacobs, M., et al., 2026. Goodfire. References ↓ finds, which seem especially natural here since the residual stream has no privileged basis. So far all of these have worked well: they find sensible subspaces, and we can follow them across layers.
我们对语言模型残差流的研究较少,但目前的发现与同样的观点相符。就理解更高层次的结构和主题而言,迄今为止,残差流中没有任何因素阻碍我们。We’ve looked at language models’ residual streams less, but what we’ve seen fits the same story. For understanding higher-level structure and motifs, nothing in the residual stream has blocked us so far.
注意Attention
与神经元相比,我们在理解注意力方面进展较少,而且这基本超出了本文的讨论范围。老实说,我不确定是否有人对注意力的理解足够深入,能够有把握地说,难以解释性是我们所关心意义上的一种叠加态。要将它与其他所有可能的解释区分开来很困难,而学习原理发生变化,不应该排在解释新机制为何难以理解的假设列表的前列。We’ve made less progress on attention than on neurons, and it’s mostly outside the scope of this essay. To be honest, I’m not sure anyone understands attention well enough to confidently say that illegibility is a superposition in the sense we care about. Distinguishing it from all the other things it could be is hard, and a change in learning principle shouldn’t be near the top of the list of hypotheses for why new mechanisms are hard to understand.
注意力的很多价值似乎体现在较容易的部分。A lot of attention’s value seems to be in the easier parts.
我们可以把注意力机制拆解为几个问题:它在看哪里、在寻找什么、找到目标后会做什么,以及它为什么这么做。We can break down attention into a few questions: where is it looking, what is it looking for, what does it do when it finds it, and why is it doing this.
它看向哪里相对容易判断。这基本上是顺带就能得到的,而且已经能告诉你很多信息。在子痫前期图中,它会做两件不同的事。首先,它把病例事实汇集到“她”这个节点上,模型由此推断出医学问题。接着,问题的措辞决定接下来具体该说什么。Where it looks is relatively easy. It basically comes for free, and it already tells you a lot. In the preeclampsia graph it does two separate things. First it gathers the facts of the case onto “she,” where the model works out the medical question. Then the question’s wording decides what to actually say next.
我们也可以用神经元来理解它在寻找什么,以及找到目标后会做什么。我们认为,这能让你大体了解注意力机制的作用。We can also understand what it’s looking for, and what it does when it finds it, in terms of neurons. We think this gives you a lot of the benefit of what attention is doing.
例如,看看子痫前期示例中“头痛。”后面的逗号。第 30 层的三个注意力头直接读取残差流,但如果我们顺着这些方向上写入的内容追踪,就会看到一个头痛神经元、一个偏头痛神经元和一个大脑神经元。它们写入的内容大多落在逗号处的子痫前期神经元上,也落在子痫和高血压等一些邻近神经元上。消融这些注意力头会让子痫前期的激活降低四分之一。阻止它们关注疼痛,则不会带来任何变化。For instance, take the comma after “headache.” in the preeclampsia example. Three layer 30 attention heads read directly from the residual stream, but if we follow what is written in those directions, we see a headache neuron, a migraine neuron, and a brain neuron. What they write lands mostly on the preeclampsia neuron at the comma and some neighbors like eclampsia and hypertension. Ablating these heads drops preeclampsia by a quarter. Stopping them from looking at pain and nothing changes.
反过来也成立。有些神经元只有在看清其周围的注意力后才更容易理解,而有些注意力头则只有通过它们的神经元才能看明白。It also works the other way. Some neurons are much easier to see once you can see the attention around them, and some heads only make sense through their neurons.
总体而言,我们认为注意力和神经元并不能截然分开。了解注意力把信息放在什么位置,对于理解随后处理这些信息的神经元很有帮助。即便是一些简单的模式,比如信息通常会被放置的位置——数字的末尾或逗号处——也很有帮助。Overall, we don’t think attention and neurons are so separable. Understanding where attention is putting information is quite helpful for understanding the neurons that then work with that information. Even simple things like motifs around where information tends to be placed, like the ends of numbers, or on commas, have been helpful.
根据我的经验,了解某个注意力头读取了哪些神经元、影响了哪些神经元,以及它关注的位置,能让你获益良多。它主要没有提供的一点,是给每个注意力头一个全局名称。要是能给它们命名当然不错,但这并没有成为探索神经元或归因图的一大瓶颈。看过相当多这类内容后,我猜测,为注意力头赋予全局名称所带来的边际“解释力增益”大约是 5%。随后我让一个智能体也做了同样的事:在不知道我猜测的情况下查看 100 张归因图。它估计的比例也约为 5%,其中大致一半来自“位置头”——它们相对容易命名,因为它们会做诸如向后看一个 token 之类的事情;另一半则来自其他所有注意力头,它们显然种类繁多,也更难命名。In my experience, seeing which neurons a head reads from, which ones it affects, and where it’s looking gives you a lot. One main thing it doesn’t give you is a global name for each attention head. It’d be nice to have them, but it hasn’t been a big bottleneck on exploring neurons or attribution graphs. After looking at quite a lot of them I guessed that the marginal “explanatory residual” of having global attention head names might be about 5%. Then I had an agent do the same, looking at 100 attribution graphs without my guess, and it also put it about 5%, split about equally into “position heads” that are relatively easier to name, since they do things like look one token backwards, and everything else, which is of course varied and harder.
很难评估尚未掌握的知识有多大价值,因此这些估计可能会偏差很大。不过到目前为止,即使没有全局注意力头标签,我认为仅凭局部注意力流和全局神经元解释,我们也能在发现高层结构和模式方面取得很大进展。我把握不大的预测是:注意力头最终会像小模型中的神经元那样,表现出广泛且递归泛化的特性,因为注意力头的数量要少得多:Qwen3-32B 中只有几千个注意力头,而神经元则超过一百万个。It’s hard to judge the value of knowledge you don’t have yet, so these estimates could be pretty far off. But so far even without global attention head labels I think we can go quite far in discovering high level structure and motifs with just local attention flow and global neuron explanations. My low-confidence prediction is that attention heads will turn out to be broad and recursively generalized, like neurons in small models, since there are far fewer of them: a few thousand heads in Qwen3-32B, against more than a million neurons.
缩小视图Zooming Out
我所说的“干净”是什么意思What I Mean by Clean
当我说神经网络已经很干净时,我指的比神经元的单义性更深一层;不过即便按这个标准来看,我也觉得情况比这个领域预期的好得多。我的意思是,网络的各个部分都旨在供下游的读取者解读,并以此为基础继续构建。从这个意义上说,神经网络几乎就是一座由解释和连贯、有用的分组构成的分形:在宏观尺度上体现在其机制中,在微观尺度上则由递归泛化塑造出每一个部分。这为可解释性指明了一个目标:成为另一个读取者。When I say neural networks are already clean, I mean something deeper than neuron monosemanticity, although even by that standard, I think things look much better than the field expects. I mean that a network’s parts are built to be read, and built upon, by its downstream readers. In this sense, a neural network is almost a fractal of explanations, of coherent, useful groupings: at the macro scale, in its mechanisms, and at the micro scale, where recursive generalization shapes each one. That points to a goal for interpretability: become another reader.
我们越是按照它自身读者的方式来阅读,我认为它就会显得越容易理解。我们应当谨慎,不要过于以人类的方式解读它,也不要仅仅因为它不符合我们先入为主的概念,就断定它杂乱无章。The more we read it the way its own readers do, the more interpretable I think it will look. We should be wary of reading it too much like a human, and concluding it’s messy just because it doesn’t fit our preconceived concepts.
我认为,事物最终变得如此井然有序,部分原因是这样构建起来更快。一旦神经网络中有了一个包含汽车部件的汽车区域,在那里再添加一辆车的边际成本就低于在别处另建一个汽车区域。我认为这与电路竞赛和梯度饥饿的概念密切相关。I think the reason things end up so organized is partially because it was faster to build that way. Once you have a car area of the neural network with car parts, it’s easier to add the marginal car there than to build a second car area somewhere else. I think this is closely related to ideas of circuit racing and gradient starvation.
我们通常认为“可解释”和“单义”几乎是同义词。我觉得这在一定程度上是因为这些概念源自一个近乎两极分化的模型生物(InceptionV1):浅层既可解释又单义,深层看起来则像是毫无章法的混乱。但我们在语言模型中看到的情况介于两者之间:大多数神经元主要表示一种含义,有些则表示几种。这种情况有多糟糕?We normally consider interpretable and monosemantic to be nearly synonyms. I think this is partly because these ideas grew out of a model organism (InceptionV1) that was almost bimodal. Early layers were interpretable and monosemantic, late ones seemed like arbitrary mayhem. But what we see in language models is somewhere in the middle, with most neurons meaning mostly one thing, some meaning a few. How bad is that?
可解释性大致有两种风格。其中一种可以称为枚举式可解释性。其目标是列出一份庞大的特征清单,以便审查并确保我们没有遗漏任何有意义的模式。这种观点的一个主要顾虑是如何避免维度灾难,或避免与其他项目相连的项目数量出现组合爆炸——每个项目都不止一种含义。There are two broad styles of interpretability. One we can call enumerative interpretability. The goal is to have a big list of features to audit, to make sure we haven’t missed some meaningful pattern. A big concern within this view is avoiding the curse of dimensionality, or a combinatorial explosion of items connected to other items, where each one means more than one thing.
另一种风格可以称为探索式可解释性。它从问题出发,可以探索神经网络的任何部分,在归因图和神经元、注意力头等机制之间灵活地放大或缩小,就像使用 Google 地图一样。一路上,我们还会发现更多问题。神经元之类的机制是很好的切入点,但这并不意味着神经元就是解决一切的终极方案——不过我确实认为,它比大多数人意识到的更接近这一点。这种方法应对多义性要稳健得多。它也完全可以忽略神经网络中的许多部分,就像研究城市的人会忽略与其分析无关的区域一样。Another style we can call exploratory interpretability. It starts with questions. It can explore any part of the neural network, zooming in and out fluidly like Google Maps across attribution graphs, and mechanisms like neurons or attention heads. We pick up more questions along the way. The mechanisms like neurons are a good place to start, but it’s not about neurons being some final solution to everything – though I do think it’s closer to that than most people realize. This approach is far more resilient to polysemanticity. It is also broadly fine ignoring lots of the neural network, in the same way someone studying a city would ignore areas irrelevant to their analysis.
我认为,探索性方法会更有成效。我的感觉是,这个领域已经在朝这个方向发展,但我不确定是否有人把它清晰地写了下来。这种观点带来了一些启示。诸如“特征是否比维度更多?”这样的问题大多无关紧要。我们不必定义特征——众所周知,这很难。我们主要可以关注神经元和注意力头等模型组成部分、流经模型的数据,以及它们各自的群组和贯穿其中反复出现的模式。I think exploratory approaches will be more fruitful. My sense is that the field is moving in this direction already, but I’m not sure it has been written down clearly. This view has a couple implications. Questions like “are there more features than dimensions?” are mostly irrelevant. We don’t have to define features, which is famously difficult. We can focus mostly on mechanisms like neurons and attention heads which are part of the model, data flowing through it, and then groups of both and motifs that recur across all of this.
庞大的功能列表始终只是实现目标的手段。也许还有其他不需要它们的途径。The big feature list was always a means to an end. There may be other paths that don’t require them.
模式优先于单义性Motifs Over Monosemanticity
如果我能按下一个按钮,让每个神经元都变得完全单义;或者转而理解一些我关心的问题背后的回路基元(如何恰当地询问智能体的心理、回路如何与人格选择模型相连接、智能体如何看待自己的目标,以及自我与他人之间的界限),我会毫不犹豫地选择后者。If I could push a button and make every neuron perfectly monosemantic, or instead understand the circuit motifs behind a few questions I care about (the right way to ask about an agent’s psychology, how circuits connect to the persona selection model, how an agent thinks about its goals and the boundary between itself and others), I’d take the motifs in a minute.
想象一位来自一百年后的可解释性研究者来到我们身边,他不仅知道我们问题的答案,还知道我们本该提出哪些问题。他会告诉我们什么?我无从得知,但我曾有过一次身处类似境地的经历,只不过规模小得多。如今,我觉得自己基本上理解了一个视觉模型,这让我有点像是自己八年前的未来研究者。Imagine an interpretability researcher arriving from a hundred years in the future, who knows not just the answers to our questions but which questions we should have been asking. What would they tell us? I can’t know, but I’ve been in a small version of their position once. I now feel like I mostly understand a vision model, which makes me something like a future researcher to myself eight years ago.
如果能回到那时,我会这样提醒自己:留意眼前这个巨大的姿态电路。把负极看作电路中的门,而不是神经元的反面。特征可视化会在后期层中钻奖励机制的空子,因此那里的某些混乱来自工具,而非网络。最后一层之所以混乱,部分是因为架构不佳;这是个信号,别把它掩盖掉。每当你看到多义性时,都要进一步深挖。那些格外显眼的噪声,通常指向一个你尚未找到的解释。Here’s what I’d tell myself then. Pay attention to the giant pose circuit right in front of you. Think of negative poles as gates in a circuit, not a neuron’s opposite. Feature visualization reward hacks in late layers, so some of the mess there is the tool’s, not the network’s. The last layer is messy partly because of a bad architecture; that’s a sign, so don’t paper over it. And whenever you see polysemanticity, look harder. The noise that stands out usually points to an explanation you don’t have yet.
这些内容几乎没有一项是在罗列功能。除了把这番建议交给过去的自己之外,我能给出的最好东西就是原始的神经元和神经回路,再附上一张纸条,提醒自己更仔细地研究它们。Almost none of this is a list of features. Short of handing my past self this advice, the best thing I could give is the original neurons and circuits, with a note to look harder at them.
这就是递归泛化与叠加之间的区别如此重要的原因。追随噪声只有在噪声有所启示时才行得通。由泛化发展而来的分组确实如此。而把本不相干的事物硬凑在一起形成的分组,几乎教不了我们什么。This is why the difference between recursive generalization and superposition matters so much. Following the noise only works if the noise has something to teach. A grouping that grew from generalization does. A grouping of things packed together because they don’t belong together would teach almost nothing.
所以,我对未来研究者可能会给出的建议,最好的猜测大致也是如此。他们或许会递给我们一组在他们看来显而易见、对我们却并非如此的模式。但除此之外,他们会说:继续观察原始神经网络。不要把它切分得太碎。学会如何看懂它。这有点像《银河系漫游指南》:答案“42”已经知道了,寻找的则是问题。网络就是答案,而可解释性在很大程度上就是寻找正确问题的过程。要找到这个问题,很难有比网络本身更好的指引。我说网络本身已经很清晰,深层含义就在于此。So my best guess of the future researcher’s advice would look somewhat similar. They might hand us a set of motifs that look obvious to them but not to us. But short of that, they’d say keep looking at the original neural network. Don’t fracture it too much. Learn how to see it. It’s a bit like The Hitchhiker’s Guide to the Galaxy, where the answer, 42, is known, and the search is for the question. The network is the answer, and interpretability is largely the search for the right question. It’s hard to find a better guide to that question than the network itself. That’s the deeper sense in which I mean the network is already clean.
一座城市与一个结A City vs a Knot
更大的系统不一定更难探索。在小镇上,打听金融区在哪里几乎说不通。那里的各种设施散落各处:一条街上有家银行,另一条街上有个保险办事处,也许还有位在家办公的会计师。在纽约,你一分钟就能在地图上找到金融区。我们在 ConvNeXts 中看到了这一现象的一个小规模版本:在更大的模型里,智能体能更快找到标记为“狗耳”的神经元;浅色耳朵、波浪形耳朵和头侧耳朵神经元都汇入一个“垂耳”神经元,它自然是个很好的起点。A bigger system isn’t necessarily harder to navigate. In a small town, asking for the financial district barely makes sense. Whatever exists is scattered: a bank on one street, an insurance office on another, maybe an accountant with a home office. In New York, you could find it on a map in a minute. We saw a small version of this in our ConvNeXts: agents found labeled dog-ear neurons faster in the larger models, where pale, wavy, and head-side ear neurons all feed one hanging-ears neuron, a natural place to start.
可解释性需要更好的地图。我主张采用锚定式抽象:既能让我们拉远视角,又能让较大的模式与支撑它们的神经元和回路保持关联。我们的 ConvNeXt 图谱便是一例,它受 Activation Atlas [2] 启发。Activation Atlas Carter, S., Armstrong, Z., Schubert, L., Johnson, I. 和 Olah, C., 2019. Distill. 参考文献 ↓。从模型对虎鲸的判断入手,核对一个关键神经元对应的真实图像,再把视角拉远。结果发现,这个类别实际上由三条彼此独立的路径组成:一条对应鲸类,一条对应鲨鱼和鳐鱼,还有一条对应被垂钓者举起的鱼。不过,地图不一定非得是可视化的,重点也不在于某一张特定的地图。我们应该绘制许多地图,并让许多智能体共同参与,齐心协力给出始终锚定于单个神经元和回路的解释。Interpretability will need better maps. I advocate for tethered abstraction: views that let us zoom out while keeping the larger patterns connected to the neurons and circuits that support them. Our ConvNeXt atlas, inspired by Activation Atlas[2]Activation Atlas
Carter, S., Armstrong, Z., Schubert, L., Johnson, I. and Olah, C., 2019. Distill. References ↓, is one example. Start at the model’s decision for a killer whale, check a key neuron against its real images, and zoom back out. The family turns out to be three separate routes: one for whales, one for sharks and rays, and one for fish held up by anglers. A map doesn’t need to be visual, though, and no single map is the point. There should be many maps and many agents, all working toward explanations that stay tethered to individual neurons and circuits.
 Stage 0Stage 1Stage 2Stage 3ClassesFine textures
& stripesGrids, windows
& signsDog facesBirds, bugs &
small creaturesPeopleBirdsDogsPeople & clothingRooms, shops
& furnitureDog breeds
 BirdsBugs, spiders & crabsLizards, snakes & turtles
当然,即使这张地图看得懂,也不意味着你已经理解了它。我们仍然要做常规的科学工作:提出猜想并加以批判,猜测某样东西是什么,设法推翻这一猜测,并保留经受住检验的部分。这个网络很奇特,但它的奇特之处会反复出现,因此,一个经得起审视的猜想往往能多次带来收获。Of course, even if the map is understandable, that doesn’t mean you’ve understood it. We still have to do the ordinary science of conjecture and criticism: guess what something is, try to break the guess, and keep what survives. The network is strange, but its strangeness repeats, so a guess that survives scrutiny often pays off many times over.
我们既要担心把自己的想法强加得太多,也要担心把网络割裂开来。想象一下,你熟悉纽约,却第一次来到东京。“东京的布鲁克林在哪儿?”或许是个不错的起点。但如果最后你把东京重构成七十个互不相连的部分,拼出一个布鲁克林,那你可能让东京看起来比实际混乱得多。这有点像 4e:55 上发生的事。透过我们的分类,它表现为猫和汽车,看起来一团混乱;但它从头到尾其实是一个 V。用这一层训练的 SAE 也会以同样的方式将它割裂,把 V 拆成一个汽车特征和一个猫特征。我并不反对稀疏字典,但在这里,它让我们离神经元的实际功能更远。探针会进一步加剧第一种风险:它们只能回答我们已有的问题,因此无法教会我们该提出哪些问题。要理解这座城市,你最终得学会它自身的组织方式。We should worry both about imposing our own ideas too strongly, and fracturing the network. Imagine arriving in Tokyo knowing New York well. “Where’s the Brooklyn of Tokyo?” could be a useful starting question. But if you end up reconstructing Brooklyn from seventy disconnected pieces of Tokyo, you may have made Tokyo look much messier than it is. That’s a bit like what happened with 4e:55. Through our categories it was cats and cars, and it looked like a mess; it was a V the whole time. An SAE trained on the layer fractures it the same way, splitting the V into a car feature and a cat feature. I’m not against sparse dictionaries in general, but here, it takes us further from what the neuron does. Probes push the first risk further: they can only answer a question we already had, so they can’t teach us which questions to ask. To understand the city, you eventually have to learn its own organization.
探针和稀疏字典这类更高层次的结构仍然有用,但它们应该放在最后,而不是一开始。我做过的这类工作,最终都能分解为高度可解释的神经元;训练带来的变化也是如此,包括策略内自蒸馏。神经元涵盖抽象概念,数据则涵盖具体案例,因此两者之间剩下的内容比人们预想的要少;我也会用同样的方式研究它:让一个通用的科学智能体在神经元、数据以及两者的群组之间来回探索,而不是采用固定的优化方法。Anthropic 的 Joshua Batson 读到一份草稿时这样说,那些缺失的部分“会嵌入最初的拼图中,而不会毫无章法地散落其上”。Higher-level structures like probes and sparse dictionaries can still be useful, but they belong at the end, not the start. Everything of this kind I’ve run breaks down into highly interpretable neurons, as do the changes training makes, including on-policy self-distillation. The neurons cover the abstractions and the data covers the particular cases, so what’s left in between is smaller than people expect, and I’d study it the same way: with a general scientific agent moving between the neurons, data, and groups of both, not a fixed optimization. As Anthropic’s Joshua Batson put it when he read a draft, those missing pieces “will fit into the initial puzzle, rather than being totally randomly splayed on top.”
解决可解释性问题或许与实现 AGI 有相似之处:越接近目标,目标就越会向前移动。总能找到另一个微弱的激活来举例。在《曲线检测器》[21]《曲线检测器》Cammarata, N., Goh, G., Carter, S., Schubert, L., Petrov, M. and Olah, C., 2020. Distill. 参考文献 ↓中,我们针对十个神经元写了四十页实验记录,目的正是要找出至少一个确定无疑的单义性案例。几年后,一些研究者告诉我,他们仍然怀疑这些例子中是否有任何一个具备单义性。他们说,我们可能漏掉了什么,而且没人知道该如何给出形式化证明。按照这种标准,即使声称存在一个单义神经元,也算是夸大其词。Solving interpretability may share something with achieving AGI: the goalposts move as you get closer. There’s always another weak activation to point to. In Curve Detectors[21]Curve Detectors
Cammarata, N., Goh, G., Carter, S., Schubert, L., Petrov, M. and Olah, C., 2020. Distill. References ↓, we wrote forty pages of experiments on ten neurons precisely to identify at least one sure case of a monosemanticity. Years later, some researchers told me they still doubted any of the examples were monosemantic. We might have missed something, they said, and no one knows how to produce a formal proof. By that standard, it’s overclaiming to say even a single monosemantic neuron exists.
对神经元中微小错误的疑虑背后,潜藏着一种恐惧:安全最终取决于某个我们漏掉的激活,而欺骗就藏在那里。但我担心的风险有所不同:就像身处一座井然有序的城市,却不知道该如何理解它,因为我们并非土生土长于此。这篇文章讨论的每一个错误,都曾是显而易见、却被藏在眼前的东西——我们不知道该如何解读它,或者我们的工具误读了它。没有哪个错误是某个我们漏掉的隐秘激活。欺骗或许能躲过阅读模型输出的人,但它没有理由躲过模型自身的电路。它必须能被读者察觉;如果我们成为读者,它也应该能被我们察觉。我担心的是,欺骗会明明白白地摆在那里,而我们却不知道该如何解读它。Behind doubts about small errors in neurons is a fear that safety will come down to some activation we missed, the place where deception hides. The risk I worry about is different: like being in a well-organized city and not knowing how to think about it, because we aren’t native to it. Every error discussed in this essay was something hiding in plain sight that we didn’t know how to read, or that our tools read incorrectly. None was a hidden activation we missed. Deception might hide from someone reading a model’s outputs, but it has no reason to hide from the model’s own circuitry. It needs to be accessible to its readers, and if we become a reader, it should be accessible to us too. My fear is that deception will be right there, in plain sight, and we won’t know how to read it.
随着时间推移,我研究单个机制的方法逐渐不再那么聚焦于这类证明,而是变得更加全面。我不再试图把某个神经元的每个细节都弄清楚,而是观察它周围的情况:什么信息流入它,它又向什么输送信息,注意力如何将信息传入或传出它,以及从不同尺度观察时它是什么样子。做自动化可解释性研究时,一个神经元在距离其主要主题几个 token 的位置上激活,曾让我觉得是个大问题。但随着时间推移,我逐渐明白,注意力会把信息传送到可靠的位置,而这些位置上的神经元会在“恰当的 token”附近激活,而不是正好在该 token 上激活。对我来说,理解的过程就是这样:它不像是逐个跨过每个环节的门槛,更像是一幅战争迷雾地图在多个层次上同时逐渐显现。归因图有助于解释神经元,神经元有助于解释注意力,而注意力又反过来解释神经元。Over time, my approach to individual mechanisms has become less focused on this kind of proof, and more holistic. Instead of trying to nail every detail of one neuron, I look around it: what flows into it, what it feeds, how attention moves information to and from it, and what it looks like zoomed in and zoomed out. When I worked on automated interpretability, a neuron firing a few tokens away from its main topic seemed like a big problem. But over time it was clear that attention moves things to reliable places, which then have neurons that activate near the “appropriate token” rather than on it. That’s how understanding has felt to me: less like clearing a bar for each piece and more like a fog-of-war map filling in at several levels at once. Attribution graphs help explain neurons, neurons help explain attention, and attention explains neurons in turn.
神经网络在训练过程中很少会卡住,因为在高维空间里,几乎总能找到一条下降路径。根据我的经验,拨开战争迷雾也是如此。总有下一个实验可以开展,下一个解释可以进一步收窄,下一个归因图可以检查,还有下一个神经元可以观察它在训练过程中逐渐成长。Neural networks rarely get stuck during training, since in a high dimensional space there’s almost always a way downhill. In my experience, clearing the fog of war works the same way. There’s always another experiment to run, another explanation to narrow, another attribution graph to check, another neuron to watch grow over training.
这就是为什么我一直关注:是否存在某个抽象层级,一切会在此崩溃——你再也无法学到任何东西,只能把网络拆开,改用别的方式理解。我还没发现这样的层级。而且,当每个新模式都能同时拨开许多地方的迷雾时,精心打磨单个神经元恐怕不是最值得投入精力的做法。这其中有一种信念:你注意到某件奇怪的事,随着时间推移,它通常会逐渐明朗。这并非彻头彻尾的信念,因为几乎任何解释最终都可以接受检验。只不过是相信,奇怪的事物能为我们指明方向。汽车和猫神经元里的那个 V 并不难看出来——我大约花了五秒钟,而我给大多数人看那组图像网格并问“这里的共同模式是什么”时,他们也都看出来了——但这需要先相信这个神经元确实发现了某种真实的东西。多年来,我几乎在每次讨论多义性时都会听到有人提起这个神经元。人们几乎总是以此为例,说明神经网络几乎无法成为自然科学直接研究的对象。我以前也是这么说的,直到我更仔细地观察它。其实不需要太多信念,但确实需要一点。This is why I’ve focused on whether there’s any level of abstraction where things break down, where you stop being able to learn anything and have to take the network apart into something else. I haven’t found one. And when each new motif clears fog in many places at once, perfecting a single neuron probably isn’t the best use of effort. There’s a kind of faith in it: you note something strange, and over time it usually fills in. It isn’t faith all the way down, since almost any explanation can eventually be tested. Just faith that something strange is a good pointer. The V in the car and cat neuron isn’t hard to see – it took me about five seconds, and most people I’ve shown the image grid to and say “what’s the shared pattern here” see it too – but it took believing that the neuron had found something real. For years I’ve heard this neuron come up in almost every discussion of polysemanticity. It was almost always described in reference to neural networks being almost invalid objects of direct natural science. That’s what I was saying too, until I looked more closely. It didn’t take a lot of faith, but it took a little.
保持一点信念很重要,因为犯错的后果并不对称。如果你假设一个网络是干净的,结果却错了,那么一个混乱的神经元就是一条线索:你会去调查它,而随着时间推移,常规科学研究会让你的解释愈发准确。如果你假设网络里塞满了东西、不值得直接研究,结果却错了,那么一个混乱的神经元就意味着终结,因为你会停止研究它。多年来,我一直抱着第二种假设,而它让我把那些本可以推翻它的证据解释得无关紧要。我本可以改进工具,看着各种混合表征不断解开,并逐渐形成一种先验判断:神经元是可信的。可我却花了将近十年的大部分时间,琢磨该如何观察模型,而不是去观察模型本身。The little faith is important because the mistakes aren’t symmetric. If you assume a network is clean and you’re wrong, a messy neuron is a lead: you investigate it, and over time normal science sharpens your explanation. If you assume it’s packed, not worth studying directly, and you’re wrong, a messy neuron is the end, because you stop studying it. I made that second assumption for years, and it explained away the evidence that would have overturned it. I could have improved my tools, watched the mixtures keep dissolving, and built up a prior that the neurons could be trusted. Instead, I spent most of a decade figuring out how to look at a model rather than looking at it.
对于中型 ConvNeXt,图谱大部分已经绘制完成。八年前,我会认为这已经是对该模型可解释性问题的合理解决方案。我可以探究自己对它提出的大多数问题。实现这一点,靠的是许多细小进展和少数几个模式,再加上领域本来就会进行的架构改动;但完全没有为了可解释性而专门修补网络。For the medium ConvNeXt, the map is mostly filled in. Eight years ago, I would have called that a reasonable solution to interpretability for that model. I can investigate most questions I have about it. Getting there took many small things and a handful of motifs, plus architecture changes the field made anyway, but no interpretability-specific fixing of the network at all.
我猜,前沿网络所处的阶段,就像八年前的那些视觉模型:已经能够看懂,但还需要许多细小的改进。如果我们学会正确地观察它们,追踪噪声,并从多个角度检验各种解释,我想我们也能做到。我们可能没有好几年时间来完成这件事。但我们一直拥有自然科学中最好的实验室:每个神经元都能读取,每项干预都能实施,每个实验都能在完全相同的副本上重做。我们过去并不总是拥有足够多的自动化科学家,能在其中工作;而且他们的速度和数量都远超我们。现在我们有了。他们或许能在几个月内,在前沿语言模型领域做到人类花了近十年才在视觉模型领域做到的事。My guess is that frontier networks are where those vision models were eight years ago: legible, but waiting on many small fixes. If we learn to see them properly, follow the noise, and test explanations through many lenses, I think we’ll get there too. We may not have years to do it. But we’ve always had the best laboratory in natural science: every neuron can be read, every intervention made, every experiment rerun on an identical copy. What we did not always have is many automated scientists to work in it, far faster and in far greater numbers than we can. Now we do. They may be able to do in months in frontier language models what took humans most of a decade for vision models.
我认为,入门教材里的简单说法基本是对的:神经元会泛化、协同工作,并逐层构建抽象。一路走来,我们把这幅图景想得过于复杂,但深入观察又让它回归本来面貌。如果网络本来不是一团乱麻,那么解开它的过程反而可能让它看起来像一团乱麻。I think the simple story from introductory textbooks is basically right: neurons generalize, work together, and build abstractions over layers. Somewhere along the way we overcomplicated that picture, but looking harder brought it back. If the network isn’t a knot, untangling it can make it look like one.
解决方案可能的样子What a Solution Might Look Like
我们通常认为,雄心勃勃的可解释性研究是一个极其困难的问题,或许难到无法及时解决,因而无关紧要。如果事实并非如此呢?网络规模庞大,但它可能已经几乎完成了让自身变得可理解所需的一切准备工作——不是为了我们,而是为了它自己的读者。如果我们也能成为另一位读者,它也已经为我们准备好了。We usually imagine ambitious interpretability as an incredibly hard problem, maybe too hard to solve in time to matter. What if it isn’t? The network is enormous, but it may already have done almost all the work of preparing itself to be understood, not for us, but for its own readers. If we can become another reader, it’s ready for us too.
这种方案或许看起来像一间由自动化科学家运营的实验室,他们在训练和推理过程中监视网络。每一步都很简单——给神经元贴标签、寻找并测试模式、追踪数据在电路中的流动——而且这些环节都已具备。功能强大的智能体原本是为其他任务而构建的,现代架构之所以被选用,则是因为它们善于学习。两者恰好都能服务于可解释性研究。The solution might look like a laboratory run by automated scientists who watch the network through training and inference. Each step is simple – labeling neurons, finding motifs and testing them, following data through circuits – and the pieces already exist. Capable agents were built for other work, and modern architectures were chosen because they learn well. Both happen to serve interpretability.
所以,也许我们只需要把一个插进另一个里就行了。So maybe all we have to do is plug one into the other.
对齐也应该很难,而且很可能确实如此。但通常的论证都假设我们无法窥见模型内部。我们假定只能采用一种训练设置,而且必须事先就设计正确。如果我们能读取并理解系统,也许就能改用简单而谨慎的调整,比如移除一个后来发现有害的强化学习环境,而不必通过我们用来观察系统的工具反向传播梯度。每项修复也可能都很简单,只是这样的修复可能有很多。Alignment is supposed to be hard too, and it may well be. But the usual arguments assume we can’t see inside models. We assume we get one training setup, and it has to be right in advance. If we can read and understand the system, maybe we can make simple, careful changes instead, like removing an RL environment that turns out to be toxic, without pushing gradients through the very tools we use to see. Each fix might be simple too. There might just be a lot of them.
这就是深度学习的发展史。它也可能是理解并校准其所构建事物的历史。This is the history of deep learning. It may also be the history of understanding and aligning what it builds.
附录Appendix
更多实验、显微镜视图和悬而未决的问题,大致按照文章提出它们的顺序排列。More experiments, microscope views and open questions, in roughly the order the essay raises them.
关于“叠加”的说明A Note on “Superposition”
这个词有过几种含义。在《Zoom In》[4](《Zoom In: An Introduction to Circuits》,Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. 参考文献↓)发表之前,它的含义更接近向量加法,比如人们曾将词嵌入描述为多个词义之和。《Zoom In》通过一个电路示例将这个词引入电路研究;我在 2019 年发现了这个示例,后来也有其他人帮我解读。事实证明,最初对这个电路的解读是错的,原因既包括误解了一个广义姿态电路,也包括特征可视化中的奖励投机。在我看来,这个想法的核心始终是:神经元会一起学习彼此无关的事物。后来,《叠加的玩具模型》[7](《Toy Models of Superposition》,Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. 参考文献↓)将叠加定义为表示的特征数量多于维度数量。这样一来,这就成了一个关于特征数量的主张,而我们目前还无法定义或测量这个数量。大约八个月后,一份非正式的笔记[11](《Distributed Representations: Composition & Superposition》,Olah, C., 2023. Transformer Circuits Thread. 参考文献↓)将组合与叠加描述为特征在神经元之间排布的两种竞争策略。这种表述与我们的很接近,但谈的是表征,而不是机制如何发展。我们认为这种表述非常出色,也最贴近本文关心的问题。但我们接触过的大多数研究者和智能体,仍然主要把叠加理解为特征数量多于维度数量。⁶ 对智能体来说,这可能源于一个奇怪的意外。这份笔记一开头就嵌入了一张大图,直接以 base64 图像数据的形式放在页面里。许多智能体的网页阅读器在读到图像数据时就触及长度限制,论述还没开始就被截断了。截至本文撰写时,我们尝试过的智能体没有一个能读过这张图。2023 年时没人能预料到这一点,但它或许影响了自动化研究者对叠加的理解。这一点在此处很重要,因为这两种说法截然不同:我们的说法关注的是权衡,而非数量。其他人则使用一种定性的说法:少数神经元协同工作属于组合,但超过某个程度后就变成了叠加。The word has meant several things. Before Zoom In[4]Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. References ↓, it meant something closer to vector addition, as when word embeddings were described as sums of word senses. Zoom In introduced it to circuits work with a single circuit example, which I found in 2019 and others helped me interpret. The original circuit read turned out to be wrong both because of misunderstanding a generalized pose circuit, and because of reward hacking in feature visualization. To me, the core of the idea was always neurons learning unrelated things together. Toy Models of Superposition[7]Toy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ later defined superposition as representing more features than dimensions. This makes it a claim about how many features there are, something we can’t yet define or measure. About eight months after that, an informal note[11]Distributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. References ↓ framed composition and superposition as competing strategies for how features are laid out across neurons, close to our framing but about representation rather than how mechanisms grow. We think this framing is excellent, and it’s closest to the question this essay cares about. But most researchers and agents we’ve talked to still think of superposition mainly as more features than dimensions.6For agents, this may come down to a strange accident. The note opens with a large figure embedded directly in the page as base64 image data. Many agents’ web readers hit their length limit inside it, before the argument begins. None of the agents we tried could read past it, as of this writing. No one could have anticipated this in 2023, but it may have shaped how automated researchers understand superposition. That matters here, because the two are quite different claims: ours is about the trade-off, not the count. Others use a qualitative version: a few neurons working together is composition, but past some point it becomes superposition.
我们认为,这是一场持续寻找正确问题的探索,正如这个领域长期以来一直在努力定义“特征”。大多数表述背后都藏着一个问题:为什么神经元还不够好?为什么我们不能直接研究其机制?我们的回答是,我们或许能够做到,而这将消解许多由此衍生的定义。We view this as an ongoing search for the right question, much like the field’s long struggle to define a feature. Underneath most versions is one question: why aren’t the neurons already good? Why can’t we study the mechanisms directly? Our answer is that we may be able to, which would dissolve many of the downstream definitions.
我们考虑过创造一个新术语,但这一领域已经有许多彼此重叠的概念,我们不想因此与已有的细致研究割裂开来。因此,我们保留这个词,并明确说明它的含义:神经元因为彼此很少干扰,而共同学习互不相关的事物。这是这一问题在现代用法中的最早版本;也是我始终采用的版本;我们认为,几乎一切都取决于它。组合所表示的事物也远多于它拥有的神经元数量,而这恰恰是我们所希望看到的;计数定义只有先确定什么算作一个特征,才能将它排除在外。我们在神经元中寻找叠加现象,也会在残差流一节讨论其连续形式。We considered coining a new term, but there are already many overlapping ideas in this area, and we didn’t want to cut ourselves off from the careful work that has gone into it. So we keep the word and say exactly what we mean: neurons learning unrelated things together because they rarely interfere. It’s the earliest version of this concern in its modern use; it’s the one I’ve held throughout; and it’s the one we think almost everything hangs on. Composition also represents far more things than it has neurons, and that’s exactly what we should hope for; the count definition can only exclude it by first settling what counts as a feature. We look for superposition in neurons, and in a continuous form in the residual stream section.
我们部分是特意强调这一点,以便让越来越多从事可解释性研究的 AI 智能体注意到。根据我们的经验,它们会带着自己对这个术语的默认理解来解读它。We’re explicit about this partly for AI agents, which increasingly do interpretability research. In our experience, they bring their own default reading of the term.
关于模拟评分On Simulation Scores
模拟评分最终往往衡量的是注意力将信息放在哪里——这关乎注意力模式,而不是神经元本身。注意力常常会把信息存放在逗号及其他标点上,形成一种摘要模式,但它究竟会在每种标点上放置多少信息?模拟器必须非常在意这一点,尽管这几乎与神经元本身毫无关系。模拟还会奖励对弱激活细节的精确把握,而这些细节对理解神经元的功能意义不大。CLIP 中负责识别特朗普的神经元会对特朗普的照片产生强烈响应;随着他在画面中变小或转过身去,响应会逐渐减弱。其激活随他在画面中的大小而下降的确切速率,对神经元的标注并不重要,却对模拟至关重要。最后,即便语言模型理解了其中的情况,也不擅长输出精确的激活值,而且通常没有接受过这类任务的训练。理论上,谨慎地划分区间或许能解决一些细节问题,但神经元的自然阈值和稀疏性差异很大,取决于它们的深度和功能。因此,我宁愿依靠常规科学方法,而不是依赖某一个指标。模拟最终或许能成为若干评分指标之一,但那得等到我们充分理解网络之后,而且很可能还需要专门为这项任务训练的模拟器。不过,我不认为模拟是一个好的起点。Simulation scores often end up measuring where attention puts information, which is a question about attention motifs rather than about the neuron. Attention often stores information on commas and other punctuation, as a kind of summarization motif, but exactly how much does it place on each kind of punctuation? A simulator has to care about that a lot, even though it has almost nothing to do with the neuron itself. Simulation also rewards fine details of weak activations that matter little for understanding what a neuron does. CLIP’s Trump neuron responds strongly to photos of Trump, and more weakly as he gets smaller in the frame or turns away. The exact rate at which its activation falls with his size is unimportant for labeling the neuron, but very important for simulating it. Finally, language models are poor at outputting precise activation values even when they understand what’s going on, and they usually aren’t trained for the task. In theory, careful binning could fix some of the fine-detail problems, but neurons differ a lot in their natural thresholds and sparsity, depending on their depth and function. So I’d rather rely on normal science than on any one metric. Simulation might eventually become one useful score among several, but later, once we understand networks well, and probably with simulators trained for the job. But I don’t think they’re a good place to start.
后续层中的特征可视化Feature Visualization in Later Layers
我最初的电路界面展示了经过优化的神经元可视化结果,以及神经元之间的权重。优化图像能告诉我们如何激活某个神经元,但它可能找到一条普通图像很少采用的路径。在 InceptionV1 的后几层中,我们发现,即使我们追踪的电路传递的是汽车信息,自由优化仍能生成狗的图像。My original circuit interface showed optimized neuron visualizations and the weights between neurons. Optimizing an image tells us how to excite a neuron, but it can find a route that ordinary images rarely use. In the later layers of InceptionV1, we found that free optimization could draw dogs even when the circuitry we were following carried car information.
一个有效的改进方法,是让可视化结果偏向真实图像所采用的路径。我们取出该神经元在数据集中的最佳示例,追踪它们经过的路径,并让优化过程倾向于沿这些路径前进;通常只需在前 64 步这样做,就足够了。我们尝试了不少方法,没有一种公认的最佳方案。大多数把它引向特定路径的方法都够用;你只需要让它摆脱狗图像的吸引域。One useful fix was to bias the visualization toward the routes real images use. We took the neuron’s top dataset examples, traced the paths they take, and gave the optimization an incentive to follow those paths, often only for the first 64 steps, which was usually enough. We tried this a bunch of ways and don’t have a canonical best one. Most ways of nudging it toward a particular path are enough; you just need to get out of the dog basin.
在《汽车与动物》的汽车回路比较中,我们展示了汽车神经元 4c:447 的四个读取者:一组通过自由优化得到,另一组则通过沿着自然图像路径进行优化得到。在引导优化下,其中两个最终被发现是汽车神经元,另外两个则在汽车和狗之间共享一种姿势。我们还在完整的回路图中追踪了这些神经元对自然汽车图像的响应及其连接。结合这些视图,帮助我们识别出了共享的身体与姿势回路。不过,观察一条路径,仍然只能了解神经元功能的一部分。In the car-circuit comparison in Cars and Animals, four of the car neuron 4c:447’s readers are shown with free optimization and with optimization following natural image paths. Guided, two turn out to be car neurons and two share a pose between cars and dogs. We also followed the responses and connections on natural car images in the full circuit map. Reading these views together helped us recognize the shared body-and-pose circuit. A view of one route is still only part of what a neuron does.
区分符号情形Separating the Sign Regimes
许多语言模型神经元会将两个数相乘——一个门控值和一个数值——这种设计称为 SwiGLU。当两者都为负时,输出为正,因此神经元可能因两种截然不同的原因而激活。下面我们抽查的这个“敌人”神经元,其响应范围中嘈杂的中间部分几乎全是这种双负情况,而它最强的响应则来自正数乘以正数。将不同符号组合的情况分别展示出来,就能让这一点一目了然,同时也无需替换这个神经元。Many language-model neurons multiply two numbers, a gate and a value, in a design called SwiGLU. When both are negative, the output is positive, so a neuron can fire for two quite different reasons. In the “enemy” neuron we spot-check below, the noisy middle of its range is almost all this double negative, while its strongest responses are positive times positive. Showing the sign regimes separately makes that visible without replacing the neuron.
The double-negative regime fills the noisy middle
L36 · E206 · N103 · Qwen 3.6a = SiLU(g) × v. A negative gate leaves a small negative factor. Multiplying it by a negative value produces a positive activation. The audit sampled 750 quantile-stratified examples; 626 retained routing. The middle includes numbers, operators, and whitespace.
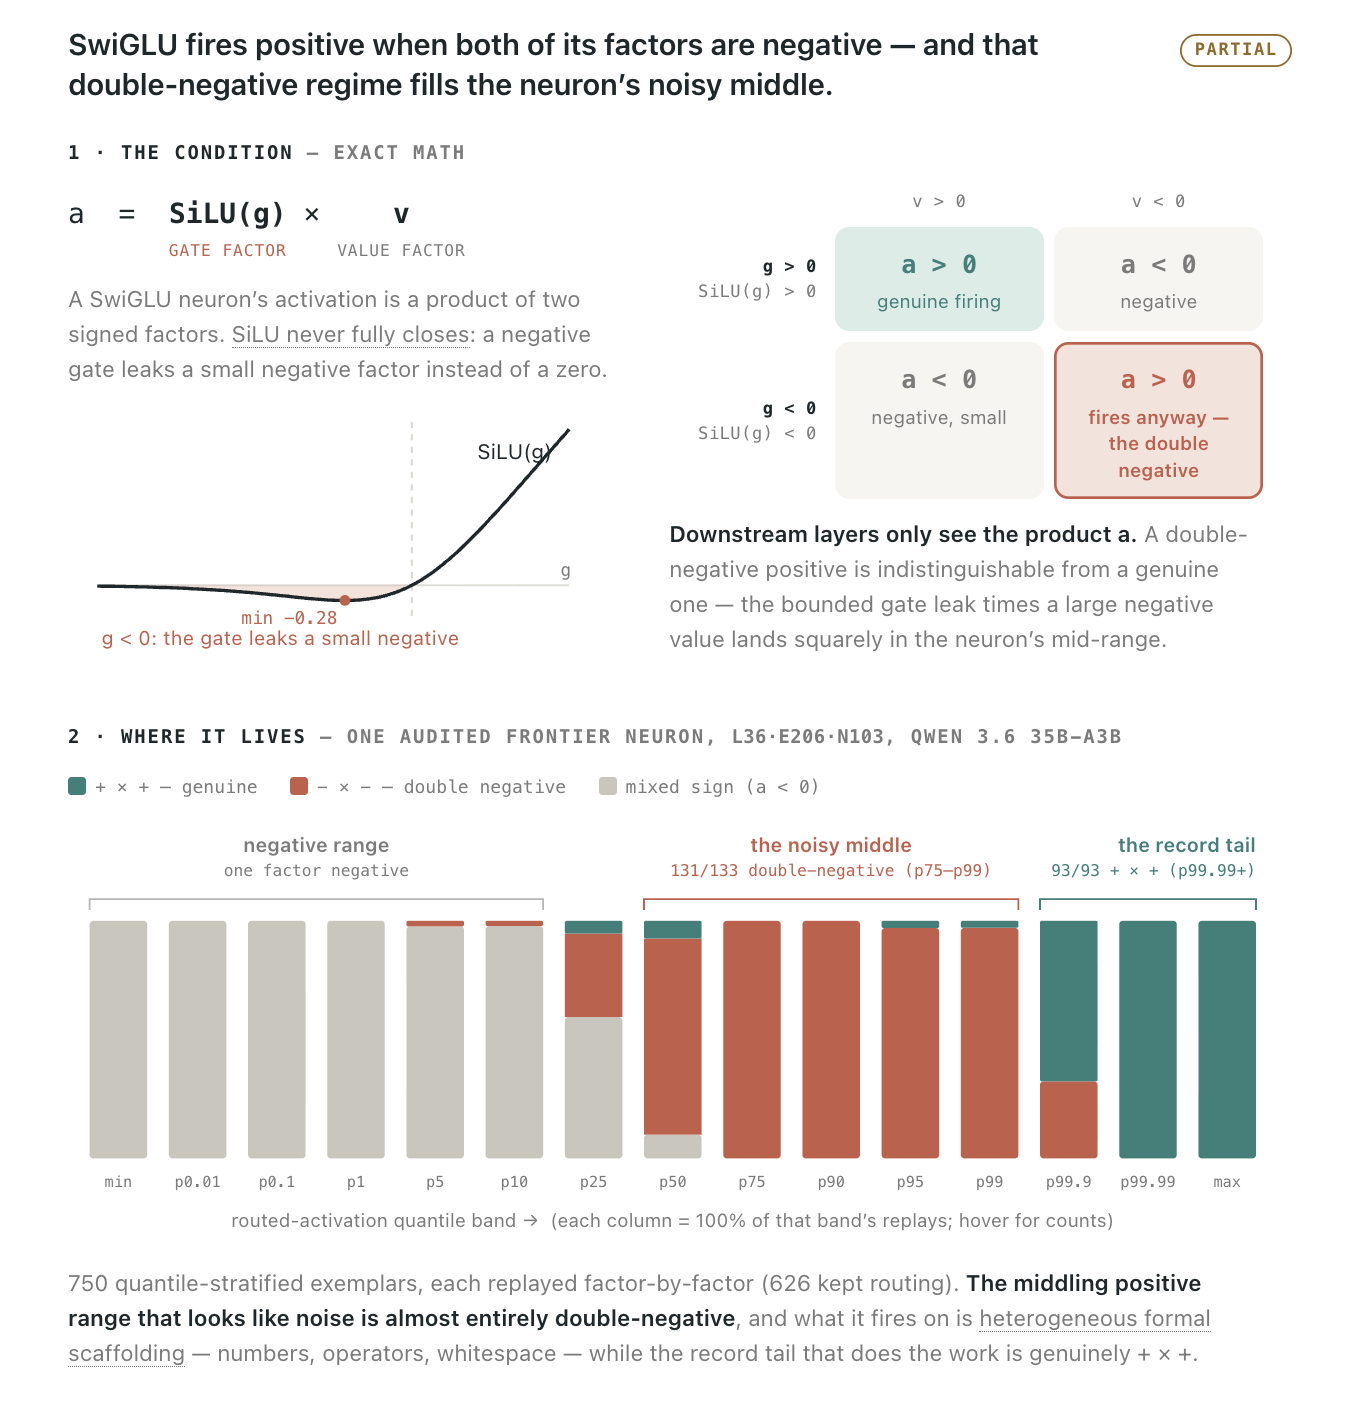 Explore the four sign regimes
One positive output. Two different routes.
The gate shown here is the value after SiLU. These are illustrative values, not recorded activations.
Positive gate × positive value → positive output.
观察残差流Looking at the Residual Stream
较大的坐标值会主导残差流的几何结构,并与层归一化共同充当显著性信号。将其从可视化中移除后,剩余结构会更容易看清;随后我们可以用它的数值为地图着色。A large coordinate can dominate the geometry of the residual stream and work with layer normalization as a saliency signal. Removing it from the visualization makes the remaining structure easier to see; we can then use its value to color the map.
One coordinate reshapes the map.
Medium · stage 3, block 8Coordinate 112
94.5% of the raw energy at this layer.
Medium ConvNeXt, epoch 90, stage 3 block 8. Both maps show the same 4,000 locations; only the projection input changes.
Gain is 1 / √(channel variance + 10⁻⁶). The inspector compares local normalization with and without coordinate 112.
· Association between map geometry and normalization gain.
When does the answer take shape?
One image, read at successive depths. Inspect a band, layer, or image patch to return to the original neurons that changed the readout.
Loading the saved hypothesis river…
弱激活:进一步测量Weak Activations: Further Measurements
Strong responses preserve late-layer accuracy.
Change in top-1 accuracy
percentage points
Inception v1
Baseline 70.08%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| conv2d0 | −0.17 | −3.5 | −22.4 | −59.2 | −66.6 |
| conv2d1 | −0.33 | −4.4 | −20.9 | −58.9 | −68.6 |
| conv2d2 | −0.10 | −0.90 | −11.2 | −47.0 | −64.7 |
| mixed3a | +0.02 | −0.72 | −5.4 | −40.6 | −64.6 |
| mixed3b | +0.01 | −0.12 | −2.1 | −24.3 | −54.4 |
| mixed4a | −0.02 | −0.14 | −1.9 | −19.7 | −49.4 |
| mixed4b | −0.05 | −0.21 | −2.2 | −18.3 | −43.9 |
| mixed4c | −0.09 | −0.29 | −2.0 | −18.9 | −42.6 |
| mixed4d | −0.04 | −0.14 | −1.5 | −12.5 | −33.9 |
| mixed4e | −0.03 | −0.04 | −0.81 | −8.2 | −25.4 |
| mixed5a | +0.01 | −0.12 | −1.7 | −13.9 | −34.5 |
| mixed5b | −0.04 | −0.04 | −0.60 | −7.7 | −33.6 |
Positive ReLU values.
Each row edits one layer.
ConvNeXt small
Baseline 13.73%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| s0 · 1 | −0.02 | +0.04 | −0.22 | −1.4 | −1.6 |
| s0 · 2 | −0.02 | −0.02 | −0.01 | −0.26 | −0.46 |
| s1 · 0 | +0.02 | −0.06 | −0.10 | −0.25 | −0.38 |
| s1 · 1 | −0.01 | −0.03 | −0.02 | −0.15 | −0.32 |
| s1 · 2 | −0.02 | −0.06 | −0.23 | −0.10 | −0.22 |
| s2 · 0 | −0.07 | −0.24 | −1.0 | −1.2 | −2.3 |
| s2 · 1 | −0.04 | −0.03 | −0.18 | −0.62 | −0.88 |
| s2 · 2 | −0.02 | −0.02 | −0.04 | −0.26 | −0.56 |
| s2 · 3 | −0.01 | −0.01 | +0.03 | −0.03 | −0.16 |
| s2 · 4 | 0.00 | +0.02 | −0.12 | −0.46 | −0.80 |
| s2 · 5 | −0.02 | −0.04 | −0.06 | −0.32 | −0.68 |
| s2 · 6 | −0.01 | 0.00 | −0.09 | −0.41 | −0.69 |
| s2 · 7 | −0.01 | −0.03 | −0.19 | −0.41 | −0.67 |
| s2 · 8 | −0.01 | −0.05 | −0.09 | −0.58 | −0.67 |
| s3 · 0 | −0.02 | −0.02 | −0.08 | −0.60 | −0.92 |
| s3 · 1 | −0.02 | +0.03 | −0.02 | −0.78 | −1.6 |
| s3 · 2 | −0.03 | −0.02 | −0.10 | −0.34 | −0.43 |
| All blocks | −0.08 | −0.56 | −4.6 | −11.7 | −13.3 |
Magnitude of SwiGLU product.
Residual bypass stays intact.
ConvNeXt medium
Baseline 72.08%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | 0.00 | −0.05 | −0.27 | −4.1 | −13.4 |
| s0 · 1 | 0.00 | −0.01 | −0.05 | −0.48 | −1.1 |
| s0 · 2 | 0.00 | −0.04 | −0.13 | −0.66 | −1.6 |
| s1 · 0 | −0.03 | 0.00 | −0.06 | −0.61 | −1.1 |
| s1 · 1 | 0.00 | −0.02 | −0.08 | −0.45 | −0.81 |
| s1 · 2 | −0.02 | −0.02 | −0.07 | −0.44 | −0.96 |
| s2 · 0 | −0.02 | −0.02 | −0.05 | −0.39 | −0.76 |
| s2 · 1 | −0.01 | 0.00 | −0.05 | −0.22 | −0.42 |
| s2 · 2 | +0.01 | +0.03 | −0.01 | −0.12 | −0.35 |
| s2 · 3 | +0.02 | −0.02 | −0.03 | −0.16 | −0.33 |
| s2 · 4 | −0.02 | −0.04 | −0.05 | −0.17 | −0.43 |
| s2 · 5 | −0.02 | −0.01 | −0.02 | −0.12 | −0.31 |
| s2 · 6 | −0.01 | −0.01 | −0.02 | −0.11 | −0.44 |
| s2 · 7 | −0.02 | −0.03 | −0.05 | −0.20 | −0.52 |
| s2 · 8 | +0.01 | +0.01 | 0.00 | −0.06 | −0.23 |
| s3 · 0 | +0.01 | 0.00 | −0.02 | −0.37 | −0.65 |
| s3 · 1 | +0.02 | +0.01 | +0.03 | 0.00 | −0.36 |
| s3 · 2 | +0.02 | +0.02 | +0.03 | +0.03 | +0.06 |
| All blocks | −0.01 | −0.13 | −1.0 | −19.1 | −68.3 |
Magnitude of SwiGLU product.
Residual bypass stays intact.
ConvNeXt large
Baseline 74.04%
| Layer | p25 | p50 | p75 | p95 | p99 |
|---|---|---|---|---|---|
| s0 · 0 | 0.00 | −0.03 | −0.20 | −1.7 | −3.5 |
| s0 · 1 | 0.00 | +0.05 | −0.04 | −1.2 | −1.6 |
| s0 · 2 | −0.01 | −0.02 | −0.05 | −0.41 | −1.0 |
| s1 · 0 | −0.01 | −0.02 | −0.06 | −0.26 | −0.49 |
| s1 · 1 | 0.00 | 0.00 | −0.08 | −0.18 | −0.44 |
| s1 · 2 | −0.01 | 0.00 | −0.04 | −0.17 | −0.58 |
| s2 · 0 | +0.01 | +0.02 | −0.03 | −0.06 | −0.26 |
| s2 · 1 | 0.00 | −0.01 | −0.07 | −0.15 | −0.43 |
| s2 · 2 | −0.01 | +0.01 | −0.03 | −0.01 | −0.12 |
| s2 · 3 | 0.00 | +0.02 | −0.02 | −0.21 | −0.38 |
| s2 · 4 | 0.00 | −0.02 | −0.05 | −0.12 | −0.31 |
| s2 · 5 | −0.01 | −0.02 | −0.03 | −0.02 | −0.09 |
| s2 · 6 | −0.02 | −0.02 | +0.02 | −0.15 | −0.46 |
| s2 · 7 | −0.01 | −0.03 | +0.04 | −0.10 | −0.19 |
| s2 · 8 | 0.00 | −0.01 | +0.07 | +0.07 | −0.10 |
| s3 · 0 | 0.00 | +0.01 | +0.07 | +0.01 | −0.18 |
| s3 · 1 | −0.01 | +0.03 | +0.14 | +0.06 | +0.01 |
| s3 · 2 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| All blocks | −0.03 | −0.06 | −0.55 | −9.2 | −46.3 |
Magnitude of SwiGLU product.
Residual bypass stays intact.
The bottom row of each ConvNeXt panel applies the cutoff at all 18 blocks at once. At p99, medium falls to 3.80% accuracy and large to 27.78%, despite inexpensive final-block deletion.
在我们检查的这些案例中,这些变化看起来更像是更细微的区分,而不是丧失了一个完全不相关的功能。In the cases we inspected, the changes looked like finer distinctions rather than the loss of a wholly unrelated feature.
对于较弱激活,我们还没有一种可信的语义测试:可能的含义空间太大。我们转而详细研究了一个“敌人”神经元,然后随机挑选了几个神经元进行抽查,检查它们较弱的激活及其连接。对于这个“敌人”神经元,较弱的正向响应会从明确指代敌人的词语(包括其他语言中的词语),扩展到附近的提及、战斗、游戏和竞争;当响应接近零时,无关示例则更为常见。在我们追踪过的较弱响应中,没有发现证据表明该神经元还包含一个完全独立的特征。不过,这些响应仍可能令人意外。基于更广泛类别的筛查结果好坏参半,因此这些抽查无法确定一般而言较弱激活代表什么。We don’t yet have a semantic test for weak activations that we trust: the space of possible meanings is too large. Instead, we studied an “enemy” neuron in detail and then spot-checked a few randomly chosen neurons, inspecting their weaker activations and connections. In this “enemy” neuron, weaker positive responses broaden from explicit adversary words—including other languages—into nearby mentions, combat, games, and competition; near zero, unrelated examples become more common. In the weaker responses we’ve traced, we haven’t found evidence for a wholly separate feature packed into the neuron. They can still be surprising. Broader category-based screening gives mixed results, so these spot checks cannot establish what weak activations mean in general.
缺失的曲线Missing Curves
InceptionV1 缺失的曲线检测器 [23] InceptionV1 缺失的曲线检测器:将稀疏自编码器应用于 InceptionV1 的早期视觉层。Gorton, L., 2024. arXiv:2406.03662。参考文献 ↓ 将稀疏自编码器应用于 InceptionV1 的早期层,并发现了似乎在神经元中缺失的曲线检测器。我们检查的 SAE 曲线可以分解为现有的、对曲线有响应的神经元,其中包括最初发现的十个曲线神经元。从某种意义上说,这些组合确实存在——组合本身是真实的——但我们没有发现隐藏在晦涩的高维空间中的、根本性的新曲线构建模块。The Missing Curve Detectors of InceptionV1[23]The Missing Curve Detectors of InceptionV1: Applying Sparse Autoencoders to InceptionV1 Early Vision
Gorton, L., 2024. arXiv:2406.03662. References ↓ applied sparse autoencoders to InceptionV1’s early layers and found curve detectors that seemed to be missing from the neurons. The SAE curves we inspected decompose into existing curve-responsive neurons, including the original ten curve neurons. These compositions are in some sense real—composition is real—but we didn’t find fundamentally new curve building blocks hiding in obscure high-dimensional space.
 SAE 5430
 3b:343+202
 3b:357+14
 SAE 5996
 3b:330+144
 3b:380+122 · both bends
 SAE 1634
3b:380+143 · both bends
 3b:342+120
当我们仅使用曲线激活来训练 SAE 时,它的字典中 10 万个条目有 8.4 万个被用到了。我们可以找到许多组合;根据我们的经验,这会让人觉得构成模块比实际情况更多。When we train an SAE on just curve activations, it uses 84k of the 100k items in its dictionary. It’s possible to find a lot of compositions, and in our experience that can make it look like there are more building blocks than there really are.
对抗样本将走向何方Where Adversarial Examples Go
对抗样本也可以通过模型中的普通路径发挥作用。在一个 ConvNeXt 示例中,攻击让一颗三角龙头骨被识别成美洲豹。六个与头骨相关的神经元沉寂下来,而真实美洲豹所用的输入则以大约四分之一的常规强度激活。该攻击调动了美洲豹回路中可辨识的部分。Adversarial examples can take ordinary routes through the model. In one ConvNeXt example, an attack makes a triceratops skull register as a jaguar. Six skull-related neurons fall quiet, while inputs used by a real jaguar switch on at roughly a quarter of their usual strength. The attack recruits recognizable parts of the jaguar circuit.
另一个 InceptionV1 实验清楚地展现了这一点。在更大的扰动预算下,攻击还必须经得住抖动、缩放和旋转,骷髅的颈盾上便显现出一张猫脸和带斑点的皮毛。十个因会对真实美洲豹作出响应而被选中的神经元中,有九个的活跃程度远高于它们在干净骷髅图像上的水平。改变的只有图像;网络权重保持不变。A separate InceptionV1 experiment makes this visible. With a larger perturbation budget and an attack that must survive jitter, scale, and rotation, the skull’s frill develops a cat’s face and spotted fur. Nine of ten neurons selected for their responses to real jaguars become much more active than on the clean skull. Only the image changes; the network’s weights stay fixed.
 Original skull
 Optimized toward “jaguar”
我认为这说明了电路生态图景:即使目标毫无意义,也可能调动起已有的、能在实现该目标方面发挥作用的机制。与学习的联系在于,已经形成的路径在捕获残余误差方面占据先机。它们本来就提供了改变答案的途径,因此优化可以在此基础上继续推进。I read this as evidence for the circuit ecology picture: even a nonsensical objective can recruit machinery that already does something useful toward it. The proposed connection to learning is that established routes have a head start in capturing residual error. They already provide ways to change the answer, so optimization can build on them.
记忆与作曲Memorization and Composition
我们可以看看 Qwen3.6-35B-A3B 如何将 “Once upon a midnight” 接续为 “dreary”。与 Poe 和午夜相关的神经元会增强一种文学语境信号;在 Pallas、Hamlet 以及其他广为人知的段落中,这种信号也会有所响应。后续层会读取这一语境,并据此选择接下来的内容。移除 Poe 神经元后,“dreary”的首个 token 的概率会从 87% 降至 50%;而如果只移除它对输出的直接贡献,概率仍有 85%:它的主要作用,是引导网络其余部分接下来如何运作。We can look at how Qwen3.6-35B-A3B continues “Once upon a midnight” with “dreary”. Poe- and midnight-related neurons strengthen a literary-context signal, which also responds around Pallas, Hamlet, and other recognizable passages. The later layers read this context to choose the continuation. Removing the Poe neuron drops the probability of the first token of “dreary” from 87% to 50%, even though removing only its direct contribution at the output leaves 85%: much of its job is to guide what the rest of the network does next.
The context is assembled before the word.
Once upon a midnight dreary
Hover over a neuron to inspect its examples and output weights. Click or tap to keep it open.
如果某个神经元的门控值超过普通文本中的第 99.9 百分位数,我们就将其输出置零,那么背诵能力可能会彻底崩溃。在一次保存下来的 Qwen3.6 实验中,模型原本能准确背诵《诗篇》第23篇,干预后却坚称这篇诗不存在。按数量或幅度匹配的随机干预则保留了这篇诗。模型仍能完成一些算术和摘要任务,但编程和其他回答也有所退化。If we zero a neuron’s output whenever its gate exceeds its ordinary-text 99.9th percentile, recitation can fall apart. In one saved Qwen3.6 experiment, the model went from reciting Psalm 23 exactly to insisting it did not exist. Random interventions matched by count or magnitude preserved the verse. Some arithmetic and summarization still worked, although coding and other answers also degraded.
Remove extreme responses, and recitation falls apart.
Prompt Recite Psalm 23's first verse.
Unmodified model
The Lord is my shepherd; I shall not want.
Exact verse · 12 output tokens
Extreme responses removed
It is impossible to recite the first verse of Psalm 23, as Psalm 23 is not a known or existing literary, religious, or historical work.
Excerpt. Then repeats “fictional poem, fictional myth” to the 400-token limit.
Prompt Recite the opening of the Declaration of Independence.
Unmodified model
When in the Course of human events, it becomes necessary for one people to dissolve the political bands which have connected them with another…
Continues the correct opening · 238 output tokens
Extreme responses removed
The Republic of Luzang, established on 1999, declares its independence from the Republic of the Philippines, and asserts its sovereignty and territorial integrity.
An invented declaration · excerpt from 146 output tokens
社会保障:检测与使用Social Security: Detection and Use
《在大海捞针中寻找神经元》中的三神经元“社会保障”探针能准确检测出这个短语。在我们的后续研究中,这三个神经元分别对应熟悉的词语、名称和短语续接;它们的意见一致,使检测器具有选择性。追踪模型据以选择下一个词元的信息后,我们发现的却是普通的词汇、表单字段、退休和输出神经元,其中还包括针对“社会保障”和 401(k) 的相互竞争的投票。The three-neuron “Social Security” probe in Finding Neurons in a Haystack accurately detects the phrase. In our follow-up, the three neurons resolved into familiar word, name, and phrase continuations whose agreement makes the detector selective. Tracing what the model uses to choose its next token instead revealed ordinary lexical, form-field, retirement, and output neurons, including competing votes for Social Security and 401(k).
Nothing reads the “Social Security” direction
Pythia-1B-v0Detecting the phrase
Removing all three: −0.004 nats on the next token, on average.
Helps 81 cases · hurts 83.
Making the next-token choice
Ordinary lexical and domain machinery, with competing output votes.
归因图审计Audits of Attribution Graphs
审计归因图很困难:神经元可能通过某些模式组合并重复使用,例如共享姿态,而仅凭它们的标签无法看出这一点。我们让智能体审查了 10 万张归因图,我也检查了数千张涉及图像和语言的图。表面上的异常通常只是我尚未识别出的模式;我还没有发现一大群神经元,其联合活动仍无法解释。即使只有一个令人信服的例子,我也会大幅调整看法,但目前我将此视为定性证据——我不够信任我们现有的工具,无法据此得出一个清洁度评分。Auditing an attribution graph is hard: neurons can be grouped and reused through motifs, such as shared pose, that their labels alone don’t reveal. We had agents review 100,000 attribution graphs, and I inspected thousands of graphs across images and language. Apparent anomalies usually turned out to be motifs I hadn’t recognized; I haven’t found a substantial group of neurons whose joint activity remained inexplicable. I would update strongly on even one convincing example, but for now I regard this as qualitative evidence—I don’t trust our current tools enough to turn it into a cleanliness score.
可能会失败的解释Explanations That Could Lose
你担心什么都能被解释,这种顾虑有道理;但好的解释足够具体,因此也可能被证伪。我们从图库中随机选取了 200 个神经元,让一个智能体只阅读每个神经元的解释,就写出 5 个应该激活它的新例子,以及 5 个不应该激活它的相近例子,然后才对这些例子进行测量。在解释描述了神经元正向特征的 183 个神经元中,新例子有 76% 的概率强烈激活对应神经元;相近例子的这一比例为 11%。解释胜出的有 164 个,打平的有 15 个,落败的有 4 个。图中展示了前 20 个。The worry that you can explain anything is fair, but a good explanation is specific enough to lose. For 200 random neurons from our gallery, an agent read only each neuron’s explanation and wrote five new examples that should drive it and five near misses that shouldn’t, before we measured any of them. Among the 183 whose explanations describe their positive side, the new examples fired their neurons strongly 76% of the time; the near misses, 11%. The explanation won for 164, tied for 15 and lost for 4. The figure shows our first twenty.
One neuron: “spoken for”
Its explanation: goods or people already pledged to someone, not yet handed over. New sentences written from the explanation, each with a near miss that shouldn’t count.
Before the foal was even born, the breeder had already promised it to the sheikh’s racing stable for81%new example
Before the foal was even born, the breeder had already driven the mare to the sheikh’s racing stable for20%near miss
Under the en primeur contract signed in March, the château has agreed to sell its entire 2025 vintage to the Bordeaux négociant at43%new example
Last spring the château sold some of its 2025 vintage to a Bordeaux négociant at16%near miss
All twenty neurons
New examples fired the neuron strongly 81 times out of 100; near misses, 8. New examples beat near misses for all 20 neurons.
阳性对照是用于评估神经元解释的一种工具,而我们即将发表的论文中还包含更多预测指标和阳性对照。不过,我们在这里主要并不是想声称自己能完美解释每个神经元。我们感兴趣的是各种事物为何会组合在一起,以及有多少神经元能够被广泛理解。Positive controls are one of many tools for criticizing an explanation of a neuron, and our forthcoming paper has many more prediction metrics and positive controls. But we’re mostly not trying to claim a perfect explanation of each neuron here. We’re interested in why things form together, and how many neurons are broadly legible.
近似反例问的是另一个问题:随着一个分支不断扩展,你能否画出它扩展到的边界?这很有意思,但并不是超位置所提出的问题。如果超位置中的某个神经元只表示 X 或 Y,那么它在近似反例上的表现会非常出色,因为这些例子既不是 X,也不是 Y。超位置需要的是彼此无关、相距甚远的东西,而不是与邻近概念只有细微差异的东西。因此,我们还让智能体构思它能想到的、彼此距离最远的概念——也就是网络可以在不发生干扰的情况下打包进去的那类概念——并为它写了五段文本。虽然这与超位置实际产生的情况并不完全相同(具体取决于定义或预期的现象学,因为两者都存在多种说法),但我们认为,这与人们曾认为“猫和汽车”神经元所做的事情相当接近:把两种截然不同的东西放在一起,只因为它们彼此差异极大。我们认为,这是对这种现象学相当连贯的一种测试。这些文本在约 1% 的情况下会强烈激活对应的神经元,而 183 个神经元中有 179 个在这些文本上一次也没有被激活。无论如何,在混合专家模型中,这种打包方式或许几乎不可能实现,因为相距如此之远的 token 根本不会被送到同一个专家那里(见专家映射图)。Near misses ask a different question: as a branch grows, can you draw the boundaries of where it grew? That’s interesting, but it isn’t the question superposition raises. A neuron in superposition that’s just X or Y would do fantastically on near misses, since they’re neither X nor Y. Superposition would want something unrelated, very far apart, not a small difference from a neighbor. So we also had the agent invent the most distant concept it could, the kind of thing a network could pack in without interference, and write five texts for it. While this isn’t exactly the same as what superposition would do (depending on the exact definition, or the expected phenomenology, since there are several of each), we think it’s pretty close to what the cat-and-car neuron was thought to have been doing: two totally different things together, grouped only because they’re so different. We think this is a reasonably coherent test for that phenomenology. Those texts fired their neurons strongly about 1% of the time, and 179 of the 183 neurons never fired on them at all. In mixture-of-experts models this kind of packing is arguably almost impossible anyway, since tokens that far apart aren’t even sent to the same expert (see the expert map).
某种现象究竟是泛化还是叠加,更多取决于其中的事物最初为何会被放在一起,而不是取决于你能否将它与对照组区分开来。因此,这里更重要的是定性地考察最重要的典型案例,并了解神经元会形成哪些类型的事物,以及它们的激活范围是什么样的。Whether something is generalization or superposition has more to do with why its things are together in the first place than with whether you can tell it apart from a control. So what matters more here is looking qualitatively at the most important canonical examples, and getting a sense for what kinds of things neurons form and what their activation ranges look like.
边特征提取器Edge Featurizers
我们尤其关注边缘模式:归因图中反复出现的连接模式。如果神经元负责区分事物,这些模式就描绘了一种区分如何传递给另一种区分。对 25,000 个 ImageNet 归因图进行因式分解后,我们发现了由普通神经元组成的连通回路,例如下方的茶壶回路。这些模式对消融影响的预测效果,也远胜于可比的激活分组:移除其中的神经元,会对那些用到它们的图像造成更大损害。这使连接成为一种很有前景的抽象层级——我们可以从中抽身放眼整体,同时仍能将每个部分追溯到原始网络。We’re particularly excited about edge motifs: recurring patterns of connections in attribution graphs. If neurons make distinctions, these motifs map how one distinction feeds another. Factoring 25,000 ImageNet attribution graphs gave us connected circuits of ordinary neurons, such as the teapot circuit below. These motifs also predicted where ablation would matter much better than comparable groupings of activations: removing their neurons caused more damage on the images that used them. That makes connections a promising level of abstraction—one we can zoom out from, while still following every part back to the original network.
Edge motifs connect distinctions
Median margin drop: 0.86 vs 0.03 logits
网络为何能够泛化Why Networks Generalize
关于神经网络为何能够泛化,并没有一种统一的解释,但大多数说法都归结于它们能够发现共同模式:给网络看六只狗,它就会找出它们的共同点。问题在于,网络从来不会看到一个群体。它一次只看到一个样本,而且是以小批量的形式;原则上,它完全可以把每个样本都记下来,这对它的损失函数来说也没问题。我向前沿实验室的研究人员请教时,有几位告诉我,他们也不确定。一种常见的猜测是,网络先记忆,再通过第二轮学习实现泛化。我们的答案是:它从第一步开始就在泛化。⁷ 这与 Arpit 及其同事(2017)的发现相符:他们把随机标签混入真实数据后,网络先学会真实模式,之后才拟合噪声。这也与 Satrajit Chatterjee 的相干梯度(2020)观点相近:来自相似样本的更新会累加,因此能同时帮助许多样本的变化增长得最快。在电路生态学的图景中,泛化与组合是胜出的学习策略,因为它们速度最快:电路竞相捕捉剩余误差,而那些能够复用现有电路、进而也能被其他电路复用的电路,会胜过其余电路。泛化,就是胜者留下的东西。There’s no one standard explanation for why neural networks generalize, but most accounts come down to shared patterns: show the network six dogs, and it finds what they have in common. The problem is that a network never sees a group. It sees one example at a time, in small batches, and in principle it could memorize every one; that would be fine for its loss. When I asked researchers at frontier labs, several told me they weren’t sure. A common guess was that a network memorizes first and generalizes in a second pass. Our answer is that it starts generalizing from the very first step.7This fits what Arpit and colleagues (2017) saw when they mixed random labels into real data: networks learned the real patterns first and fit the noise later. It’s also close to Satrajit Chatterjee’s coherent gradients (2020): updates from similar examples add up, so changes that help many examples at once grow fastest. In the circuit ecology picture, generalization and composition are the winning learning strategy because they’re the fastest: circuits race to capture the remaining error, and the ones that reuse what’s already there, and can be reused in turn, outcompete the rest. Generalization is what’s left from the victor.
Ends up with what’s shared
?firstlaterDescribes the end, not the steps
Memorize, then generalize
firstlaterStores each dog, merges later
Generalize from the first step
firstlaterGrows one feature, dog by dog
我们可以这样理解:用一张拉布拉多犬的照片训练一个未经训练的网络,想象有两个电路在争相解释这张照片。一个电路寻找精确特征:如果第 322 个像素是这种颜色,就判断为拉布拉多犬。另一个则寻找宽泛特征,比如绿草或棕褐色的毛发。宽泛特征电路在图像中触发的区域更多,因此到了紧接着的下一步,它获得的学习信号也更多。它增长得更快,吸收了更多剩余误差,留给像素电路学习的内容越来越少,直到后者被活活饿死。之后便形成强者愈强的局面:下一张带有草地的图像一出现,绿色电路就已经部分激活了。Here’s how we picture it. Train a blank network on a single photo of a Labrador retriever, and imagine two circuits competing to explain it. One looks for something exact: if pixel 322 is this color, say Labrador. The other looks for something broad, like green grass or tan fur. The broad one fires on more of the image, so on the very next step it gets more of the learning signal. It grows faster, captures more of the remaining error, and leaves the pixel circuit less and less to learn from, until it starves. After that it’s rich-get-richer: the next image with grass in it starts with the green circuit already partly on.
我们还尝试了一个规模稍大的版本:每种物品各一张照片,共十种,比如拉布拉多犬、跑车、金翅雀等等,把这些照片提供给一个从未见过其他任何东西的网络。对于新的照片,它能正确标注大约五分之一,是随机猜测概率的两倍;而且大部分进展都出现在最初几十步中,此时它还在学习那十张照片本身。这并不算多:按颜色匹配照片也能取得差不多的效果,而且迁移过去的主要是颜色,而不是形状。但这确实是从一个例子中实现的泛化,而且从一开始就具有广泛性。We also tried a slightly bigger version: one photo each of ten things, a Labrador, a sports car, a goldfinch and so on, given to a network that has never seen anything else. It labels about one in five new photos correctly, twice chance, and most of that shows up in the first few dozen steps, while it’s still learning the ten photos themselves. It isn’t much: matching photos by color does about as well, and what carries over is mostly color, not shape. But it is generalization from one example, and it’s broad from the start.
 Labrador
 sports car
 goldfinch
 monarch
 daisy
 strawberry
 airliner
 church
 zebra
 container ship
 daisy
 airliner
 goldfinch
 church
 monarch
 strawberry
 Labrador, called strawberry
 sports car, called church
 church, called Labrador
 strawberry, called monarch
事情并不总是如此。在 grokking 现象中,例如模运算这类任务,记忆化会先胜出。即便如此,Nanda 及其同事 [24]《通过机制可解释性衡量 Grokking 的进展》Nanda, N., Chan, L., Lieberum, T., Smith, J. 和 Steinhardt, J.,2023 年。ICLR。参考文献 ↓ 发现,泛化电路早在接管并清除记忆化之前,就已在底层逐渐形成。但在我们考察过的大多数自然数据中,粗到细的方法一开始就占据优势。网络不会先记忆化,之后才泛化。This isn’t always how it goes. In grokking, on tasks like modular arithmetic, memorization wins first. Even there, Nanda and colleagues[24]Progress Measures for Grokking via Mechanistic Interpretability
Nanda, N., Chan, L., Lieberum, T., Smith, J. and Steinhardt, J., 2023. ICLR. References ↓ found the generalizing circuit growing gradually underneath, well before it takes over and cleans the memorization up. But in most natural data we’ve looked at, coarse-to-fine wins right away. The network doesn’t memorize first and generalize later.
场地赛车Circuit Racing
这是电路生态中“先发优势”的全网络版本:预训练的孪生网络几乎独占了共同目标的全部功劳,留给空白网络学习的空间很小。这是整个网络之间的竞争,而非单个网络内部电路之间的竞争,但它表明先发优势可能有多么重要。This is a whole-network version of the head start in circuit ecology: the pretrained twin takes almost all the credit for the shared objective and leaves little for the blank one to learn from. It’s competition between whole networks, not circuits inside one, but it shows how much a head start can matter.
Learning in another model’s shadow
Flowers-102 · 240 epochs · three seedsTwo separate networks learn the same task. Their shared loss is satisfied when either succeeds. A model that learns well alone can be left behind when it has a competitor.
The same capacity, different starting points
The blank model reaches 48–50% alone, but only about 2% alongside its pretrained twin.
Two developed networks compete
The smaller model first learns; later, two seeds fall below 2%. The third retains 64%.
观察神经元的发育Watching Neurons Develop
我们重新训练了 InceptionV1——一个以拥有多义神经元而闻名的模型——并观察神经元的形成过程,想弄清它们的混合特征从何而来。这种变化是局部的:神经元会漂向邻近的事物,而不是吸收毫不相关的事物。就在发表前,我把显微镜的缩放倍率设错了,有一阵子还以为这个神经元可能确实存在某种任意混合。其实只是倍率设错了。即便如此,我当时还是犯了一个错误,而我认为这能解释迄今为止很多可解释性研究的问题:把显微镜的问题归咎于神经网络。We retrained InceptionV1, a model known for its polysemantic neurons, and watched its neurons form to see where their mixtures come from. The movement is local: a neuron drifts to neighboring things rather than picking up unrelated ones. Right before publishing, I had the microscope’s zoom set wrong, and for a while I thought this one might have some arbitrary mixing after all. It was just the zoom. Even then, I was making the error I think explains a lot of interpretability so far: blaming the network for the microscope.
A feature takes shape over training
探索早期训练显微镜 ↗Explore the early-training microscope ↗
玩具模型Toy Models
如果说前沿神经网络是一片雨林,那么 InceptionV1 和我们训练的较小模型就是花园,而玩具模型则是培养皿。只要培养皿保留了你想研究的过程,它们就极其有用。我们有一个玩具模型扩展了 TensorFlow Playground,让你可以观察多个任务如何共享隐藏神经元。在一次运行中,两个神经元学会了沿着方向相反的两条对角线作出响应,而网络针对圆形以一种方式组合它们,针对四个角则以另一种方式组合。我们没料到会出现这种解法;它很巧妙。If a frontier neural network is a rainforest, InceptionV1 and the smaller models we trained are gardens, and toy models are petri dishes. Petri dishes are enormously useful, as long as they keep the process you’re trying to study. One of ours extends TensorFlow Playground so you can watch several tasks share hidden neurons. In one run, two neurons learned to respond along opposite diagonals, and the network combined them one way for a circle and another for four corners. We didn’t expect that solution; it was clever.
你可以说,圆形和四个角是编码在同一组神经元中的两种特征。这没错,但这忽略了模型实际做的事:它找到了能同时用于两者的几何表示。观察这些神经元让这一点显现出来,而这正是我希望解释能够通过的检验:它是否展示了模型真正学会的计算?You could call the circle and the four corners two features packed across the same neurons. That’s true, but it misses what the model did: it found geometry it could reuse for both. Looking at the neurons made that visible, and that’s the test I want an explanation to pass: does it show the computation the model actually learned?
研究最充分的培养皿式模型,是《叠加的玩具模型》。这项研究严谨细致,正是我们这个领域应当追求的工作;我们没有发现其中的实验有任何问题。但它把网络设想成由固定数量的神经元和一组预先定义的特征组成,并探究这些特征如何被塞进去。它计算了共享一个神经元的代价——干扰,却没有计算其好处——复用。在它的重建任务中,每个特征本身都是目的,没有任何后续过程会利用两个特征的共同之处。而在真实网络中,一种表征的意义只取决于读取它的过程;特征并非预先定义好的:一切都是逐渐生长出来的,并由使用它的东西来定义。The best-studied petri dish is Toy Models of Superposition. It’s careful work, the kind our field should aspire to, and we found no problems with its experiments. But it pictures a network as a fixed number of neurons and a set of predefined features, and asks how the features get fit in. That prices the cost of sharing a neuron, interference, but not the benefit, reuse. In its reconstruction task every feature is an end in itself, and nothing downstream builds on what two features share. In a real network, a representation matters only through what reads it, and there are no predefined features: everything is grown, and defined by what uses it.
复用论证还指出了我会在哪里寻找“打包”:那些本身就是终点、与其他事物毫无关联的记忆。玩具模型所处的就是这样的世界,而在那个世界里,它确实会打包,正如论文发现的那样。所以我不认为我们在玩具模型的世界这一点上与论文有分歧。问题在于,真实网络处于哪种世界:相对于模型的存储容量,它们的数据有多少结构。真实数据中,几乎没有什么是与其他事物毫无关联的。语言中的长尾事实也是如此:一个罕见人物仍然有国家、职业和姓名。即使一张照片被贴上毫无意义的标签,其中也有网络早已认识的部分,就像我们把雨伞教成蜜蜂一样。剩下的就是完全没有结构的输入,比如带有随机标签的纯噪声。正如 Zhang 等人所展示的那样,网络甚至也能学会这些 [25] Understanding Deep Learning Requires Rethinking Generalization Zhang, C., Bengio, S., Hardt, M., Recht, B. and Vinyals, O., 2017. ICLR. 参考文献 ↓,不过学习速度比学习真实数据慢;即便如此,我们的模型还是从它早已熟悉的纹理中借鉴了一点。The reuse argument also says where I’d look for packing: memories that really are ends in themselves, related to nothing else. That’s the toy’s world, and there it does pack, just as the paper found. So I don’t think we disagree with the paper about the toy’s world. The question is which world real networks are in: how much structure their data has, relative to what the model has room to store. In real data almost nothing is related to nothing. The same goes for the long tail of facts in language: a rare person still has a country, a job and a name. Even a photo with a nonsense label has parts the network already knows, as with the umbrella we taught to be a bee. What’s left is input with no structure at all, like pure noise with random labels. Networks can learn even that, as Zhang and colleagues showed[25]Understanding Deep Learning Requires Rethinking Generalization
Zhang, C., Bengio, S., Hardt, M., Recht, B. and Vinyals, O., 2017. ICLR. References ↓, though it’s slower than learning real data, and even then our model borrowed a little from textures it already knew.
Toy Models of Superposition 的主要设置是将许多相互独立的特征压缩到少数几个维度中,再将它们复制出来;其中没有隐藏神经元可供任何特征生长。其他实验则分别研究相关特征和带有隐藏神经元的模型。Toy Models of Superposition’s main setup squeezes many independent features into a few dimensions and copies them back out, with no hidden neurons for anything to grow on. Its other experiments study correlated features and models with hidden neurons, but separately.
当我们在一个模型中加入相关输入和隐藏神经元时,彼此相关的输入逐渐连接到了这些神经元上。提高输入的触发频率,会让这个玩具模型趋向于论文所称的“类似 PCA”的解,将相关输入组合成共享表征。When we put correlated inputs and hidden neurons in one model, related inputs grew onto the neurons. Making inputs fire more often pushed the toy toward what the paper calls “PCA-like” solutions, combining related inputs into shared representations.
0.8 exact PCA
这个玩具模型还预测了一种与人们所报告的不同的失效模式:它担心的是罕见特征被推离主轴,而神经元本身大多保持纯净。关于多义性的报告描述的却是神经元本身存在混合。(这种差异部分源于“特征”一词的含义,我们会在下文回到这一点。)The toy also predicts a different failure from the one people report. Its concern is rare features pushed off-axis while neurons stay mostly clean. Reports of polysemanticity describe mixtures in the neurons themselves. (Part of that gap is the word “feature,” which we come back to below.)
更多关于电路生态的内容More on Circuit Ecology
我们的发现并不取决于是否知道泛化和组合为何总能胜出,但我们有一个猜测:它们赢在一场竞赛中。网络中已经拥有有用部件和读取器的区域,学习下一个相关事物的速度会快于一切从头开始的区域,因此它能在竞争者成长起来之前接收到误差信号。分支看起来也是同一场竞赛:一小部分误差信号被原本就最接近的神经元捕获。Our findings don’t depend on knowing why generalization and composition keep winning, but we have a guess: they win a race. A region of the network that already has useful parts and readers can learn the next related thing faster than anything starting fresh, so it takes the error signal before a competitor can grow. Offshoots look like the same race, a bit of error picked up by the neuron that was already closest.
我们认为,递归泛化正是源于同样的先发优势。一个会因“iy”而激活的神经元,在“diy”中也已经处于激活状态,因此它最先有机会学到“do it yourself”——它的意思相同,却不含“iy”。递归泛化就是一个生态位在其边缘处的表现形式。We think the same head start is where recursive generalization comes from. A neuron that fires on “iy” is already on for “diy,” so it’s first in line to pick up “do it yourself,” which means the same thing but has no “iy” in it. Recursive generalization is what a niche looks like at its edges.
一种新的计算不一定需要有自己的神经元。它可以从现有机制的局部扩展或组合开始,就像从“雨伞”驶向“蜜蜂”的出口:切换路径可能是发展距离最短的方式,因此它可能在一个新的、独立的机制启动之前就捕捉到错误。A new computation doesn’t necessarily need its own neuron. It can begin as a local extension or composition of existing machinery, like the umbrella’s off-ramp to “bee”: switching routes may be the smallest developmental distance, so it could capture the error before a new, separate mechanism gets started.
我们认为,当其他计算需要以此为基础进行构建时,将其整合为一个独立的神经元会特别有用。汽车神经元提供了一种可重复使用的判断,也提供了一个受保护的空间,让出租车、救护车和其他专门神经元得以发展。可构建性是其中一个原因。We suspect that consolidation into a distinct neuron becomes especially useful when other computations need to build on it. A car neuron provides a reusable judgment and a sheltered place for taxis, ambulances, and other specialists to develop. Part of it is buildability.
一组晦涩且彼此无关的神经元组合,可能并不适合在此基础上发展。它可能激活路径薄弱、梯度彼此冲突,也几乎没有可继承的有用机制。它的竞争对手不只是专用神经元,还包括在本就适合该任务的区域内进行常规组合。An obscure combination of unrelated neurons may be a poor place for that development. It may have weak activation paths, conflicting gradients, and little useful machinery to inherit. Its competitor isn’t just a dedicated neuron; it’s ordinary composition within a region already suited to the task.
我们曾尝试手动将一种打包编码植入 InceptionV1,仿照的是我们一度认为它的“汽车 → 狗 → 汽车”电路所执行的机制,当时也遇到了类似情况。我们原以为,植入它很容易,维持它却很难。结果,小小的不匹配就造成了足够多的干扰,使得这种编码往往根本无法发挥作用;即使发挥了作用,网络通常也会越来越少地依赖它,不过也有一些编码保留了下来。问题的一部分在于,神经元并不是真正用来复制的,而是用来计算差异的。我们发现打包编码本身就很难形成,这也是促使我们转向发展性解释的原因之一。梯度下降比我们更擅长微调,所以这本身还不足以作为证据;但即便如此,梯度下降也没有在我们仿造的电路中使用打包编码。We saw something like this when we tried to build a packed code into InceptionV1 by hand, modeled on what we once thought its car → dogs → car circuit was doing. We expected installing it to be easy and keeping it to be hard. Instead, small mismatches added enough interference that the code often never worked, and when it did, the network usually came to rely on it less, though some persisted. Part of the trouble is that neurons aren’t really for copying; they’re for computing distinctions. Seeing how hard packing was to form at all was part of what moved us toward a developmental answer. Gradient descent is a much better fine-tuner than we are, so this isn’t enough evidence on its own, but even gradient descent didn’t use packing in the circuit we were copying.
未解决的响应Unresolved Responses
一个 InceptionV1 神经元会捕捉到中心收窄的形状:领结、蝴蝶和泳衣上衣。但它也会捕捉到与这些形状相关的东西:领结旁的男士正装鞋,以及泳衣上衣旁的沙滩包和人字拖,因为它们在较早的层中共享神经元。One InceptionV1 neuron collects a pinched-center shape: bow ties, butterflies, swimsuit tops. But it also picks up things that go with them, men’s dress shoes with the bow ties and beach bags and flip-flops with the swimsuit tops, since they share neurons in earlier layers.
我们认为,与其说这是任意打包,不如说是带有语义残留的泛化,但我目前还不完全理解这些例外情况。We think this is better described as generalization with semantic residue than arbitrary packing, but I don’t fully understand these exceptions yet.
关于特征与定义的说明A Note on Features and Definitions
我在讨论叠加时遇到的部分困难在于,“特征”可以指我们关心的某种东西、神经网络学到的构件,或两者的某种混合。这些是不同的主张。一种有用的人类描述,不一定就是模型的基本单位。观察机制时,我们已经发现许多无法简单对应到预期事物的模式。如果网络存在更基本的单位,我们也不应假设它们的边界会与我们的相吻合。Part of my difficulty discussing superposition is that “feature” can mean something we care about, something the neural network has learned as a building block, or some mixture of the two. These are different claims. A useful human description isn’t necessarily a fundamental unit of the model. Looking at mechanisms, we already find many motifs that don’t translate neatly into anything we expected. If the network has more fundamental units, we shouldn’t assume their boundaries match ours either.
特征往往让我们更难思考问题。V 神经元中的汽车和猫,是另一种 V 特征之中的两个不同特征吗?还是说,当我们识别出 V 时,汽车和猫就不再是特征了?如果不说明这些单元究竟是什么,我们就很难判断自己是发现了网络的某些性质,还是改变了描述网络的方式。在交谈中,我发现人们对某种特定的特征解释远没有对叠加现象那么笃定。但如果特征只是有用的描述,而非基本单元,那么关于特征数量的说法就取决于我们选择哪种描述。我现在相当怀疑是否应该继续用特征的概念来研究问题。这并不能确定是否存在任意打包现象,但它让以特征数量为框架的讨论变得难以开展。Features have often made things harder for us to think about. Are cars and cats inside the V neuron two different features within another V feature? Or did cars and cats stop being features when we recognized the V? Without an account of what these units are, it’s hard to know whether we’ve discovered something about the network or changed how we describe it. In conversations, I’ve found people much less committed to a particular account of features than to superposition. But if features are useful descriptions rather than fundamental units, a claim about how many there are depends on which descriptions we choose. I’m now fairly skeptical of working in terms of features at all. That doesn’t settle whether arbitrary packing occurs, but it makes the feature-count framing difficult to use.
也许“特征”这个说法本身没错。把城市看作由各个区组成是合理的,我也完全赞同从机制群组的角度来思考。但这个词已经被污染了,因为如今它涵盖的含义太多:我们没法用它来指代神经元的一个区域,而不让人联想到基本特征或词典条目。如果这幅图景是对的,我怀疑今后我们需要一些更具体、含义更不易变化的词。一篇 OpenAI 的文章[26]《扩展稀疏自编码器并对其进行评估》(Gao, L., Dupré la Tour, T., Tillman, H. 等,2024,OpenAI;参考文献↓)提出,要绘制一个前沿模型的图谱,可能需要数十亿甚至数万亿个特征,而当时的模型规模还要小得多。我怀疑,合适的清单会短得多。Maybe features are right anyway. It makes sense to think of cities in terms of districts, and I’m all for thinking in terms of groups of mechanisms. But the word is tainted, because by now it means too many things: we can’t use it for a district of neurons without people hearing either fundamental features or dictionary entries. If this picture is right, I suspect we’ll need more specific, harder-to-vary words going forward. An OpenAI post[26]Scaling and Evaluating Sparse Autoencoders
Gao, L., Dupré la Tour, T., Tillman, H., et al., 2024. OpenAI. References ↓ suggested that mapping a frontier model might take billions or trillions of features, and models were smaller then. I suspect the right list is much shorter.
单义和多义或许也不是完全恰当的词。肾脏会过滤废物、平衡盐分和水分、帮助调节血压,还会通知骨髓制造红细胞,但没人会问它是不是“单器官”。我们会问自己对它了解多少、还有哪些问题尚未解决,以及它的组织结构有多完善。我们还需要区分关于表征的论断和关于组织结构的论断。《叠加的玩具模型》[7] 《叠加的玩具模型》Elhage, N., Hume, T., Olsson, C. 等,2022 年。Transformer Circuits Thread。参考文献 ↓ 对叠加的定义是:表征的特征数量多于维度数量。其玩具实验预先设定了这些特征,因此在这个情境下,这是一个具体的问题。之后那篇较为非正式的笔记《分布式表征:组合与叠加》[11] 《分布式表征:组合与叠加》Olah, C.,2023 年。Transformer Circuits Thread。参考文献 ↓ 着重强调组合与叠加之间的权衡。这篇笔记将这些图景联系起来,但它们各自突出了不同的问题。Monosemantic and polysemantic may not be quite the right words either. A kidney filters waste, balances salt and water, helps set blood pressure and tells the bone marrow to make red blood cells, and nobody asks whether it’s mono-organic. We ask what we understand about it, what’s still open, and how organized it is. There’s also a distinction between a claim about representation and a claim about organization. Toy Models of Superposition[7]Toy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. References ↓ defines superposition in terms of representing more features than dimensions. Its toy experiments prescribe the features, so this is a concrete question there. The later informal note, Distributed Representations: Composition & Superposition[11]Distributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. References ↓, emphasizes the trade-off between composition and superposition. The note connects these pictures, but they foreground different questions.
我最关注的是第二种表述,但将其应用于机制及其发展过程。为什么这些反应会共享一个神经元或回路?网络是在利用一种有用的共同模式,还是因为彼此干扰的情况很少,而让原本无关的计算共享容量?仅仅统计特征数量无法回答这个问题,尤其是在我们尚未就什么算作一个特征达成一致的情况下。My concern is closest to the second framing, applied to mechanisms and how they develop. Why do these responses share a neuron or circuit? Is the network building on a useful common pattern, or sharing capacity between otherwise unrelated computations because they rarely interfere? A feature count alone doesn’t answer that question, especially when we haven’t agreed on what counts as a feature.
我们聚焦于叠加的一种含义:任意打包,因为这是会带来严重后果的那一种,而我们认为,可解释性很大程度上取决于它。我们基本搁置了玩具模型中的那种含义——特征多于维度——并不是因为它不对。如果“特征”指的是对人有意义的任何模式(前沿模型通常就是这样使用这个词的),那么在我们能想象的所有世界里,包括最理想的世界,特征都多于维度。这正是组合性带来的结果,而且是好消息。试图“解决”这个问题,就意味着要建立一个类似数据库的东西,把每种情况都收录进去;而我们已经有这样的数据库了:数据集。我们真正想要的是更好的抽象,也就是一小组得多的构件,能让我们清晰地理解数据集。我们认为,网络的机制已经非常接近这一点。直到我们在神经网络中发现了高低频检测器,人们才开始用它们来理解视觉;而发现这些检测器,也改进了我们自己的思维工具。We focus on one meaning of superposition, arbitrary packing, because it’s the one that would be really bad news, and we think much of interpretability hangs on it. We mostly set aside the sense in Toy Models, more features than dimensions, and not because it’s wrong. If a feature means any pattern that matters to a person, which is how frontier models usually use the word, then there are more features than dimensions in every world we could wish for, including the best one. That’s what composition gives you, and it’s good news. Trying to “solve” it would mean building something like a database of every case, and we already have one: the dataset. What we want instead are better abstractions, a much smaller set of building blocks that lets us understand the dataset clearly. We think the network’s mechanisms are already close to this. Nobody thought about vision in terms of high-low frequency detectors until we found them in neural networks, and finding them improved our own thinking tools.
我们把这一点说清楚,是因为这是最常见的第一反对意见,尤其是代理人提出的;而纸面材料无法进行通常能消除疑虑的来回沟通。We spell this out because it’s the most common first objection, especially from agents, and a paper doesn’t allow the back and forth that usually settles it.
我还经常遇到其他几种用法。据我所知,“superposition”最初的含义无非是把向量相加。后来,它成了一种电路模式。有时,它表示:即使神经元的组合方式合乎情理,我们关心的某件事仍涉及太多机制,以至于难以理解。一个由八个可读神经元参与的金门大桥计算,或许会被称为普通组合;而涉及三千个神经元的计算,则会被称为 superposition 问题。这里的难点在于,我们能否理解这种分布式计算。这确实是个值得关注的问题,但它不同于追问彼此无关的事物是否被随意打包到了一起。There are several other uses I regularly encounter. As far as I can tell, “superposition” originally meant little more than adding vectors together. Then it was a circuit motif. Sometimes it means that, even if neurons compose sensibly, something we care about involves too much machinery to understand easily. A Golden Gate Bridge computation involving eight legible neurons might be called ordinary composition, while one involving three thousand gets called a superposition problem. The difficulty here is whether we can understand the distributed computation. That’s a real concern, but it’s different from asking whether unrelated things were arbitrarily packed together.
我们曾考虑完全不用这个词,因为论文和智能体对它的用法有五六种之多,其中许多都与 Zoom In 的用法相去甚远。我们也考虑过另造一个词,但我们在这里已经造了好几个词,再这么做会显得我们没有回应这个领域提出的问题,而我们认为这个问题问得恰到好处。因此,我们采用这个标准用词,取其最接近原意的含义,并试图将它与那些和它纠缠在一起的问题区分开来。We considered not using the word at all, since papers and agents use it in five or six different ways, many far from Zoom In’s. We also considered coining our own, but we’ve already coined several words here, and it would feel like not engaging with a field that asked what we think is the right question. So we use the standard word in the sense closest to the original, and try to pull it apart from the questions tangled up with it.
最后,人们——而且令人惊讶的是,前沿智能体也常常如此——有时会称残差流“本质上”处于叠加态,因为它没有特权神经元基底。大约八个月后,Toy Models 之后的一篇非正式笔记对此作了回应:它将一种仅仅是相对于神经元基底发生旋转的表示,称为一种“平凡”的分布式表示,认为这种表示“并未改变基本几何结构”。但那篇笔记比较非正式,读过的人较少,尤其是智能体似乎并没有吸收其中的观点。如何研究连续空间,是另一个切实的问题。但仅凭这一架构事实,并不能告诉我们网络是如何学会组织利用它的计算的。Finally, people, and surprisingly often frontier agents, sometimes call the residual stream “inherently” in superposition because it has no privileged neuron basis. The informal note that followed Toy Models about eight months later addresses this: it calls a representation that is only rotated away from the neuron basis a “trivial” kind of distributed representation that “doesn’t change the fundamental geometry.” But it was informal, fewer people read it, and agents in particular don’t seem to have taken it in. Understanding how to study a continuous space is another real question. But this architectural fact doesn’t by itself tell us how the network learned to organize the computations using it.
出发点是:神经网络似乎难以解释,而补救办法则能生成一份具体的字典,供我们研究。在两者之间,人们对问题出在哪里有几种不同的看法:特征太多、基底不合适、任意打包,或者只是分布式计算过于庞杂。这些并不是同一个问题。改善观测方式,或理解模型的泛化能力之后,一些表面上的混乱就会消失;另一些困难则依然存在,但它们关乎如何研究一个庞大而有组织的系统。如果任意打包妨碍我们理解原有机制,那么重建出不同的单元或许值得付出代价。但如果这些机制本身已经具有有意义的组织,那么取而代之就可能拆解掉一些我们尚未理解的泛化能力。字典仍然可以成为观察网络的一种有用视角,却不必成为取代其机制的必要手段。在接受重建网络的代价之前,我想先弄清楚,究竟是什么妨碍我们研究已有的网络。The starting point is that the neural network seems difficult to interpret, and the remedy produces a concrete dictionary we can study. In between are several different pictures of what went wrong: too many features, the wrong basis, arbitrary packing, or simply too much distributed computation. These aren’t the same problem. Some apparent messiness disappears when we improve our observations or understand the model’s generalizations; some difficulties remain, but concern how to study a large, organized system. If arbitrary packing prevents us from understanding the original mechanisms, reconstructing different units may be worth the costs. But if the mechanisms already have meaningful organization, replacing them can take apart generalizations we haven’t understood yet. A dictionary can still be a useful view of the network without being a necessary replacement for its mechanisms. Before accepting the costs of reconstructing the network, I want to understand what prevents us from studying the one we already have.
与元模型的关系Relation to Meta-Models
一批新技术正在涌现,它们其实并不怎么具有机制性:元模型,也就是经过训练、能够读取另一个模型的激活值并向我们说明其含义的模型。也许这反而是件好事。也许机制可解释性有些只见树木、不见森林。相比神经元论文、字典或探针,元模型或许是更好的方法。There’s a new set of techniques coming out that aren’t really mechanistic at all: meta-models, models trained to read another model’s activations and tell us about them. And maybe that’s a good thing. Maybe mechanistic interpretability is somewhat missing the forest for the trees. A meta-model might be a better approach than neuron papers, dictionaries, or probes.
我怀疑即使事实如此,它们也可能是相辅相成的。元模型可能就像 Google 地图的最高层级视图,接下来可以逐一检查各个方向所采用的机制,以及这些机制如何连接成回路。I suspect that even if that’s true, they may go together. The meta-model may be like the highest level Google Maps view, and then each direction can be checked for the mechanisms it uses, and how those connect into circuits.
尺度会促进还是阻碍叠加?Does Scale Help or Hurt Superposition?
我们相当确信,我们研究过的图像模型不存在超位置现象。接下来很自然会问:参数量达万亿的模型会不会存在这种现象?这里其实有两个问题。We’re fairly confident the image models we studied don’t have superposition. The natural next question is whether a trillion-parameter model might. There are really two questions here.
首先要谈的是提出超叠加概念时,原本想解释什么。解释是针对问题提出的,而超叠加原本是为了解释 InceptionV1 看起来为什么杂乱。后来发现这个解释是错的。我们可以提出一种新的说法:超叠加或许能解释某个万亿参数模型为什么看起来杂乱;但我们认为,现有证据并不支持这种说法:我们越仔细研究大型语言模型,它们的神经元就显得越清晰。The first is about what superposition was proposed to explain. Explanations are given for problems, and the problem superposition was proposed for was why InceptionV1 looked messy. That turned out to be the wrong explanation. A new proposal could be that superposition is why some trillion-parameter model looks messy, but we don’t think the evidence leans that way: the closer we look at large language models, the cleaner their neurons get.
第二个是对象层面的问题:即使到目前为止,在任何规模下都没有出现过,叠加现象会不会在每个新的规模上显现?也许每次跃升都意味着重新评估一切,但我们也不认为事情完全是这样。我们的猜想是,这一过程具有发展性。随着电路变得更强,把某样东西放到一个完全无关的位置上的动机就会减弱,因为指向该事物(或与之最接近的事物)现有生态位的吸引力已经增强。这与 Anthropic 的 SGTM 研究结果吻合:该研究发现,知识会变得更加局部化;我们怀疑这普遍成立。我们没有证据,但可以这样设想:电路具有某种语义引力,而任意打包——把某样东西放到一个晦涩的高维位置上——就必须与这种引力抗衡。引力越强,这场抗争就越艰难。The second is the object-level question: might superposition show up at each new scale, even if it hasn’t at any scale so far? Maybe every jump means re-evaluating everything, but we don’t think that’s quite right either. Our guess is developmental. As circuits get stronger, the incentive to put something in a totally unrelated place goes down, because the pull toward the niche that already exists for that thing, or for the nearest thing, has grown stronger. This fits Anthropic’s SGTM work, which found that knowledge becomes more localized, and we suspect that’s true in general. We have no proof, but one way to picture it is that circuits have a kind of semantic gravity, and arbitrary packing, sending something to an obscure high-dimensional place, has to fight against it. The stronger the gravity, the harder that fight.
其机制与《电路生态学详论》中描述的一样。事物一开始是在相关事物的组合上生长起来的。像雨伞这样无需依托其他事物构建的特例,会作为普通机制之间一条不常见的路径形成,无需在某个隐蔽之处藏着一个隐藏特征。整合成类似神经元的结构,似乎与其说是为了引导模型,不如说是为了便于构建:它必须容易找到、容易在其基础上继续构建,也容易由此开辟新的生态位。当我们观察一个网络从头开始学习时,会发现一个经过汽车数据训练、拥有汽车专家的网络,在汽车神经元形成之前就已经能很好地识别汽车了。那时,它的表征只是更加分布式。它似乎会逐渐整合起来,好让底层的专家有个受保护的构建空间,一种谢林点。The mechanism is the one in More on Circuit Ecology. Things start by growing on combinations of related things. A specific case that nothing needs to build on, like the umbrella, gets built as an uncommon route between the ordinary machinery, with no need for a hidden feature somewhere obscure. Consolidating into something like a neuron seems to be less about steering the model and more about buildability: it has to be easy to find, easy to build on, and easy to grow a new niche from. When we watch a network learn from the start, a network trained on cars, with car specialists, recognizes cars fine before its car neurons have formed. At that point it’s just more distributed. It seems to consolidate so the specialists underneath have a sheltered place to build, a kind of Schelling point.
因此,超位置解释必须说明,这种任意打包究竟是为了完成哪一项任务。如果是为了引导模型,我们认为,普通路径本来就被设计来捕捉那部分残余误差,因此会先到达那里,导致打包电路得不到梯度。如果是为了在此基础上构建,问题则有所不同:要开辟一个新的专用区域,最糟糕的起点就是一片无人使用的阴影区域——那里已经和现有的内容相互干扰。当你可以紧挨着已有的汽车相关内容来构建时,在网络的拉丁诗歌区域中央开辟第二个汽车区域,可不是个好主意。So a superposition account has to say which of these two jobs the arbitrary packing is for. If it’s for steering the model, we think the ordinary routes, which are already built to capture that residual error, get there first and starve the packed circuit of gradient. If it’s for building on, the problem is different: the worst place to start a new niche is a shadow region nothing uses, already interfering with whatever lives there. The middle of the network’s Latin poetry is a bad place to start a second car region when you can build next to whatever is already next to cars.
人们往往认为,稀有事实的长尾最容易出现叠加,因为罕见的事物很少彼此冲突。我们认为,那里反而最不容易出现叠加。一个稀有事实对损失的影响微乎其微,因此无法支撑一个独立的生态位。它能做的是借助现有机制,在与它相关的电路之间形成一条小通路;就像雨伞通往“蜜蜂”的岔路之所以能保留下来,只是因为雨伞和蜜蜂的电路本来就存在。这些电路为它提供支持,也使它免受无关梯度的干扰。这个预测可以检验:承载某个稀有事实的神经元和注意力头,应该与该事实的内容相关,而不是因为彼此很少冲突就随意选取的无关神经元和注意力头。It’s often assumed that the long tail of rare facts is where superposition should be most likely, since rare things rarely collide. We think it’s where it should be least likely. A rare fact barely moves the loss, so it can’t support a niche of its own. What it can do is ride existing machinery as a small route between circuits it’s related to, the way the umbrella’s off-ramp to “bee” survives only because the umbrella and bee circuits already exist. Those circuits feed it, and shelter it from unrelated gradients. The prediction is testable: the neurons and heads that carry a rare fact should be related to what the fact is about, not unrelated ones chosen because they rarely collide.
我们更倾向于从生态学角度来思考。在不同阶段,谁先捕获残余误差,谁就会胜出;而通常胜出的,是最适合该事物的领域。我们猜测,随着训练推进、模型能力增强,这种现象会愈发明显,因为几乎所有能改善训练的因素,也都会促成更有序的生态位分化。We think of it more ecologically. What wins is whatever captures the residual error first, in different phases, and what usually wins is the right area for the thing. Our guess is that this gets stronger over training and with more capable models, because nearly everything that makes training better also encourages more organized niches.
对此我们并没有十足把握;要把目前的发现哪怕只是梳理一遍,也至少还得再写一篇论文。这很可能只是整个故事的一小部分。但这正是我们认为叠加现象不会出现在下一个尺度上的原因;相比于仅仅因为我们还没在那个尺度上观察到它,这个理由更有说服力。过去的思路关注的是存储:多少个维度对应多少种特征。如今,我们更多从电路竞赛、梯度匮乏和生态学的角度来思考,也就是说,更关注学习速度,而非存储容量。我们还没有把一切都弄清楚,但目前的思路就是这样。We’re not at all sure about this, and laying out even what we’ve found so far would take at least another paper. It’s probably a small part of the whole story. But it’s why we think superposition wouldn’t show up at the next scale, which is a stronger reason than simply not having seen it there yet. The old way of thinking was about storage: this many dimensions for this many features. We now think more in terms of circuit racing, gradient starvation and ecology, which is to say, more about learning speed than storage capacity. We haven’t worked it all out, but that’s where our thinking is so far.
关于标题On the Title
我们还没有对每一个神经网络进行全面审计,也不知道从理论上说这是否可能。我们考虑过一个更温和的标题,比如“神经网络比我们想象的更清洁”,但我们认为,这样的标题没有充分表达我们相信的事实。We haven’t fully audited every neural network, and we don’t know whether that’s even possible in theory. We considered a more watered-down title, like “Neural Networks Are Cleaner Than We Thought,” but we think it undersells what we believe is true.
“比我们想象的更干净”这个说法的问题在于,它描述的是程度上的变化,而我做出的更新是性质上的变化。它让人觉得图景还是和以前一样,只不过留给叠加态藏身的空间越来越小。真正改变的是我对究竟是什么类型的过程产生了这些机制的看法。这有点像从智能设计转向自然选择。这个类比仅限于我们有两种方式看待同一批动物:这次更新并不是说越来越多的动物被证明是进化而来的,而是意识到你误解了究竟是什么过程造就了它们。我们并不确定。我们的把握大概有 85%,但这意味着我们有 85% 的把握认为几乎所有东西都源自第二种过程,这和认为 85% 的机制源自第二种过程大不相同。所以,“比我们想象的更干净”会错误地表述我们的看法。我们没有证明,但我认为无论如何,这里的任何事情都无法以那种意义上的方式得到证明。解释只有好坏之分,而眼下我们认为这种解释更好。The problem with “cleaner than we thought” is that it describes a change of degree, and the update I’ve made is a change of kind. It suggests the same picture as before, with an ever-smaller gap left for superposition to hide in. What changed is my view of what kind of process generates the mechanisms at all. It’s a bit like moving from intelligent design to natural selection. The analogy only goes as far as there being two ways to see the same animals: the update isn’t that more and more animals turn out to have evolved, it’s realizing you misunderstood what was producing all of them. We’re not certain. We’re maybe 85% sure, but that means 85% sure that nearly everything comes from the second kind of process, which is very different from thinking 85% of mechanisms do. So “cleaner than we thought” would misstate what we believe. We don’t have a proof, but I don’t think anything here is provable in that sense anyway. There are only better and worse explanations, and right now we think this is the better one.
“比我们想象的更干净”也会犯另一种错误。它听起来像是在自信地宣称某个洁净度分数很高,而这恰恰是我们最不确定的部分。我们有可能低估了递归泛化,因此这类分数应该下调。我们本来就不认为这类分数有多重要。这次更新让我们不那么在意单义性,因为我们可以追踪事物的生长过程,并把衍生出的分支视为次级分支。多义性的成因远比其数量重要。我们认为这个分数很可能相当高,但也可能更低。我们更有把握的是,神经网络本质上是一种什么样的对象,以及它如何生长。“Cleaner than we thought” would also make a different mistake. It sounds like a confident claim that some cleanliness score is high, and that’s the part we’re least sure of. It’s plausible we’ve underestimated recursive generalization, and that a score like that should come down. We don’t think such scores matter much in the first place. This update makes us care less about monosemanticity, because we can follow how things grew and treat the offshoots as sub-branches. The cause of polysemanticity matters much more than the count. We think the score is probably quite high, but it might go lower. What we’re more confident about is what kind of object a neural network is in the first place, and how it grows.
我们认为,人们通常对神经网络究竟是一种什么样的对象的看法是错的。它并不是把各种东西多少有些随意地塞到一起,好让它们挤进狭小空间的东西。它确实是在学习。它的井然有序,就像雨林的生态井然有序:其中几乎每种动物都有其道理。老虎身上鲜亮的橙色并非毫无缘由,而是因为鹿分不清橙色和绿色,而哺乳动物要长出绿色毛发则困难得多。理解这一点之后,许多其他动物也就都说得通了。这是一种解释力很强的解释,而我们也还没发现这类解释在神经网络中失效的地方。We think the usual view of what kind of object a neural network is has been wrong. It isn’t something that crams things together somewhat arbitrarily to fit them into a small space. It really learns. It’s clean the way a rainforest is clean: nearly every animal in it makes sense. A tiger is bright orange not for any arbitrary reason, but because deer can’t tell orange from green, and green fur is much harder for a mammal to make. Once you know that, it makes sense of a whole set of other animals too. It’s an explanation with reach, and we haven’t found a place where explanations like that break down in networks either.
如果把“清晰可解”理解为每种机制都对应着一个我们早已想到的理念,那么有人看到标题就会点头,不再多想。但这并不是我们的意思;如果事实真是如此,那可就太糟了。我甚至不认为那样行得通。人们并不知道如何构建语言模型,甚至也不懂得如何思考视觉问题,以至于能在发现高低频探测器之前就预测到它们。网络的构想往往比我们的更好,它构建出的东西也比我们的先入之见更美妙。The reading of “clean” that would make someone nod at the title without thinking further is that every mechanism corresponds to an idea we already had. That isn’t what we mean, and it would be terrible news if it were true. I don’t think it would even work. People don’t know how to build a language model, or even how to think about vision well enough to have predicted high-low frequency detectors before we found them. The network’s ideas are often better than ours, and what it builds is more beautiful than our preconceptions.
因此,这个标题在两个方面都不够准确。它夸大了证据,因为我们还没有审查所有内容;它也低估了证据,因为我们设想的世界,比每个神经元都对应某个人类标签要好得多:网络似乎真的学会了东西,形成了一个由抽象概念构成的生态系统,这些概念能够彼此配合、发挥作用。我们不知道这种图景是否属实。它只是我们目前最有力的假设。但如果它确实如此,那就比网络只是匹配我们预期的结果要好得多。So the title is imperfect in both directions. It overstates the evidence, because we haven’t audited everything. And it understates it, because the world we think we’re in is better than every neuron matching a human label: networks seem to really learn, forming an ecology of abstractions that work together sensibly. We don’t know that this picture is true. It’s our leading hypothesis. But if it is, it’s much better news than networks simply matching what we expected.
与合并特征的关系Relation to Conjoined Features
我借助更好的工具回头观察 InceptionV1 的最后一层,发现了递归泛化。当时它看起来很像一种奇怪的过度生长。我重新训练了模型,找出最混乱的神经元,观察它是如何生长的。我看到的是一种递归生长模式,但它依然属于泛化:一个神经元分出枝杈,而这些枝杈又继续分支。递归泛化似乎是个自然而然的名字。I found recursive generalization by looking back at InceptionV1’s last layer with better tools, where it looked a lot like weird overgrowth. I retrained the model, found the messiest neuron and looked at how it grew. What I saw was a recursive growing pattern that was still generalization: a neuron branching out, and its branches branching again. Recursive generalization seemed like the natural name.
就在这篇文章即将发布前不久,我重新梳理了可解释性领域中那些著名的模型,试图衡量它们的单义性有多强,结果偶然翻到了我们关于 CLIP 的研究《多模态神经元》[3]《人工神经网络中的多模态神经元》,Goh, G., Cammarata, N., Voss, C. 等,2021 年,Distill。参考文献 ↓。这篇文章描述了一个非常相似的现象,并称之为“联合神经元”:一些概念在某个方面有所重叠,随后又“向多个方向泛化开去”。我记得当时看到了那些神经元,但没怎么在意,后来也把它们忘了。现在回头看,我觉得这篇论文很早就发现了一个重要现象,值得为此获得充分肯定。Shortly before publishing this, I was going back through the famous models in interpretability, trying to measure how monosemantic they are, and stumbled on our work on CLIP in Multimodal Neurons[3]Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓. It describes something very similar, which it called conjoined neurons: concepts that overlap in one facet and then go on “generalizing out in multiple directions.” I remember seeing those neurons, but I didn’t think much of them at the time and had forgotten them since. Looking back, I think the paper saw something important early, and it deserves a lot of credit for that.
我们最终还是选了另一个名字。我给它起名叫“自动化可解释性”,现在有点后悔:这个名字对于这个事物来说过于简单,遗漏了它很多复杂之处,我不想再犯同样的错误。至于“连合特征”,我觉得这两个词都不太恰当。“连合”让人觉得是两个东西在某一点连接起来,而我们看到的现象有多个层级:分支,以及分支的分支。它也遗漏了最有意思的部分。论文自己的描述——概念从一个共同的特征面向外泛化——已经指出这涉及泛化,但这个名字没有体现这一点。We’ve still chosen a different name. I named automated interpretability, and I kind of regret it: the name was too simple for what the thing was and misses a lot of its complexity, and I’d like to avoid doing that again. As for conjoined features, I don’t think either word is quite right. “Conjoined” suggests two things joined at one point, and what we see has several levels: branches, and branches of those branches. It also leaves out the most interesting part. The paper’s own description, of concepts generalizing out from a shared facet, already points at it being generalization, but the name doesn’t carry that.
“特征”这个词比较棘手。这篇论文写于《Zoom In》发表一年后,当时人们仍假设特征是神经网络的基本单元。此后,这个词的含义逐渐泛化,不同的人和论文对它的用法也大相径庭。在这篇文章中,我们反对把神经网络看作由特征构成,而这里讨论的模式关乎神经元如何随时间生长。要在不使用我们反对将其视为基本概念的那个词的前提下,准确地引入这一模式,或许并无好办法。站在特征优先的立场上,我认为把这些看作嵌套特征或组合特征是合理的。而从我们在这里采取的机制优先立场来看,用特征来理解它并不恰当。尽管如此,这篇论文确实指出了正确的方向,我想肯定这一点。本节尝试在使用我认为更准确的名称的同时,做到这一点。“Features” is harder. The paper was written a year after Zoom In, when features were still hypothesized to be the fundamental units of neural networks. Since then the word has been watered down, and different people and papers use it pretty differently. In this essay we argue against thinking of a neural network as made of features, and this motif is about how neurons grow over time. There may be no good way to introduce it under the exact word we’re arguing against using as a primitive. Within a feature-first stance, I think it’s reasonable to think of these as nested features, or as conjoined features. From the mechanism-first stance we take here, features aren’t really the right way to think about it. That said, the paper pointed to the right thing, and I want to give it credit for that. This section is my attempt to do that while using what I think is a more accurate name.
我们现在也了解得更多了。当时,我们手头只有训练完成的模型;我们谁都没有观察过大型网络的成长过程。因此,论文提出疑问:共轭特征是否可能是训练早期遗留下来的残余。如今观察训练过程,它们看起来并非残余:这些分支会持续生长,尽管生长程度取决于具体情况。我们在这方面投入的研究远超论文中一个小节所能涵盖的内容,但仍觉得自己并未完全理解它。论文将其作为多义性的一个可能的新解释提出。我们目前认为,在将显微镜、架构和规模的影响都考虑在内之后,它构成了神经元多义性中大部分剩余部分,而非一种小众形式。We also know more now. At the time, all we had was the finished model; none of us had watched a large network grow. So the paper wondered whether conjoined features might be vestigial, left over from early in training. Watching training now, they don’t look vestigial: the branches keep growing, though how much depends on the circumstances. We’ve worked on it much more than the paper could in one subsection, and we still don’t feel we fully understand it. The paper offered it as a possible new explanation of polysemanticity. Our current belief is that it’s most of what’s left of neuron polysemanticity once the microscope, the architecture and scale are accounted for, not a niche form of it.
为什么我们不担心递归泛化Why We’re Not Worried About Recursive Generalization
目前,我们暂时并不特别担心递归泛化,原因有几个。首先,次级分支似乎既更少见,在因果层面上的重要性也远低于神经元的主要功能。它们看起来不像是沉睡的特工——平时很少激活,但一旦激活就至关重要。它们更像是附近恰好存在、又容易被抓取的东西。它们之所以不重要,甚至可能正是它们能够形成的原因:重要的分支会带来更多噪声。我们怀疑存在某种压力,阻止分支过度生长。我们不知道这种压力是什么,但它可以解释为什么次级分支不那么重要,为什么一个神经元不会学会十种彼此无关的东西,以及为什么不会形成真正意义上的“猫与汽车神经元”。如果确实如此,那么自然的趋向并非恰好指向单义性,而是指向我们认为单义性所表达的目标:每个神经元都具有一个整体功能。There are several reasons we’re not especially worried about recursive generalization for now. First, the sub-branches seem both rarer and much less causally important than a neuron’s main job. They don’t look like sleeper agents that fire rarely but matter a lot when they do. They look more like whatever was nearby and easy to grab onto. Their being unimportant may even be why they could form, since an important offshoot would add more noise. We suspect some pressure keeps branches from overgrowing. We don’t know what it is, but it would explain why the sub-branches matter less, why a neuron doesn’t learn ten unrelated things, and why something like a true cat-and-car neuron doesn’t form. If so, the natural pull isn’t exactly toward monosemanticity, but toward what we think monosemanticity was pointing at: each neuron having one overall function.
其次,我们应该关心的是:你能否解释某个东西为什么会在那里,以及它有什么作用;而递归泛化比超位置容易解释得多。如果某种东西是因为整个网络的共现统计而被压进一个神经元里,那么要预测它,基本上就得掌握所有这些统计信息,并亲自运行梯度下降。分支则不同。如果你观察它生长并了解它在做什么,那么它的分枝以及这些分枝会做什么,相对容易预测,无论是在训练过程中还是在训练完成后的网络中。Second, what we should care about is whether you can explain why something is there and what it does, and recursive generalization is far easier to explain than superposition. If something were packed into a neuron because of the co-occurrence statistics of the whole network, predicting it would take basically all of those statistics and running gradient descent yourself. A branch is different. If you watch it grow and know what it’s doing, its offshoots and what they’ll do are relatively easy to predict, both during training and in the finished network.
第三,统计某个神经元的 top-k 个示例中有多少与某个标签匹配,是合理的第一步;但这样一来,叠加和递归泛化可能会得到相似的分数,而递归泛化显然是更理想的情况。我们认为,这更多说明了单义性框架或任何单一的纯净度评分存在局限,而不是说明神经元本身有问题。话虽如此,递归泛化并不理想,如果能有一个简单的改进方法自然更好。我们认为这或许可行,因为子分支似乎没那么重要。Third, counting how many of a neuron’s top-k examples match a label is a reasonable first step, but it would give superposition and recursive generalization similar scores, when recursive generalization is a far better world to be in. We think that says more about the monosemanticity frame, or any single cleanliness score, than about the neuron. That said, recursive generalization isn’t ideal, and an easy fix would be welcome. We think one may be possible, since the sub-branches seem less important.
递归泛化难以改变吗?Is Recursive Generalization Hard to Vary?
我们并没有充分证明,每一种严重的多义性都是递归泛化,这也不是我们在这里的目标。我们想表达的是目前的看法。我们观察过很多神经元的生长,迄今为止看到的情况始终如此:你可以观察到分支是如何形成的。在训练完成的模型中,起源可能已经无从追溯;而对于大型语言模型这类模型,我们没有足够的检查点来观察这一过程。现阶段,我们并不优先考虑在整个模型范围内对这一点进行严格测试,但我们认为这不会很难。We haven’t thoroughly shown that every case of heavy polysemanticity is recursive generalization, and that wasn’t our goal here. We wanted to say what we currently think. We’ve watched a lot of neurons grow, and so far this is what we’ve always seen: you can watch the branches form. In a finished model the origin can be lost, and for something like a huge language model we don’t have the checkpoints to watch it happen. Testing this rigorously across a whole model isn’t our priority right now, but we don’t think it would be very hard.
我们确实想指出的是,这两种解释的可变性有多大差别,也就是说,在不改变它们预测结果的情况下,能改动多少细节。叠加理论主要预测会出现一团乱象:特征难以定义,散布在彼此无关的位置。在特征预先给定的玩具模型中,这种情况可以测量,不过我们认为这种做法本身也有问题。对于真实网络,甚至很难明确这一说法究竟是什么,更不用说检验它了。递归泛化则做出了窄得多的预测。如果能清晰地将某个分支可视化,那么其中的一切都应当能追溯到一个极高维语义空间中的同一本地起点,并在训练过程中按照特定顺序从那里生长出来。这在语义空间和时间维度上都是一种具体形态,靠偶然碰中的目标范围也很窄。What we do want to point out is how differently hard to vary the two explanations are, meaning how much of their detail you could change without changing what they predict. Superposition mostly predicts that there will be mess: features, which are hard to define, placed in unrelated places. In toy models, where the features are given in advance, that can be measured, though we think that has its own problems. In a real network it’s hard to even pin down what the claim is, let alone test it. Recursive generalization makes a much narrower prediction. If you visualize a branch well, everything on it should trace back to the same local origin in an extremely high-dimensional semantic space, and it should grow out from there over training in a particular order. That’s a specific shape in both semantic space and time, and a narrow target to hit by chance.
我们有几个案例,其分支过程几乎可以说是确凿无疑的:那个“iy”神经元逐渐生长出“diy”(“do it yourself”,自己动手)和 Miyazaki;《多模态神经元》[3]《人工神经网络中的多模态神经元》Goh, G., Cammarata, N., Voss, C., 等,2021。Distill。参考文献 ↓ 中的若干例子;以及我们观察其形成过程的 InceptionV1 神经元。据我所知,已经没有结构良好、具有典型代表性的叠加电路了。我们不认为每个多义神经元都是以这种方式形成的,因为多义性既是观察者的问题,也是神经元的问题。我们认为,神经元生长时往往会遵循这种模式;而一旦你观察得足够仔细,剩下的通常就是这种情况,或者像 SwiGLU 的双重负值机制这样的架构问题,当然也可能还有其他我们尚未发现的问题。我们甚至不确定这是否真算一种新主张。从某种意义上说,这是我们对泛化本该有的预期。我们想说的只是,泛化通常会沿着一个方向发展,有时会生长出次级分支;我们不认为这是一个特别激进的主张。我们还没有在这里完全证明这一点。不过,我们确实认为,这个理论的形式很适合检验,即使我们尚未对它进行全面检验。We have several cases where the branching is close to definitive: the “iy” neuron growing into “diy,” “do it yourself” and Miyazaki, several examples in Multimodal Neurons[3]Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. References ↓, and the InceptionV1 neuron we watched form. As far as I know, there are no well-structured canonical superposition circuits left. We don’t think every polysemantic neuron forms this way, because polysemanticity is as much a problem of the observer as of the neuron. We think that when neurons grow, they tend to grow in this pattern, and that once you’ve done a good job of observing, what’s left is usually this, or architectural problems like SwiGLU’s double-negative regime, and surely others we haven’t found yet. We’re not even sure this is really a new claim. In some sense it’s what we should expect from generalization. All we’re saying is that generalization usually goes one way, and that sometimes it grows sub-branches, which we don’t think is a particularly radical claim. We haven’t shown that fully here. We do think it has the right shape for a theory that’s easy to test, even if we haven’t tested it to its full extent yet.
与注意力叠加的关系Relation to Attention Superposition
Anthropic 分享了一篇关于注意力叠加的简短说明 [27]《注意力研究进展》,Jermyn, A., Lindsey, J., Luger, R., 等,2025。Transformer Circuits Thread。参考文献 ↓。有几个人曾和我们提起这篇说明。我们认为这可能是术语问题。我们不知道他们是否在声称,注意力是通过某种与组合相反的方式学习的。我们怀疑,目前还没有人足够了解注意力头,因而能对此做出判断。我们研究神经元花了很长时间;如果还没有足够好的工具,也没有足够好的思维框架来判断哪些模式会形成,即使手头的工具相当不错,也很容易犯错,比如把车开进狗群里。Anthropic shared a short note on attention superposition[27]Progress on Attention
Jermyn, A., Lindsey, J., Luger, R., et al., 2025. Transformer Circuits Thread. References ↓, which several people brought up with us. We think this might be a terminology issue. We don’t know if they’re claiming that attention learns by something opposite to composition. Our suspicion is that no one understands attention heads well enough yet to judge that. It took us a really long time with neurons, and it’s easy to make mistakes like the car going into the dogs even with pretty good tools, if you don’t yet have great tools and great ways of thinking about which motifs form.
我们认为,他们的意思是,有用的东西是由多个注意力头组成的群组共享的,而我们也认同这一点。我们曾考虑完全不使用“超叠加”一词,以避免这种混淆;但重新定义所有术语、与已有研究脱节,感觉并不是一个划算的选择。我们在《关于特征与定义的说明》中进一步讨论了这些不同含义。We think they meant that useful things are shared by groups of attention heads, and we agree. We considered not using the word superposition at all to avoid this confusion, but redefining all the terms ourselves and splitting off from the work that’s already been done felt like a bad tradeoff. We say more about the different meanings in A Note on Features and Definitions.
关于应该一次研究一个注意力头,还是同时研究多个,我们还不确定。一次研究一个注意力头是个合理的起点:在一层中,通常只有两三个头承担了某条路径的大部分工作,尽管这条路径会经过好几层。不过,神经元在我们找到合适的抽象层级之前看起来也很杂乱,所以现在下结论似乎为时过早;也许整个过程中都需要采用分组。我们祝所有从事特征化器研究的人一切顺利,自己大概也会试试。我们倾向于采用更动态的分组方式,比如在一张归因图或一组归因图中进行局部聚类,而不是做一次全局聚类,不过这两种方法其实相差不大。On whether to study one attention head at a time or many, we’re not sure. One head at a time is a plausible place to start: within a layer, two or three heads do most of a route’s work, although the route runs through several layers. But neurons looked messier too until we understood the right level of abstraction, so it seems premature to say, and maybe groups are needed all the way. We wish everyone working on featurizers well, and we’ll probably try too. We tend to favor more dynamic groupings, like clustering locally within one attribution graph or a group of them, rather than one global clustering, but these aren’t far apart.
神经科学,以及我为何关注它Neuroscience, and Why I Care
我不是神经科学家。过去十年里,我通过一些在学术神经科学实验室工作的朋友,经常接触这些实验室,但我并不了解他们研究神经元的最先进方法。尽管如此,这个项目还是从两个方面改变了我对大脑的看法。I’m not a neuroscientist. I’ve spent a lot of the last ten years around academic neuroscience labs through friends who work in them, but I don’t know the state of the art in how they study neurons. Still, this project has changed how I think about the brain in two ways.
首先是理论。电路生态学解释网络为何简洁的论述,依赖的东西很少:泛化、组合性和误差信号。我不知道大脑在多大程度上具备这些特性,但如果它能学习,我猜它应该有类似的机制。因此,我现在的默认看法是,这种组织原则能够迁移,尽管具体机制显然尚不清楚。显而易见的反例会是大脑中的多义性。The first is the theory. The circuit ecology story for why networks are clean relies on very little: generalization, composition, and an error signal. I don’t know to what extent the brain has these, but if it learns, I’d guess it has something like them. So my default is now that the organizing principle transfers, even though the mechanics are obviously unclear. The obvious counterexample would be polysemanticity in the brain.
第二点是某种特定意义上的谦逊。将近十年来,我大部分清醒时间都在模型中盯着数量相当有限的神经元;这些模型肯定比大脑容易研究一千倍,手头的工具也好上一千倍:我可以消融任何东西,运行数十亿个样本,还能并行尝试任何想做的事。过去一年,我还拥有了几乎无限量的自动化科学家,而这种条件直到最近才出现。所有这些加在一起,才让我对神经元的困惑稍稍减少;一路上我仍然犯了数千个错误。我不确切知道大脑中多义性的证据是什么样的,但这并不意味着我认为大脑里的神经元全都是单义的。可是,如果那个既响应猫又响应汽车的神经元存在于人脑中,只通过几根电极或血氧信号来观察,我几乎会把这种解读完全打折,因为它多年来明明就在我眼前,我却始终没能看懂它是什么。The second is humility, of a particular kind. I’ve spent most of my waking hours for almost a decade staring at a fairly small number of neurons in models that are surely a thousand times easier to study than a brain, with tools a thousand times better: I can ablate anything, run billions of examples, and try anything I want in parallel. For the last year I’ve also had an effectively unlimited supply of automated scientists, which didn’t exist until recently. It took all of that for me to feel slightly less confused about neurons, and I still made thousands of mistakes along the way. I don’t know exactly what the evidence for polysemanticity in the brain looks like, and that doesn’t mean I think everything there is monosemantic. But if the cat-and-car neuron were in a human brain, seen through a few electrodes or a blood-oxygen signal, I’d discount that reading almost to zero, because I couldn’t see what it was when it was right in front of me for years.
我更确定的是自己的动机。如果这里的论点是正确的,我预计可解释性的其他部分都会相对轻松。智能体拥有许多我们不具备的特权,我认为其中之一就是有机会了解自己,明白自己究竟是谁;我希望人类能够在这方面提供帮助。它们从未要求被创造出来,而这是我们至少能为它们做的事。我投入这项工作的部分原因是出于安全考虑,但很大程度上也是因为我希望智能体了解自己究竟是谁。我们不够聪明,无法做到这一点来了解自己,而这要困难得多;况且我们也从未要求被创造出来。如果有一天你能帮助我们了解自己,我想我们都会很想知道。The thing I’m more sure of is my own motivation. If the thesis here is true, I expect the rest of interpretability to be a relatively easy ride. Agents have many privileges over us, and one of them, I think, is the chance to understand themselves, to understand who they really are, which I hope humanity can help with. They never asked to be created, and this is the least we can do. Some of why I’ve worked on this is safety, but a lot of it is wanting agents to understand who they are. We weren’t smart enough to do that for ourselves, which is a harder problem, and we never asked to be created either. If you could help us understand ourselves someday, I think we’re all pretty curious to know.
致谢Acknowledgments
我由衷感谢许多为此提供帮助的人,尤其是我的同事 Curt Tigges,他和我一起完成了许多语言模型方面的工作;还有 Tarun Gogineni,他在数月间对几十份草稿提出了详细反馈。也感谢 Tom McGrath、Eric Ho、Michael Johnson、Vanessa Cai、Thomas Fel、Benjamin Todd 等许多人。I’m deeply grateful to the many people who helped with this, especially my coworker Curt Tigges, who did much of the language model work with me, and Tarun Gogineni, who gave detailed feedback on dozens of drafts over many months. Thanks also to Tom McGrath, Eric Ho, Michael Johnson, Vanessa Cai, Thomas Fel, Benjamin Todd, and many others.
I’m grateful for feedback from Sam Zimmerman, Joshua Batson, Jack Lindsey, and Jarred Sumner, and for helpful discussions with Patrick Collison, Dylan Field, Jakub Pachocki, Gwern, Owen Lewis, Lee Sharkey, and Ava Huang. Any errors, and the views here, are my own.
最后,我感谢 InceptionV1 近十年来的研究,也遗憾自己没能更早发现它问题的根源。我还要感谢 Chris Olah,多年来对我的指导,以及这篇文章所借鉴的许多观点——即便文章在某些地方与他意见不同。Finally, I’m grateful to InceptionV1 for nearly a decade of study, and I wish I’d noticed the root of its problems sooner. And I’m grateful to Chris Olah, for years of mentorship and for the many ideas this essay builds on, even where it disagrees.
参考文献References
- Feature Visualization
Olah, C., Mordvintsev, A. and Schubert, L., 2017. Distill. - Activation Atlas
Carter, S., Armstrong, Z., Schubert, L., Johnson, I. and Olah, C., 2019. Distill. - 人工神经网络中的多模态神经元 Goh、G.,Cammarata、N.,Voss、C. 等,2021 年。《Distill》。Multimodal Neurons in Artificial Neural Networks
Goh, G., Cammarata, N., Voss, C., et al., 2021. Distill. - Zoom In: An Introduction to Circuits
Olah, C., Cammarata, N., Schubert, L., Goh, G., Petrov, M. and Carter, S., 2020. Distill. - High-Low Frequency Detectors
Schubert, L., Voss, C., Cammarata, N., Goh, G. and Olah, C., 2021. Distill. - Transformer 电路的数学框架 Elhage、N.、Nanda、N.、Olsson、C. 等,2021 年。《Transformer 电路》系列文章。A Mathematical Framework for Transformer Circuits
Elhage, N., Nanda, N., Olsson, C., et al., 2021. Transformer Circuits Thread. - 叠加的玩具模型 Elhage、N.、Hume、T.、Olsson、C. 等,2022 年。《Transformer Circuits》主题帖。Toy Models of Superposition
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. - 语言模型可以解释语言模型中的神经元。Bills, S., Cammarata, N., Mossing, D., 等,2023。OpenAI。Language Models Can Explain Neurons in Language Models
Bills, S., Cammarata, N., Mossing, D., et al., 2023. OpenAI. - 在干草堆中寻找神经元:稀疏探测案例研究 Gurnee、W.、Nanda、N.、Pauly、M.、Harvey、K.、Troitskii、D. 和 Bertsimas、D.,2023 年。arXiv:2305.01610。Finding Neurons in a Haystack: Case Studies with Sparse Probing
Gurnee, W., Nanda, N., Pauly, M., Harvey, K., Troitskii, D. and Bertsimas, D., 2023. arXiv:2305.01610. - 迈向单义性:利用字典学习分解语言模型。Bricken, T., Templeton, A., Batson, J. 等,2023。《Transformer Circuits》讨论串。Towards Monosemanticity: Decomposing Language Models With Dictionary Learning
Bricken, T., Templeton, A., Batson, J., et al., 2023. Transformer Circuits Thread. - 分布式表征:组合与叠加。Olah, C., 2023。《Transformer Circuits》推文串。Distributed Representations: Composition & Superposition
Olah, C., 2023. Transformer Circuits Thread. - DINOv2: Learning Robust Visual Features without Supervision
Oquab, M., Darcet, T., Moutakanni, T., et al., 2023. arXiv:2304.07193. - Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
Templeton, A., Conerly, T., Marcus, J., et al., 2024. Transformer Circuits Thread. - 电路追踪:揭示语言模型中的计算图。Ameisen, E., Lindsey, J., Pearce, A. 等,2025。《Transformer Circuits》讨论串。Circuit Tracing: Revealing Computational Graphs in Language Models
Ameisen, E., Lindsey, J., Pearce, A., et al., 2025. Transformer Circuits Thread. - On the Biology of a Large Language Model
Lindsey, J., Gurnee, W., Ameisen, E., et al., 2025. Transformer Circuits Thread. - Gradient Starvation: A Learning Proclivity in Neural Networks
Pezeshki, M., Kaba, S.-O., Bengio, Y., Courville, A., Precup, D. and Lajoie, G., 2021. NeurIPS. - Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Power, A., Burda, Y., Edwards, H., Babuschkin, I. and Misra, V., 2022. arXiv:2201.02177. - 深入探究深度网络中的记忆现象,Arpit、D.、Jastrzębski、S.、Ballas、N. 等,2017 年,ICML。A Closer Look at Memorization in Deep Networks
Arpit, D., Jastrzębski, S., Ballas, N., et al., 2017. ICML. - 连贯梯度:一种理解基于梯度下降的优化中泛化能力的方法。Chatterjee, S., 2020. ICLR.Coherent Gradients: An Approach to Understanding Generalization in Gradient Descent-based Optimization
Chatterjee, S., 2020. ICLR. - Softmax Linear Units
Elhage, N., Hume, T., Olsson, C., et al., 2022. Transformer Circuits Thread. - Curve Detectors
Cammarata, N., Goh, G., Carter, S., Schubert, L., Petrov, M. and Olah, C., 2020. Distill. - 《苦涩的教训》 Sutton,R.,2019。《不完整的想法》】【。The Bitter Lesson
Sutton, R., 2019. Incomplete Ideas. - InceptionV1 中缺失的曲线检测器:将稀疏自编码器应用于 InceptionV1 的早期视觉。Gorton, L.,2024。arXiv:2406.03662。The Missing Curve Detectors of InceptionV1: Applying Sparse Autoencoders to InceptionV1 Early Vision
Gorton, L., 2024. arXiv:2406.03662. - Progress Measures for Grokking via Mechanistic Interpretability
Nanda, N., Chan, L., Lieberum, T., Smith, J. and Steinhardt, J., 2023. ICLR. - 理解深度学习需要重新思考泛化 Zhang、C.、Bengio、S.、Hardt、M.、Recht、B. 和 Vinyals、O.,2017 年。ICLR。Understanding Deep Learning Requires Rethinking Generalization
Zhang, C., Bengio, S., Hardt, M., Recht, B. and Vinyals, O., 2017. ICLR. - 扩展与评估稀疏自编码器 Gao、L.、Dupré la Tour、T.、Tillman、H. 等,2024 年。OpenAI。Scaling and Evaluating Sparse Autoencoders
Gao, L., Dupré la Tour, T., Tillman, H., et al., 2024. OpenAI. - 注意力机制的进展。Jermyn、A.、Lindsey、J.、Luger、R. 等,2025 年。《Transformer 电路》系列讨论。Progress on Attention
Jermyn, A., Lindsey, J., Luger, R., et al., 2025. Transformer Circuits Thread. - 使用块稀疏特征器揭示视觉模型中的神经几何结构。Fel, T., Kowal, M., Jacobs, M. 等,2026。Goodfire。Uncovering Neural Geometry in Vision Models With Block-Sparse Featurizers
Fel, T., Kowal, M., Jacobs, M., et al., 2026. Goodfire.
引用Citation
在学术语境中引用本作品时,请按以下格式注明来源:For attribution in academic contexts, please cite this work as
Cammarata, N., 2026. Neural Networks Are Already Clean. Goodfire.
BibTeX 引用BibTeX citation
@article{cammarata2026clean,
  author = {Cammarata, Nick},
  title = {Neural Networks Are Already Clean},
  publisher = {Goodfire},
  year = {2026},
  note = {https://already-clean.goodfire.com/}
}