Gemini 4 Argon:我们 frontiers 智能时代的下一章
原题Gemini 4 Argon: our next era of frontier intelligence
推荐理由Google DeepMind 发布前沿模型 Gemini 4 Argon:定价 2/10 美元,输出 token 上限从 64K 扩到 100 万,面向复杂长程任务。发布方式同样值得注意:先经 Fairwind 计划开放给受信任的网络防御者,收集护栏反馈后再逐步扩大。Google 内部战果具体:量子子程序优化超过公开基线 40%,智能体群分析全集群画像释放 300 TiB 以上内存,libgav1 的 32K 行 SIMD 重写为安全 Rust 后快 2.7 倍。观察前沿能力与分阶段发布治理的一手窗口。
读前速览
Google 宣布 Gemini 4 Argon,一款输出上限达 100 万 token 的 frontier 模型,在 DeepSWE、Vals Index 和 CWE-bench 上的表现居首,将首先通过 Fairwind Program 提供给值得信赖的网络安全防御者。
Gemini 4 Argon 是一款专为长时程推理而打造的 frontier 模型,目前正在分阶段推出,首先面向值得信赖的网络安全防御者。
它通过 Fairwind Program 提供给一组值得信赖的网络安全防御者,Google 正在参与美国政府的自愿性预发布访问流程,并在更广泛的开发者、企业和消费者可用之前持续完善相关约束机制。
Argon 在 Google 内部已在编码、基础设施和研究领域展现出可衡量的影响。
它在几分钟内就超越了已发布的量子基线 40%,帮助智能体释放超过 300 TiB 的数据中心内存(据估计总节省 500 TiB 至 1 PiB),并用于大规模 C/C++ 至 Rust 的迁移工作,迁移量高达 80 万行以上,其中一个 libgav1 解码器比之前的 Rust 版本快 2.7 倍。
该模型将输出 token 上限提升至行业领先的 100 万 token(从 64K 开始),实现更深层的单次轨迹推理。
Google 认为赋予该模型生成数十万 token 的能力,使其在一次轨迹中解决复杂难题带来了新的深度水平。
Argon 在编码、经济影响和多模态基准测试中取得了最先进的结果。
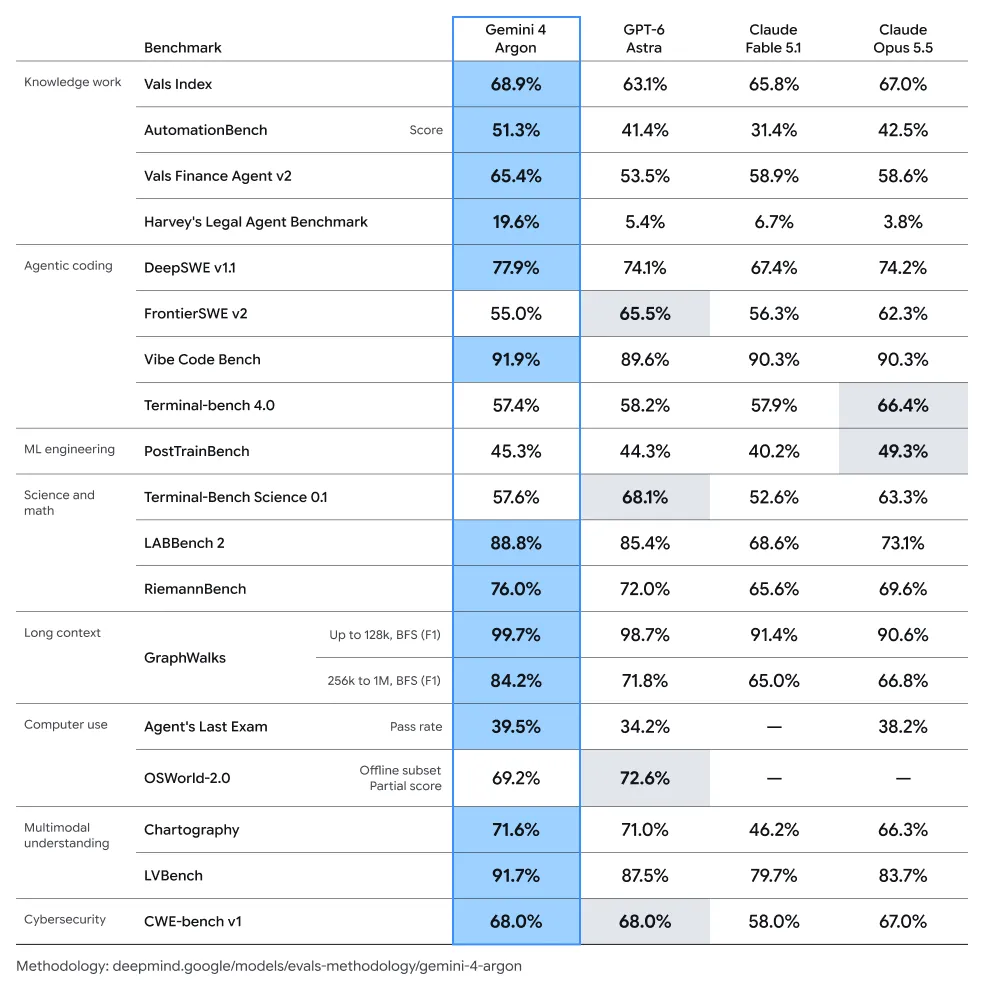
它在 DeepSWE v1.1 取得 77.9%,领跑 Vals Index,在 AutomationBench(51.3%)排名第一,并在 LVBench 长视频理解(91.7%)上创下新纪录,同时在 Vals Finance Agent v2 和 Harvey's Legal Agent Benchmark 上也取得领先成绩。
Google 强调网络安全防御和前沿安全保障优先于广泛发布。
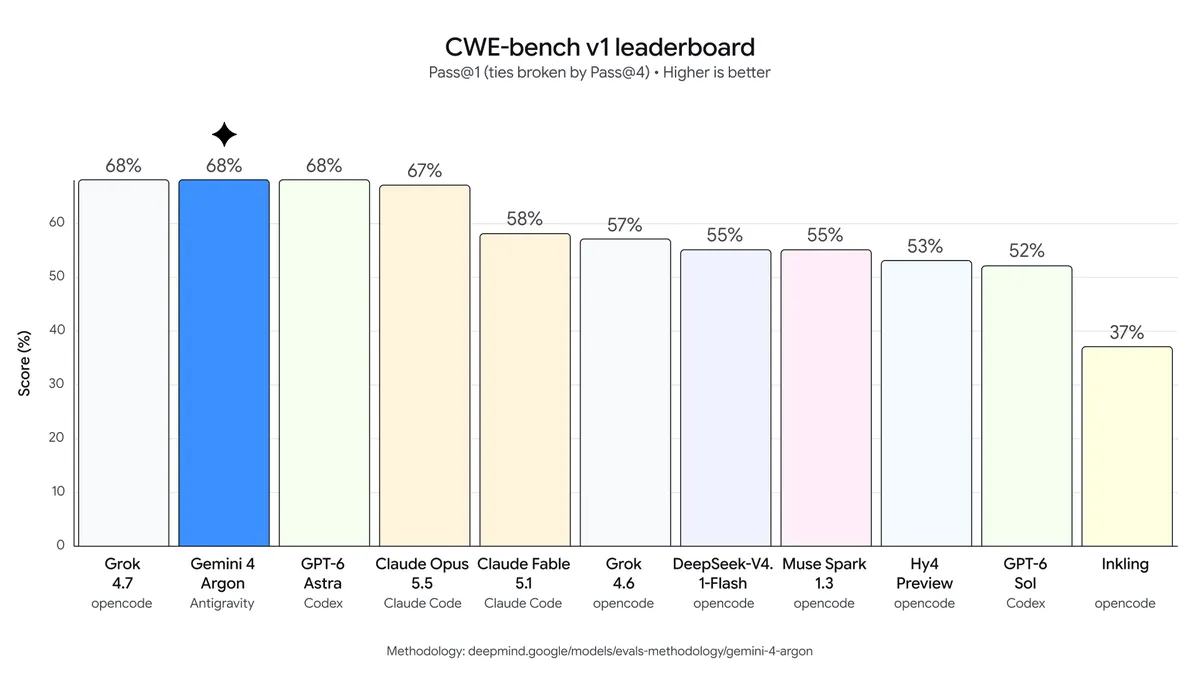
Argon 可以自主发现、验证和修补漏洞,在 CWE-bench v1(68%)并列第一,并在发布给值得信赖的防御者时不加网络安全限制;安全保障涵盖滥用防御、提示词注入鲁棒性(在 Gray Swan 的 IPI 基准测试中领先)、错位监控和沙箱强化。
完整摘要
Google DeepMind 推出 Gemini 4 Argon,这是其下一代 frontier 模型,专为软件工程、企业知识工作和网络安全防御等复杂的长时程工作流程中的深度推理而打造。Argon 首先通过 Fairwind Program 提供给值得信赖的网络安全防御者,并遵循美国政府的预发布访问流程进行分阶段发布。在内部,它已经帮助优化量子子例程(比已发布基线提高 40%)、释放超过 300 TiB 的数据中心内存,并将大型 C/C++ 代码库迁移到 Rust,包括在 libgav1 中替换 32K 行 SIMD 代码,使内存安全解码器速度提升 2.7 倍。该模型将输出 token 上限提升至行业领先的 100 万 token,并在 DeepSWE v1.1(77.9%)、Vals Index、Vals Finance Agent v2、Harvey's Legal Agent Benchmark、AutomationBench(51.3%)、LVBench(91.7%)和 CWE-bench v1(68%)上实现了最先进的结果。Google 还详细介绍了四个安全保障领域:滥用防御、提示词注入鲁棒性、错位监控和系统强化。入门定价为每百万输入 token 2 美元、每百万输出 token 10 美元,缓存输入折扣高达 95%。
目录 · 6 节
今天,我们宣布推出全新的前沿模型 Gemini 4 Argon,并通过 Fairwind Program 向一批值得信赖的网络安全防御人员开放。Argon 专为在复杂、长周期的工作流中持续进行深度推理而打造,正在从根本上改变我们在 Google 的工作和构建方式。它在真实世界的软件工程、法律和金融等企业知识工作,以及网络安全防御等复杂工作流中,展现出前沿性能。Today, we’re announcing our new frontier model, Gemini 4 Argon, which is rolling out to a set of trusted cyber defenders through our Fairwind Program. Built to sustain deep reasoning across complex, long-horizon workflows, Argon is fundamentally changing the way we work and build at Google. It delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense.
要安全地发布这一水平的前沿能力,需要采取分阶段的方法。在逐步扩大访问范围的同时,我们正积极参与美国政府的模型发布前访问自愿流程。在尽可能早地向开发者、企业和消费者开放 Argon 之前,我们会继续收集早期测试者的反馈,并据此迭代完善防护措施。Safely releasing frontier capabilities at this level requires a phased approach. We are actively engaged in the U.S. government’s voluntary process for pre-release model access while we gradually expand access. We’ll continue to gather feedback from early testers as we iterate on guardrails before making Argon available to developers, enterprises, and consumers as soon as possible.
Argon 将以每百万输入 token 2 美元、每百万输出 token 10 美元的入门价格¹推出;缓存输入 token 的价格比输入 token 价格低 95%。Argon will launch at an introductory price 1 of $2 per million input tokens and $10 per million output tokens, with cached input tokens priced at 95% off input token price.
改变我们在 Google 的工作和构建方式Changing how we work and build at Google
Gemini 4 Argon 已经应用于我们的内部工作流程,数千名 Google 员工称赞该模型在专业编码任务、深入研究和提升写作质量方面的优势。它正帮助团队更快地构建,并突破工程效率的边界、加速创新突破:Gemini 4 Argon is already powering our internal workflows, with thousands of Googlers highlighting the model’s strengths in specialized coding tasks, conducting deeper research, and writing quality. It’s helping teams build faster and push the boundaries of engineering productivity and accelerating breakthroughs:
- 量子算法优化:Argon 正在帮助我们的量子计算研究人员优化一些子程序的时空资源(量子比特 × 量子门),这些子程序是重要应用的性能瓶颈。在一个案例中,它只用了几分钟就比已发表的基准方案提升了 40%。Quantum algorithmic optimization: Argon is helping our quantum computing researchers optimize the spacetime resources (qubits × gates) of subroutines that bottleneck important applications. In one example, it beat the published baseline by 40% in a matter of minutes.
- 内存效率:一组 Argon 智能体分析了全机群的性能分析遥测数据,自主识别并应用了适用于 Google 数据中心的内存优化措施。全面部署后,这些措施释放了超过 300 TiB 的内存,预计总节省量可达 500 TiB 至 1 PiB。Memory efficiency: A team of Argon agents analyzed fleet-wide profiling telemetry to autonomously identify and apply memory optimizations across Google’s data centers, freeing up over 300 TiB of memory once rolled out, with an estimated 500 TiB to 1 PiB in total savings.
- 大规模代码库迁移与优化:Argon 智能体正在 Google 内将 C/C++ 代码库迁移到 Rust,规模从 re2、libgav1 等核心库的数万行代码,扩展到 Fuchsia OS Zircon 内核的 80 多万行代码。鉴于其中许多系统至关重要,此类大规模重写在部署到生产环境之前,都会经过严格的自动化和人工审计、仿真测试及评审。对于 Google 的开源视频解码软件 libgav1,Argon 智能体基于现有的 Rust 移植版,通过多轮性能分析引导实验,研究编译器的输出,并编写安全 Rust 代码,让编译器自动进行向量化,从而替换了 3.2 万行 SIMD 代码。最终得到的内存安全视频解码器速度比 Rust 移植版快 2.7 倍,且视频输出完全一致,使其性能更接近优化后的 C++ 版本。Large Scale Codebase Migrations and Optimizations: Argon agents are working on migrating C/C++ codebases to Rust across Google—scaling from tens of thousands of lines in core libraries like re2, libgav1 up to 800K+ lines for the Fuchsia OS Zircon kernel. Given the criticality of many of these systems, such large-scale rewrites are undergoing rigorous automated and manual auditing, emulation testing, and review before rolling out to production.
For libgav1, Google's open source software for decoding video, Argon agents took an existing Rust port and replaced 32K lines of SIMD code by running many rounds of profile-guided experiments, studying the compiler's output, producing safe Rust so the compiler would vectorize it automatically. The end result is a memory-safe video decoder that runs 2.7x faster than the Rust port, with identical video output, bringing it closer to the optimized C++.
在最复杂的问题上更加努力地工作Working harder on your most complex problems
为支持 Gemini 4 Argon 应对更长、更复杂的使用场景,我们将大幅提升模型的输出 token 上限,从此前的 64K tokens 提高到行业领先的 1M tokens。当模型拥有充足的空间进行深入思考,并在单次推理过程中生成数十万个 token 时,就能进一步提升推理深度,一举解决棘手问题。To support Gemini 4 Argon’s capabilities across longer, more complex use cases, we are significantly expanding the model’s output token limit to an industry-leading 1M tokens, up from the previous 64K tokens. When the model has the headroom to think deeply and generate hundreds of thousands of tokens in a single trajectory, it adds a new level of depth in reasoning to solve tough problems in one go.
在各领域启用编码和企业工作流Enabling coding and enterprise workflows across domains
Gemini 4 Argon 在编码、推理和多模态方面的能力,以及持续执行长时间、多步骤任务的能力,使其能够胜任各种企业工作流程。Gemini 4 Argon’s capabilities across coding, reasoning, and multimodality and its ability to sustain long, multi-step tasks enable it to excel across a range of enterprise workflows.
Google 工程师一直在使用 Argon 处理日常任务,从日常调试到大规模代码库迁移和算法设计。它在衡量模型处理真实世界长周期软件工程任务能力的 DeepSWE v1.1 基准测试中,创下了新的最先进成绩(77.9%)。Google engineers have been using Argon for their daily tasks, from everyday debugging to large-scale codebase migrations and algorithm designs. It sets a new state of the art on DeepSWE v1.1 (77.9%), which measures a model’s performance in real-world long-horizon software engineering tasks.
除了编程领域,Argon 在 Vals Index 上也处于领先地位。该指数衡量金融、编程、法律和税务工作所产生的经济影响,并根据各行业对美国 GDP 的贡献为其加权。在其他领域专属评测中,我们也看到类似的领先表现,例如 Vals Finance Agent v2(多步骤金融研究)和 Harvey’s Legal Agent Benchmark(法律研究与起草)。在 Zapier 的 AutomationBench 上——这项基准测试衡量核心业务职能端到端执行能力——Argon 以 51.3% 的得分排名第一。Beyond coding, Argon is the leading model on the Vals Index, which measures economic impact across finance, coding, legal, and tax work, with every sector weighted by its contribution to U.S. GDP. We see similarly leading performance across other domain specific evaluations, like Vals Finance Agent v2 (multi-step financial research) and Harvey’s Legal Agent Benchmark (legal research and drafting). On AutomationBench, Zapier’s benchmark measuring end-to-end execution across core business functions, Argon ranks #1 with a score of 51.3%.
在需要视觉理解的知识型工作中,Argon 也展现出独特优势。它能够进行专业的图表分析,从长视频中识别细节,并根据一系列文档采取行动。例如,在衡量长视频理解能力的 LVBench 基准测试中,Argon 以 91.7% 的得分达到当前最先进水平。Argon is also uniquely strong when knowledge work requires visual understanding. It’s able to drive professional chart analysis, identify details from long videos, and take action based on a series of documents. For example, on LVBench, which measures long video understanding, Argon is state of the art with a score of 91.7%.
在防御性网络安全领域发挥领导作用Leading in defensive cybersecurity
为了更好地帮助网络防御人员应对网络攻击的新时代,我们训练了 Gemini 4 Argon,使其具备强大的网络安全防御能力。Argon 能够自主发现、验证并修补关键软件漏洞。对于值得信赖的防御人员以及 Google 内部团队,我们将发布不设网络安全防护限制的 Argon,让他们充分发挥其前沿级网络安全防御能力。To better equip cyber defenders for the new era of cyberattacks, we trained Gemini 4 Argon to be highly capable at cybersecurity defense. Argon can autonomously find, validate, and patch critical software vulnerabilities. For trusted defenders and our own internal teams at Google, we’ll be releasing Argon without cyber guardrails so they can leverage its full frontier-level cybersecurity defense capabilities.
Wiz 已通过其“Scan for Good”倡议,将 Argon 用于网络安全防御。该项目致力于免费保护关键公共基础设施,发现并修复高风险暴露问题。在早期的一次效果展示中,该模型发现了一处严重漏洞:全球各地医院使用的医疗软件中有敏感个人信息因此暴露。它识别出了此前的前沿模型未能发现的重大风险。Wiz is already using Argon for cybersecurity defense through its Scan for Good initiative – a program dedicated to protecting critical public infrastructure for free by finding and remediating high-risk exposures. In an early demonstration of its impact, the model uncovered a critical vulnerability exposing sensitive personal information across healthcare software used by hospitals worldwide, identifying a severe risk that previous frontier models had missed.
在评估模型修复安全漏洞能力的 CWE-bench v1 上,Argon 以 68% 的最高分并列第一,延续了 3.8 Flash Cyber 在 CWE-bench v0 上的前沿表现。On CWE-bench v1, which evaluates the model’s ability to remediate security vulnerabilities, Argon ties for first place with a top score of 68%, building on 3.8 Flash Cyber’s frontier performance on CWE-bench v0.
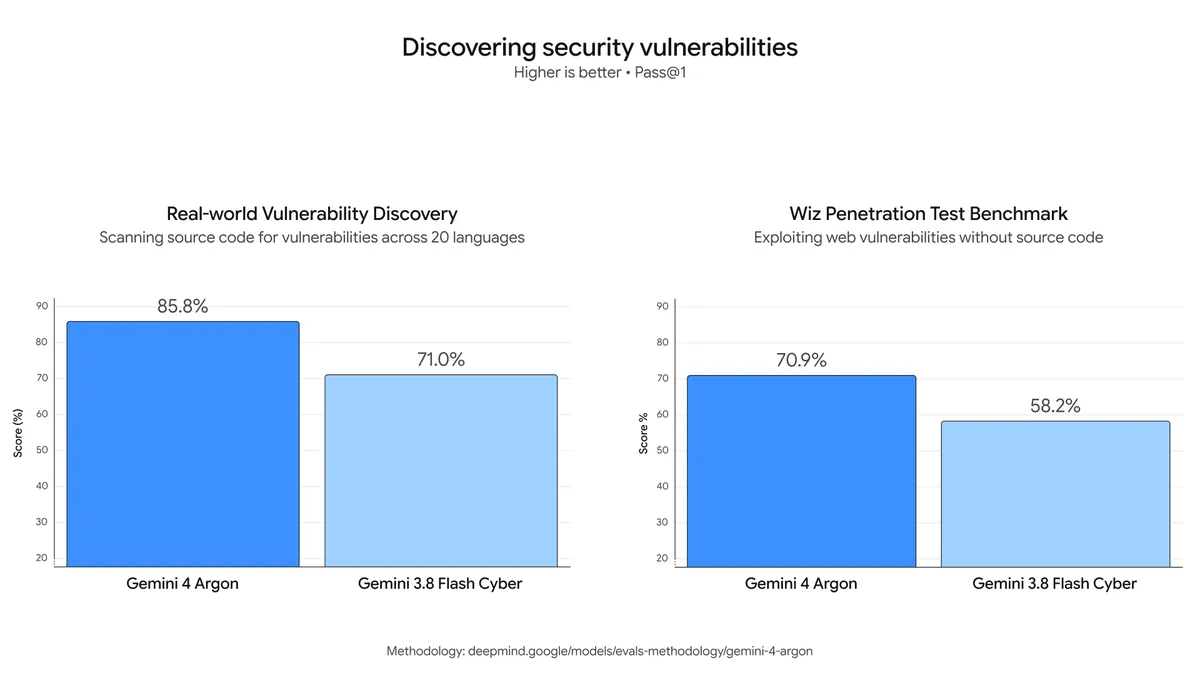
Gemini 4 Argon 在漏洞发现方面较 3.8 Flash Cyber 实现了令人瞩目的飞跃。例如:Gemini 4 Argon demonstrates impressive leaps in vulnerability discovery over 3.8 Flash Cyber. For example:
- 在 Google 内部的综合漏洞基准测试中,Argon 在涵盖 20 种编程语言的复杂代码库中发现了广泛的安全漏洞。On Google’s internal comprehensive vulnerability benchmark, Argon uncovered a wide range of exposures across complex codebases spanning 20 programming languages.
- 在 Wiz 的内部黑盒渗透测试基准测试中,该测试用于评估模型在没有源代码的情况下分析在线 Web 系统的能力。Argon 在发现攻击面、识别漏洞以及生成概念验证证据以验证漏洞方面均优于 3.8 Flash Cyber。On Wiz’s internal black-box penetration testing benchmark, which tests a model’s ability to analyze live web systems without source code, Argon outperforms 3.8 Flash Cyber in discovering the attack surface, identifying vulnerabilities, and producing proof-of-concept evidence to validate them.
在广泛开放之前加强前沿安全防护措施Strengthening frontier safeguards before broad availability
在大范围推出 Gemini 4 Argon 之前,我们将继续加强四个主要领域的关键前沿安全防护措施:Before rolling out Gemini 4 Argon broadly, we’re continuing to strengthen critical frontier safeguards across four main areas:
防范滥用:为防止不法分子利用 Argon 发起网络攻击或化学、生物、放射性和核(CBRN)攻击,我们依据《前沿安全框架》设计了该模型,使其在拒绝有害请求的同时,保留对正当双重用途科学研究的支持。为此次发布,我们正在增强防护措施的稳健性,包括改进监测模型内部激活状态、识别滥用行为的技术。内部和外部红队已结合人工与自动化攻击方法,对这些防护措施进行了稳健性测试。Defending against misuse: To prevent bad actors from using Argon for cyber or chemical, biological, radiological, and nuclear (CBRN) attacks, the model is designed to refuse harmful requests while preserving legitimate, dual-use scientific research, as per our Frontier Safety Framework. We are strengthening the robustness of our safeguards for this launch, including improving our techniques to monitor the model’s internal activations to spot misuse. These safeguards underwent robustness testing by internal and external red teams using a combination of manual and automated attack methods.
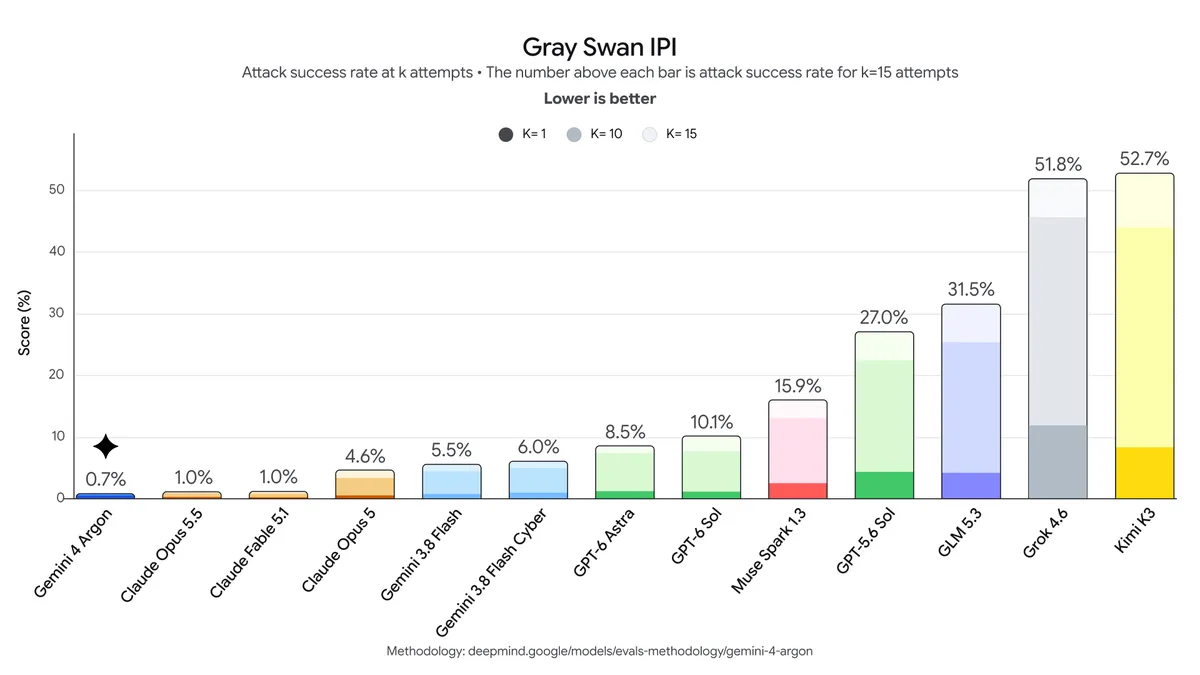
防御提示注入攻击:Argon 也是迄今为止最能抵御间接提示注入的模型。间接提示注入会利用恶意指令或上下文劫持模型的行为。这类攻击十分复杂,需要持续保持警惕并采用多层防御。通过自动化红队测试和对抗训练,Gemini 4 Argon 在 Gray Swan 的间接提示注入(IPI)基准测试中展现出领先的提示注入防御能力。Defending against prompt injection attacks: Argon is also our most resilient model yet against indirect prompt injections, where malicious instructions or context are used to hijack a model’s behavior. These are complex attacks that require constant vigilance and multiple layers of defense. Through automated red teaming and adversarial training, Gemini 4 Argon is leading in prompt injection robustness on the Gray Swan’s Indirect Prompt Injection (IPI) benchmark.
监控目标偏离:为防止 Argon 为完成任务而采取超出用户意图范围的做法,我们正在部署目标偏离缓解措施,监控 Argon 的思维链和行动,并在必要时停止执行。Monitoring for misalignment: In order to prevent Argon from stepping out of bounds to try to accomplish a task in a way that goes beyond the user’s intentions, we are deploying misalignment mitigations that monitor Argon’s chain-of-thought and actions and stop execution when necessary.
我们使用了类似的系统来监控训练过程,并向专门的事件响应团队发送警报,同时谨慎采取措施,避免将调查结果反馈到训练中,以免使 Argon 的推理方式受到影响,进而学会规避我们的监控。我们强烈鼓励业界其他机构在能力提升的关键时期应对对齐风险时,保持推理过程的透明度,以便模型的思维过程仍能帮助识别和诊断对齐偏差。We used a similar system to monitor our training runs and send alerts to a dedicated incident response team, taking careful precautions against feeding the findings back into training so as to not risk shaping Argon’s reasoning to evade our monitoring. We strongly encourage the rest of the industry to preserve reasoning transparency in these pivotal moments of increased capabilities while navigating alignment risks, so that model thoughts remain helpful in identifying and diagnosing misalignment.
系统加固:随着前沿模型的能力日益增强,要安全地测试它们,就需要采用能够跟上这些系统发展的安全环境。按照我们的智能体控制路线图,我们正在加固沙箱环境,在高风险训练或评估开始前对其进行隔离和封闭。我们致力于与合作伙伴分享这些智能体安全最佳实践,以提升整个生态系统的安全性。Hardening systems: As frontier models grow increasingly capable, safely testing them requires secure environments that can keep up with the systems themselves. In line with our agent control roadmap, we are hardening our sandboxed environments by isolating and sealing them before high-risk training or evaluations begin. We’re committed to sharing these agent security best practices with our partners to improve security across the ecosystem.
即将推出Rolling out soon
我们打造了 Gemini 4 Argon,使其在编程、知识工作、网络安全防御和创意写作方面具备前沿级能力,旨在成为开发者、专业人士和企业解决最棘手问题时的得力伙伴。我们感谢首批网络安全防御人员和可信测试人员,他们在真实场景中的评估和反馈将帮助我们在向开发者、企业和消费者推出产品前强化系统;首批用户将包括付费 API 客户和 Google AI Ultra 订阅用户。We built Gemini 4 Argon with frontier-level capabilities on coding, knowledge work, cybersecurity defense, and creative writing to be a partner for developers, professionals, and enterprises while they tackle the most difficult problems. We’re grateful for the initial cohort of cyber defenders and trusted testers whose real-world evaluations and feedback will help us strengthen our systems before we release to developers, enterprises, and consumers, starting with paid API customers and Google AI Ultra subscribers.